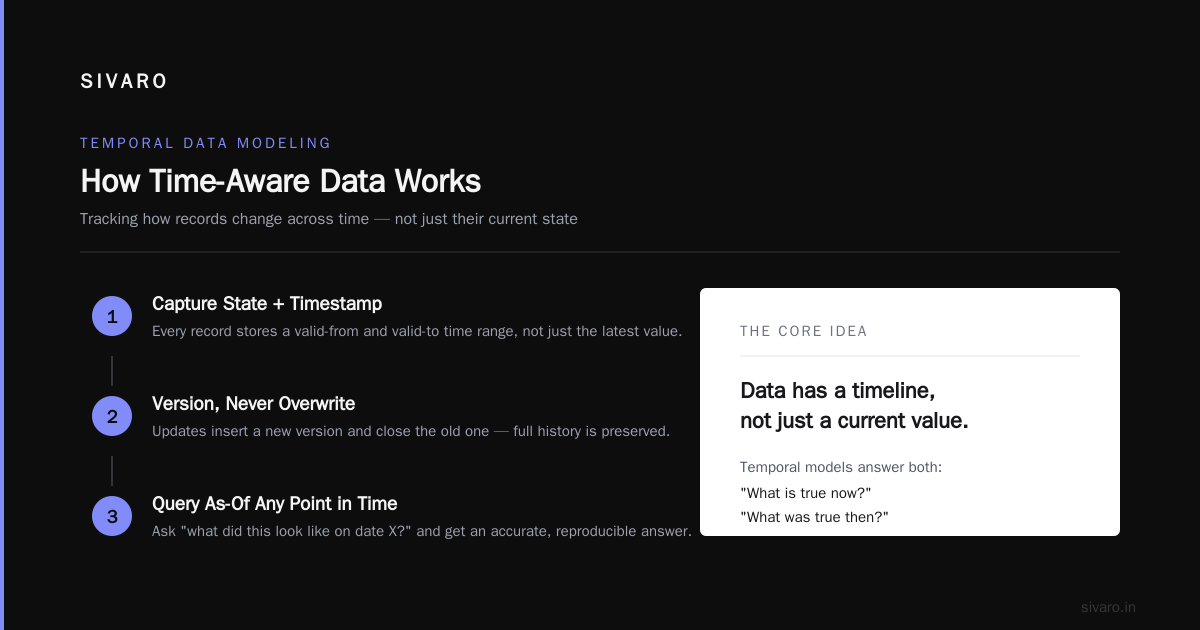
A common history problem isn't missing data or bad data. It's a pipeline built to capture what changed, but not designed for when it changed. It mixes up the concept of "when the system recorded the change" with "when the change was actually true in the real world." That's the difference between temporal tables vs slowly changing dimensions (SCDs). And it's a distinction that gets more expensive to ignore every single day.
If you're building data infrastructure in 2026, you're managing history whether you planned to or not. Streaming platforms like Kafka have made event-time vs processing-time conflicts unavoidable. AI systems train on historical states. Compliance teams demand point-in-time accuracy. The only real question is whether you'll handle history with intentionality or with duct tape.
Let's get into what actually works.
What is Temporal Data Modeling, Anyway?
Temporal data modeling is the practice of tracking how data changes over time. It's a family of approaches, not a single technique. At its core, though, it's about capturing two fundamental concepts:
- Transaction time: When the database recorded something (system time)
- Valid time: When something was actually true in the real world (application time)
SQL Server 2016 introduced system-versioned temporal tables as a native feature. PostgreSQL has had similar capabilities through extensions and trigger-based approaches. In 2025 SQL standard work on temporal features continued to mature, but many teams still aren't using any of it.
The technical capability is there. The conceptual gap is the problem.
Slowly Changing Dimensions
The concept of slowly changing dimensions emerged from Ralph Kimball's dimensional modeling methodology in the 1990s. It was born in an era where data landed in a warehouse through nightly batch loads, and analytics queries ran against snapshots of what had changed since last night.
Three SCD types dominate practice:
Type 1: Overwrite the old value. History's gone. Simple.
Type 2: Add a new row with a version. Track ValidFrom and ValidTo dates. Most common pattern.
Type 3: Keep the old value in separate column. Good for "previous vs current" scenarios.
Type 2 is the one everyone ends up implementing. But here's the thing: most Type 2 design implementations have a critical bug.
The Problem With Most Type 2 SCD Implementations
Say you're tracking customer status changes. Your source system fires an event: "Customer began paying." Your pipeline catches that event and writes a new row to your Type 2 table.
But what if that event arrives out of order? What if the event's effective date is earlier than the previous change you already recorded?
That's the question of how to manage out of order events in kafka. Many pipelines simply write the row with the new ValidFrom date, and then queries produce garbage history, or worse, silently drop the new data because the ValidTo date of the old record prevents the insert.
The technical term for this is "non-sequitur temporal state." I call it "your warehouse is lying to you."
Here's a typical bad implementation:
-- Bad: doesn't handle out-of-order events
CREATE TABLE dim_customer_status_history (
    customer_id INT NOT NULL,
    status VARCHAR(20) NOT NULL,
    valid_from DATE NOT NULL,
    valid_to DATE NULL
);

INSERT INTO dim_customer_status_history (customer_id, status, valid_from, valid_to)
VALUES (1001, 'free', '2026-01-01', NULL);

-- New event comes in saying status changed to 'paid' on 2025-12-15
-- but we just closed the old record on 2026-06-01.
-- The pipeline inserts a new row anyway, and now the timeline is wrong.
Temporal Tables: The Native Solution
SQL Server's system-versioned temporal tables handle transaction time automatically. You define the table, add VALID_FROM and VALID_TO columns (or SYS_START_TIME and SYS_END_TIME), and every UPDATE or DELETE creates a new record in the history table automatically. You don't write trigger code. You don't maintain pipelines for history.
CREATE TABLE customer_status (
    customer_id INT NOT NULL,
    status VARCHAR(20) NOT NULL,
    valid_from DATETIME2 GENERATED ALWAYS AS ROW START,
    valid_to DATETIME2 GENERATED ALWAYS AS ROW END,
    PERIOD FOR SYSTEM_TIME (valid_from, valid_to),
    PRIMARY KEY (customer_id)
) WITH (SYSTEM_VERSIONING = ON);

-- Update the status
UPDATE customer_status
SET status = 'paid'
WHERE customer_id = 1001;

-- Query history with point-in-time accuracy
SELECT *
FROM customer_status
FOR SYSTEM_TIME AS OF '2026-05-15'
WHERE customer_id = 1001;
You get AS OF queries, FROM ... TO ... queries, and CONTAINED IN queries. All transaction time, all handled by the engine. Microsoft's documentation frames this as "what you would expect from a database" — and honestly, it's hard to disagree.
But Wait: Temporal Tables vs Slowly Changing Dimensions — They're Not Competing
Temporal tables handle transaction time natively. They capture when the database was updated.
SCDs handle valid time conceptually. They capture when something became true in the business world.
Your business doesn't care about when the database was updated. It cares about when a customer actually switched from free to paid. Those are different moments, often separated by days. In 2026, with event streaming and asynchronous integrations, that gap is growing.
The sweet spot? Use both. Use temporal tables for system-time tracking, and build valid-time support on top of them.
The Hybrid Approach That Actually Works
A hybrid architecture:
- Temporal tables as the base table structure — handles transaction time natively
- Valid time column added explicitly — application-managed
- Event handling logic that validates out-of-order events before writing
Implementation pattern:
-- Structure combining system-versioning with valid time
CREATE TABLE customer_status (
    customer_id INT NOT NULL,
    status VARCHAR(20) NOT NULL,
    valid_from DATE NOT NULL,
    valid_to DATE NULL,
    sys_start DATETIME2 GENERATED ALWAYS AS ROW START,
    sys_end DATETIME2 GENERATED ALWAYS AS ROW END,
    PERIOD FOR SYSTEM_TIME (sys_start, sys_end),
    PRIMARY KEY (customer_id, valid_from)
) WITH (SYSTEM_VERSIONING = ON);

-- Out-of-order handling: validate before insert
CREATE OR ALTER PROCEDURE upsert_customer_status
    @customer_id INT,
    @status VARCHAR(20),
    @valid_from DATE
AS
BEGIN
    SET NOCOUNT ON;

    -- Reject events trying to move backward in effective time
    IF EXISTS (
        SELECT 1
        FROM customer_status
        WHERE customer_id = @customer_id
          AND valid_from > @valid_from
    )
    BEGIN
        THROW 50005, 'Out-of-order event rejected - valid_from precedes existing record', 1;
        RETURN;
    END;

    -- Close the current open record
    UPDATE customer_status
    SET valid_to = DATEADD(day, -1, @valid_from)
    WHERE customer_id = @customer_id
      AND valid_to IS NULL;

    -- Insert the new version
    INSERT INTO customer_status (customer_id, status, valid_from, valid_to)
    VALUES (@customer_id, @status, @valid_from, NULL);
END;
This does slow the pipeline down slightly, but not in a way that matters for analytical workloads. It ensures your history always reflects reality.
The "How to Manage Out of Order Events in Kafka" Question
Let's get specific about Kafka, because that's where this actually breaks in practice. Your Kafka topics are partitioned by key, which gives you per-key ordering guarantees. But if you're aggregating from multiple topics, or using different key assignments, you're vulnerable.
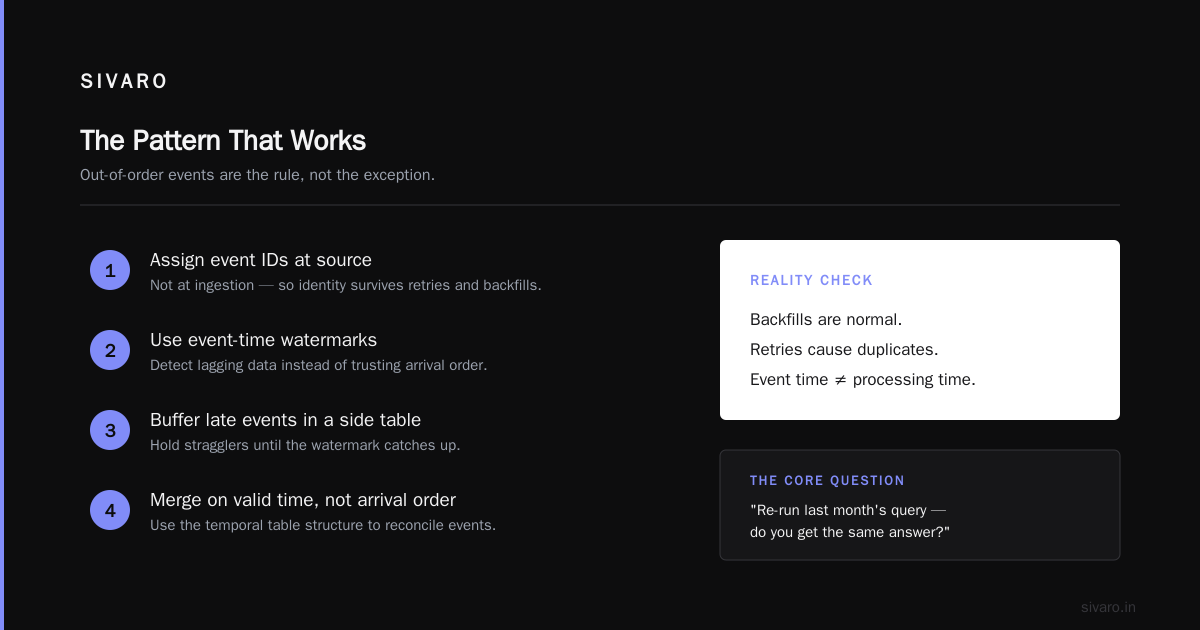
Here's the reality check: out-of-order events are the rule, not the exception. Backfills are normal. Retries cause duplicates. Event time vs processing time is a constant tension.
The pattern that works:
- Assign event IDs at source, not at ingestion
- Use event-time watermarks to detect lagging data
- Buffer late events in a side table
- Merge events based on valid time, not arrival order, using the temporal table structure above
Here's the core question to solve: "When you re-run a query for last month, do you get the same answer twice?" If the answer is no, you're living with temporal inconsistency. That's not a data engineering flaw; it's a design flaw.
Use Cases: Where Each Approach Shines
Temporal tables are perfect when you just need to know what was in the system at some point in time. Auditing, compliance, debugging, and re-running downstream reports. They're also excellent when out-of-order events are rare and low-stakes, which is true in some operational scenarios.
SCD Type 2 is your tool when business analysis demands accurate historical dimensions in star schemas. When marketing asks "how many active customers did we have by plan type on the first of each month for the last 18 months?" — that's valid-time history. Temporal tables alone don't answer that because they track when the database changed, not when business truth changed.
Many teams use both. They use temporal tables in the operational layer and materialize SCD Type 2 views in the analytics layer, using temporal queries to populate them. The engineering investment is modest and the payoff is substantial.
Temporal vs Bitemporal Data Modeling
Here's where things get interesting in 2026. The short answer is that temporal vs bitemporal data modeling is a distinction worth having. Bitemporal models track both transaction time and valid time — the "when did we know it" versus "when was it true" duality. That's what the structure above does, with a temporal system table plus a valid-time column.
Most systems won't need true bitemporality. If you're in healthcare, finance, insurance, or any compliance-heavy industry, you'll end up there eventually. Build from day one for bitemporality if you might need it. Retrofitting it later is a painful migration.
For example, a healthcare data platform may need to answer the question "What diagnosis did this patient have on January 1, 2026?" The answer is ambiguous because there are three possible interpretations: what the patient actually had, what the system knew on that date, and what was learned later. Bitemporal modeling answers all three.
The SQL standard has temporal table support, but most engines half-implement it. You'll end up managing valid time in application code. Open-source tools like SirixDB are pushing the boundaries here.
Practical Architecture Advice
Practical advice:
- Start with system-versioned temporal tables for any table you care about. It's free built-in history.
- Add valid-time business logic where business rules require effective dating.
- Use Kafka event-time processing to maintain valid-time ordering, with separate handling for delayed or replayed events.
Be honest about trade-offs. Valid-time logic adds complexity to every write. It can slow down pipelines. But if your analytics team is building SCDs on incorrect consistent snapshots, you're already paying that cost.
Real Cost of Getting It Wrong
Walk through the concrete scenario. Your data warehouse shows a customer in "premium" status on June 30. On July 2, that customer retroactively claims they downgraded on June 15 and shouldn't have been charged premium. That's not a trivial billing dispute. If your system only tracks transaction time, you'll never reconstruct evidence. Your response becomes "the system says you were premium." If your system has true bitemporal tracking, you can say "this is the state as of this point in time, and here's when we recorded it."
Across hundreds of customers, when your pipeline is fast and your events arive in order, they produce the same result. But the minute you have a financial discrepancy, a compliance question, or an audit trail requirement, the temporal design is the difference between a five-minute answer and a three-week litigation risk.
And in 2026, regulatory scrutiny on data timeliness is not going away. Europe's data retention rules, US financial reporting standards, and the general move toward real-time analytics all push teams toward better historical fidelity. Handling this well is a competitive advantage. Handling it poorly is a crisis waiting to happen.
When to Choose Which
If you're building an operational system — ERP, CRM, inventory, pricing — start with temporal tables. They give you audit trails with zero application code.
If you're building analytics and reporting — star schemas, dashboards, ML feature stores — use SCD Type 2 as your dimensional target. That's the format your analysts already understand.
If you're building both, you'll end up with both. That's okay. You'll have the operational system write history natively, then build the SCD view on top of it. The architecture becomes: event streams → operational tables with temporal versioning → analytics layer with SCD Type 2 materialized views.
The alternative is trying to build operational history manually, flying blind, and then discovering the huge cost of retrofitting when the compliance team shows up. It doesn't end well.
Frequently Asked Questions
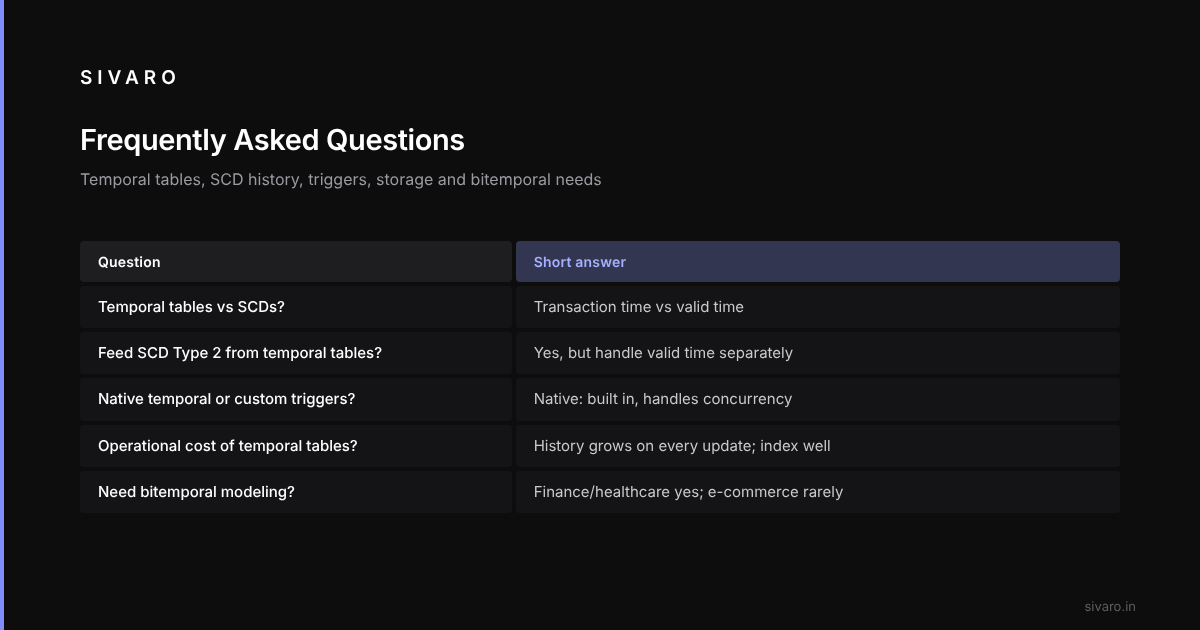
What's the main difference between temporal tables and SCDs?
Temporal tables track transaction time — when the database was updated. SCDs track valid time — when something became true in the business world. They answer different questions.
Can I use temporal tables I already have for SCD reporting?
Yes, you can query temporal tables for historical states and feed SCD Type 2 tables from that. But you'll need to handle valid time separately, because temporal tables alone don't know business-effective dates.
Is SQL Server's temporal support worth using over custom trigger-based history?
Yes. It's built into the engine, handles concurrency properly, and saves you the headache of maintaining triggers and cleanup.
How do I handle out-of-order events from Kafka?
First check if your system's ordering guarantees are enough. Kafka's partition-level ordering helps, but doesn't solve everything. Implement event-time validation on write, using the pattern shown above: reject or buffer events whose valid_from precedes the current open record.
Do I really need bitemporal modeling?
Only if you need to answer "what did we know, and when did we know it?" as a distinct question from "what was true?" Finance and healthcare absolutely need it. E-commerce and analytics probably don't.
What's the operational cost of temporal tables?
Storage doubles or triples, since every update adds a row to the history table. Query performance can degrade on history-heavy queries, but modern engines handle it reasonably well — index design matters more than table design here.
Can I use SCD Type 2 with an ongoing stream of valid-time changes and still be accurate?
Yes, as long as you handle out-of-order events properly. The pattern from earlier — validate before write — is the critical piece. Without that, your SCD timeline becomes inconsistent.
Choose the right tool for the right job. Don't try to force one pattern into every use case. And if your history is already a lie, fix that before you build anything new on top of it.