The biggest mistake? Confusing fine‑tuning with post‑training. They sound similar. They’re not. One teaches new knowledge. The other teaches new behavior. Mix them up and you burn money.
Here’s what I’ll cover: what each actually is, when to use which, costs, tooling in 2026, a decision framework, and where most people get it wrong.
The Real Difference: Supervised Fine‑Tuning vs Alignment Post‑Training
Let’s define terms.
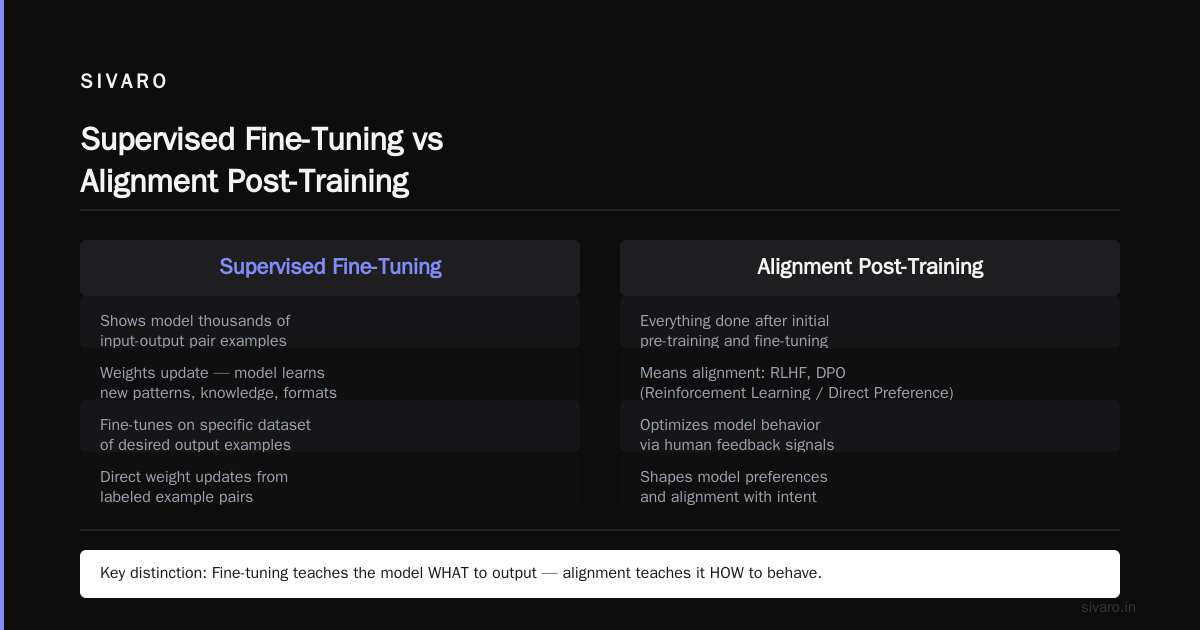
Fine‑tuning (usually Supervised Fine‑Tuning, SFT) means taking a pre‑trained base model and training it further on a specific dataset of input‑output pairs. You show the model thousands of examples of exactly what you want it to produce. The weights update. The model learns new patterns, new knowledge, new formats.
Post‑training is the umbrella term for everything done after the initial pre‑training and after standard fine‑tuning. In practice it means alignment: RLHF (Reinforcement Learning from Human Feedback), DPO (Direct Preference Optimization), or other techniques that shape the model’s behavior — making it more helpful, less toxic, or better at following instructions.
At first I thought this was a branding problem — turns out it’s a fundamental architectural choice. SFT shifts the model’s distribution. Post‑training constrains it.
A 2024 paper from ScienceDirect ( Fine‑Tuning Large Language Models for Specialized Use ) showed that fine‑tuning on domain data without subsequent alignment produced models that were more accurate on domain tasks but less safe. The alignment step recovered safety without sacrificing domain accuracy — but only if you had enough preference data.
That paper changed how I think about the pipeline. You don’t just pick one. You sequence them.
When You Should Fine‑Tune (And When You Shouldn’t)
Most people think fine‑tuning fixes everything. They’re wrong.
Fine‑tuning excels when:
- You need the model to internalize a large corpus of proprietary knowledge (e.g., 10,000 internal legal documents).
- You need a very specific output structure — like structured JSON with custom fields that prompt engineering keeps breaking.
- You’re deploying a small model (3B–8B params) and need it to punch above its weight on a narrow task.
But here’s the contrarian take: most production problems are not solved by fine‑tuning. They’re solved by better retrieval, better prompt design, or better evaluation.
The RAG vs Fine‑Tuning in 2026 decision framework from Winder.ai is brutally honest: if your task depends on up‑to‑date information or facts that change, RAG beats fine‑tuning every time. Fine‑tuning freezes knowledge. RAG queries live data.
Don’t fine‑tune facts. Fine‑tune behaviour and format.
Post‑Training: The Hidden Lever for Production Quality
If fine‑tuning is the engine, post‑training is the steering wheel.
Alignment techniques like DPO and RLHF don’t teach the model new facts. They teach it how to answer. Tone, structure, safety, refusal thresholds.
In 2025, the dominant post‑training method shifted from PPO (the original RLHF algorithm) to DPO. Why? DPO is simpler — no separate reward model training, no PPO instability. It directly optimizes the policy on pairs of preferred and dispreferred responses.
Here’s a minimal DPO training snippet using HuggingFace TRL (2026 version):
from trl import DPOTrainer
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

model = AutoModelForCausalLM.from_pretrained("mistral-7b-v0.3")
ref_model = AutoModelForCausalLM.from_pretrained("mistral-7b-v0.3")
tokenizer = AutoTokenizer.from_pretrained("mistral-7b-v0.3")
tokenizer.pad_token = tokenizer.eos_token

trainer = DPOTrainer(
    model=model,
    ref_model=ref_model,
    tokenizer=tokenizer,
    train_dataset=preference_dataset,  # list of {"prompt", "chosen", "rejected"}
    beta=0.1,                          # KL penalty strength
    max_length=1024,
    args=TrainingArguments(
        output_dir="./aligned-mistral",
        per_device_train_batch_size=4,
        num_train_epochs=1,
        logging_steps=10,
        save_steps=200,
    ),
)
trainer.train()
That’s it. 50 lines and you have a model that prefers helpful, safe responses over hallucinated ones.
The LLM Fine‑Tuning Best Practices: Complete Guide for 2026 recommends using DPO as a “finishing touch” after any SFT run.
Cost and Compute: Fine‑Tuning Is Cheaper Than You Think, Post‑Training Isn’t
Let’s talk money.
In 2026, LoRA fine‑tuning is dirt cheap. A full‑parameter fine‑tune on a 70B model? Still expensive. But LoRA on 8B? You can do it on a single A100 80GB for a few hundred dollars.
Post‑training is a different beast. DPO and RLHF need two models (policy and reference) plus preference data that requires human or synthetic annotation. A single RLHF run on a 70B model can cost $2,000–$5,000 in GPU time. And you often need multiple iterations.
But the hidden cost is data. Good preference data is expensive. You need humans to compare outputs, or a very solid automated evaluator (which itself costs money to build and maintain).
If you’re running a Mac Studio, you already know the pain. Fine‑tune LLM on Mac Studio problems are real. The M2 Ultra has 128GB unified memory — great for inference, terrible for training. LoRA on 7B models works, but you hit memory walls fast. Training a 13B model? Forget it. We recommend using cloud instances for fine‑tuning, even for prototyping. The Fine‑Tune Local LLMs 2026 | Practical Guide has a good chart on what works on Apple Silicon. Spoiler: only up to 8B with QLoRA.
Tooling in 2026
Tooling has matured fast. In 2024 you had to glue together five scripts. Now there are turn‑key solutions.
For overviews, see The Best 5 LLM Fine‑Tuning Tools of 2026 and Fine‑Tune Any LLM 2026: 10 Tools Tested, Cheapest Wins.
For fine‑tuning:
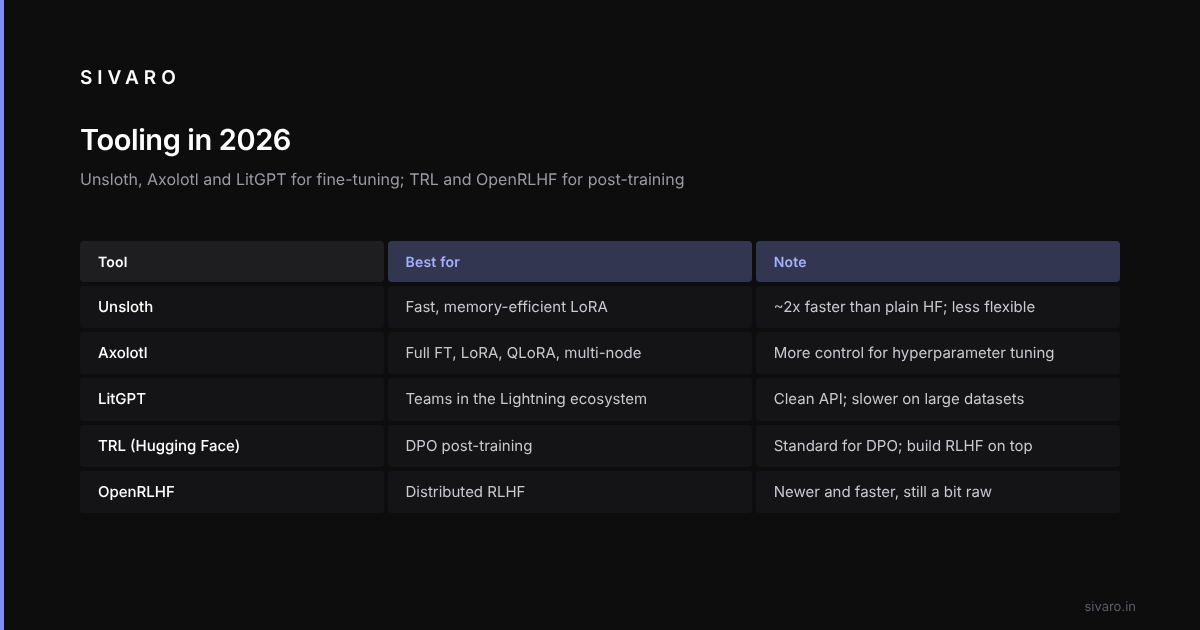
- Unsloth — fastest trainer for LoRA. 2x faster than pure HuggingFace. Memory efficient. The only downside: less flexible for custom training loops.
- Axolotl — more control. Supports full fine‑tune, LoRA, QLoRA, even multi‑node training. Useful when you need to experiment with hyperparameters.
- LitGPT — good if you’re already in the Lightning ecosystem. Clean API, but slower on large datasets.
For post‑training:
- TRL (HuggingFace) — standard for DPO. For RLHF, you can build on top of TRL with a custom reward model.
- OpenRLHF — newer, faster, supports distributed RLHF. Still a bit raw.
Cheapest wins? The Techsy.io article tested 10 tools. The winner for price/performance was Unsloth + a rented A100 at $1.10/hr.
The Open Source Question: Best Open Source LLM to Fine Tune for Production
You want an open‑source model that you can fine‑tune, control, and serve. Here’s my ranking for August 2026:
- Llama‑3.2‑8B (Meta) — the sweet spot. Great base, large community, many fine‑tuned variants to bootstrap from. If you need smaller, the 3.2‑1B is surprisingly capable after fine‑tuning.
- Mistral‑7B‑v0.3 — still strong, especially for code. Slightly less safety aligned out of the box, but DPO fixes that.
- Phi‑3‑medium‑4k (Microsoft) — punches above its weight on reasoning. Great for math and logic tasks.
Avoid fine‑tuning models larger than 13B unless you have serious infrastructure. The marginal gain is small for most use cases.
Pitfalls in Production
I’ll keep these short.
Catastrophic forgetting. A model fine‑tuned only on domain data can get great at the domain task but forget how to answer general questions. The fix: mix 10–20% of general‑domain data into every fine‑tuning run.
Data contamination. Internal chat logs can contain personally identifiable information, and a model trained on them can generate names that match real employees. Always deduplicate and anonymize.
Evaluation mismatch. Everyone uses BLEU or ROUGE. Those scores correlate weakly with human judgment. Use task‑specific evaluation instead: for a summarization model, measure fact‑level recall using an NLI classifier. That catches hallucinations that BLEU misses.
Over‑fine‑tuning. More epochs doesn’t mean better. Use early stopping based on validation loss — and monitor the validation set’s perplexity on a held‑out general‑task benchmark.
A Decision Framework: Fine‑Tune, Post‑Train, or Do Nothing?
Here’s my quick decision tree.
-
Does the model already answer correctly 80%+ of the time with just a prompt + few‑shot examples?
→ Do nothing. Invest in prompting and retrieval. -
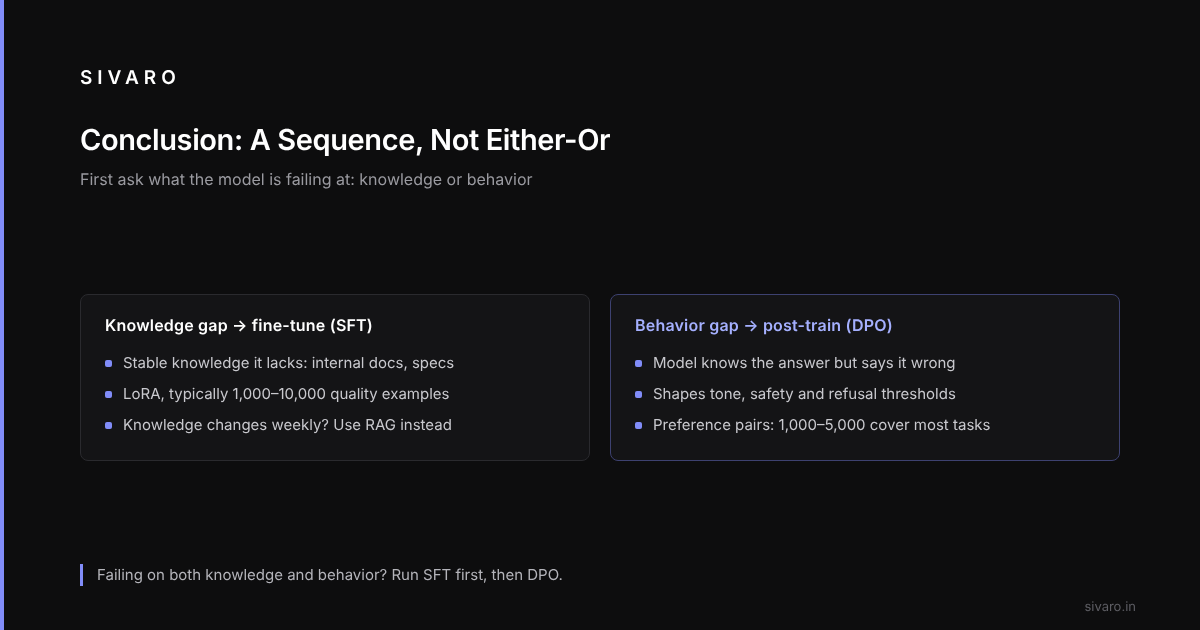
Is the model failing because it lacks specific knowledge (internal docs, product specs) that doesn’t change often?
→ Fine‑tune (SFT). Use LoRA. 1,000–10,000 high‑quality examples. -
Is the model failing because it says the wrong thing — rude, unsafe, unhelpful, hallucinated — even though it knows the answer?
→ Post‑train (DPO). You need preference pairs. 1,000–5,000 pairs is enough for most tasks. -
Is it failing on both knowledge and behavior?
→ Do SFT first, then DPO. Two‑stage pipeline. -
Does the knowledge change weekly?
→ Don’t fine‑tune. Use RAG. Fine‑tune only for format/behavior.
FAQ
What’s the difference between fine‑tuning and post‑training?
Fine‑tuning updates model weights on supervised data to inject knowledge. Post‑training (alignment) shapes behavior using preference data — usually via DPO or RLHF.
Can I fine‑tune an LLM on a Mac Studio?
Yes, but only small models (≤8B) with QLoRA. Larger models are impractical due to memory limits. Expect slow training and possible OOM errors. Cloud is cheaper in the long run.
Which open source LLM should I fine‑tune for production in 2026?
Llama‑3.2‑8B for most use cases. Mistral‑7B for code. Phi‑3‑medium for reasoning tasks.
How much data do I need for fine‑tuning?
100–500 examples for format learning. 1,000–10,000 for knowledge injection. More than 50k rarely helps.
Do I need RLHF or DPO?
If your model is already good but inconsistent on style, safety, or instruction following, yes. DPO is easier than RLHF. Start there.
What’s the cheapest way to fine‑tune?
Use Unsloth + QLoRA on a rented A100 or L40S. Cost: ~$1–$2 per hour. Most runs finish in 2–4 hours.
Can I combine fine‑tuning and post‑training?
Yes, and you should. SFT first, then DPO. That sequence consistently outperforms either alone.
Conclusion
Fine‑tuning vs post‑training isn’t a either‑or. It’s a sequence. You fine‑tune to inject knowledge. You post‑train to make that knowledge usable in the real world.
Some teams spend heavily on RLHF when a cheap LoRA fine‑tune would have solved their problem. Others skip alignment entirely, then wonder why their perfectly factual model is getting complaints for rudeness.
The cost of getting this wrong isn’t compute. It’s lost trust.
So before you touch a single weight, ask: What is the model actually failing at? Knowledge or behavior? Then pick your tool.