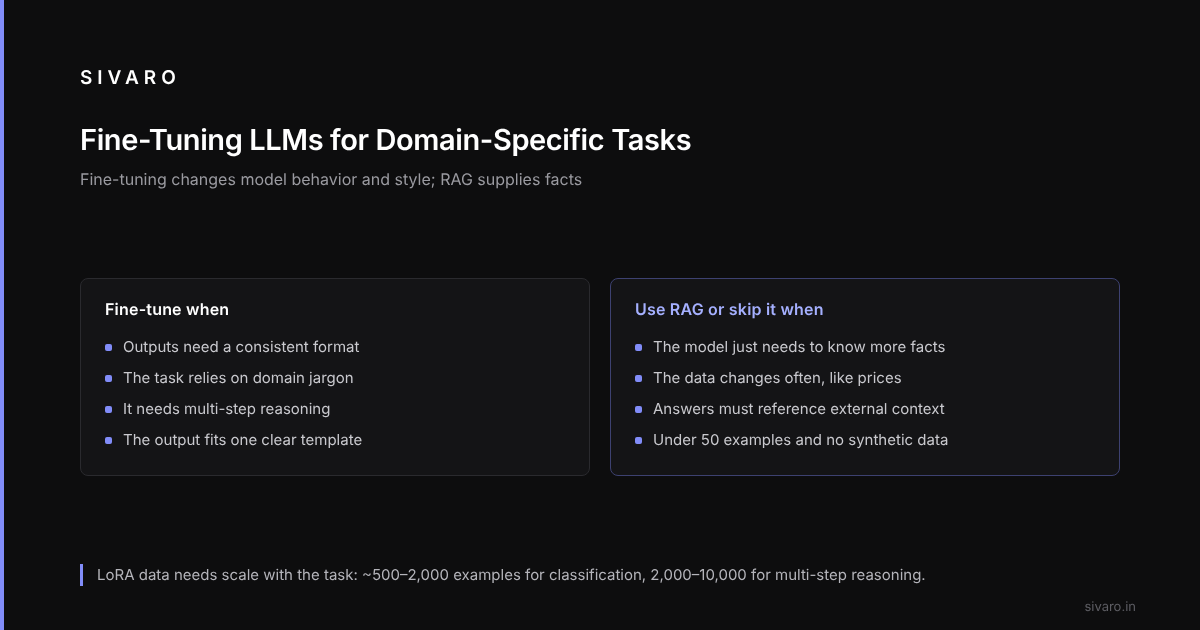
Fine tuning LLMs for domain specific tasks means taking a general‑purpose model and adapting its weights (or adding adapter layers) so it learns the patterns, vocabulary, and reasoning of your niche — medical coding, financial compliance, customer support scripts, whatever. You get a model that thinks like your domain, not like the internet.
By the end of this, you’ll know which tools to use, how much data you actually need, and when fine‑tuning is a waste of time (hint: sometimes it is).
Why Fine‑Tuning Still Matters in 2026
You’d think with base models getting smarter every quarter, fine‑tuning would be obsolete. Mistral large, Llama 4, Gemini 3 — they all crush benchmarks. But benchmarks aren’t your job. Your job is a specific task with specific errors that cost real money.
General models are broad. They know a little about everything. In 2026, a good base model can pass the bar exam — but it can’t tell you the difference between a “demand letter” and a “notice to cure” in the way your paralegals need it. That’s the gap fine‑tuning closes.
SuperAnnotate’s 2026 guide has a good breakdown of when fine‑tuning beats prompt engineering. The short version: if your task requires consistent output formats, domain jargon, or multi‑step reasoning, fine‑tune. If you just need the model to know more facts, try RAG first.
Data: The Real Bottleneck
Most people ask “how much data needed to fine tune llm” and I tell them: less than they think, but more than they expect to clean.
The Myth of “10,000 Examples”
Small datasets can be enough for narrow tasks. The key is quality, not volume. One mislabeled example in a small dataset hurts twice as much.
Rough ranges:
| Task Complexity | Minimum Examples | Recommended Range |
|---|---|---|
| Simple classification | 200–500 | 500–2,000 |
| Structured output (JSON, tables) | 500–1,000 | 1,000–5,000 |
| Multi‑step reasoning | 1,000–2,000 | 2,000–10,000 |
| Creative generation with style | 100–300 | 300–1,500 |
Those numbers are for parameter‑efficient fine‑tuning (PEFT) like LoRA. Full fine‑tune needs 3‑5x more.
The ScienceDirect paper from 2024 validates the diminishing returns curve they found — after ~2,000 examples, gains flatten quickly for most domain tasks.
Fine Tuning LLMs with Limited Dataset Size
You don’t have 10,000 labeled examples? Here’s an approach for small datasets:
- Start with synthetic data — use a strong base model (GPT‑4o, Claude 4) to generate candidate examples, then manually review 30% to catch drift.
- Use LoRA with higher rank — for tiny datasets, rank = 32 not 8. More trainable parameters per example.
- Apply aggressive validation — hold out 20 examples and check every epoch. Stop when validation loss stops dropping. Overfitting kills tiny datasets fast.
SitePoint’s practical guide walks through exact code for this scenario. I’ll share a snippet below.
Tools That Actually Work
Three tools stand out.
1. Unsloth (still the speed king)
Unsloth 2.0 came out in March.
# Unsloth example (July 2026)
from unsloth import FastLanguageModel

model, tokenizer = FastLanguageModel.from_pretrained(
    model_name="unsloth/Meta-Llama-3.1-8B",
    max_seq_length=4096,
    dtype=None,
    load_in_4bit=True,
)
model = FastLanguageModel.get_peft_model(
    model,
    r=16,
    target_modules=["q_proj", "v_proj"],
    lora_alpha=16,
    lora_dropout=0.05,
)
TechsyIO tested 10 tools and Unsloth wins on cost per finetune.
2. Axolotl for complex configs
When I need to mix instruction tuning with RLHF or control for bias, Axolotl is the only option that doesn’t make me cry. The YAML‑based config system is verbose but predictable. Deepchecks’ 2026 review puts Axolotl at #1 for teams that need reproducibility.
# axolotl config snippet
model:
  base_model: mistralai/Mistral-Large-2
  type: MistralForCausalLM
  tokenizer_type: MistralTokenizer
  load_in_8bit: true

datasets:
  - path: ./domain_data.jsonl
    type: completion

train:
  micro_batch_size: 4
  gradient_accumulation_steps: 8
  learning_rate: 2e-4
  num_epochs: 3
3. Together.ai for managed services
If you don’t want to touch GPUs, Together’s fine‑tuning API works. The tradeoff: you can’t debug as easily. TechsyIO calls it “best for non‑ML teams” and I agree.
RAG vs Fine‑Tuning in 2026: The Real Divide
RAG and fine‑tuning are not competitors. They solve different problems.
RAG is for knowledge retrieval — facts, documents, procedures that change. If your domain data updates weekly, RAG wins.
Fine‑tuning is for behavior and style — how the model thinks about your data, not what facts it retrieves. The model learns to extract key fields from insurance forms because it’s been trained on thousands of examples, not because it read a manual.
The winder.ai decision framework published in January 2026 gives a simple test: ask yourself, “Can I describe the desired output in one clear template?” If yes, fine‑tune. If you need to reference external context, use RAG.
The two can be combined: the fine‑tuned model calls a RAG API for supporting evidence when it’s unsure.
Step‑by‑Step: Fine Tuning for a Medical ICD Coding Task
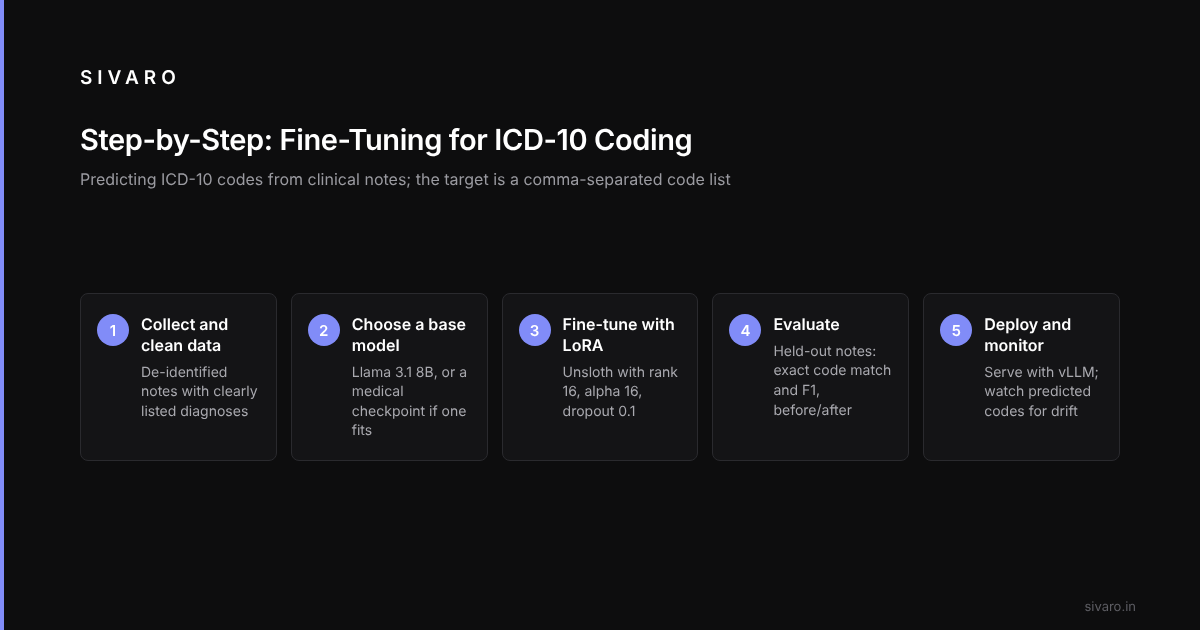
Here is a walkthrough for one task: predicting ICD‑10 codes from clinical notes, stripped down to the essentials.
1. Collect and clean data
Start from de‑identified notes, and keep only those where the diagnosis is clearly listed. Each note becomes a prompt:
Clinical note: [text]
ICD‑10 codes:
The target is a comma‑separated list of codes. That’s it. Simple format, less confusion.
2. Choose a base model
A model like Llama 3.1 8B is a reasonable base. For domain fine‑tuning, 7B–13B is the sweet spot in 2026. SuperAnnotate’s guide has a table showing model size vs. task performance — diminishing returns after 13B for most domains.
3. Fine‑tune with LoRA
The example below uses Unsloth with rank=16, alpha=16, dropout=0.1.
from unsloth import FastLanguageModel
from datasets import load_dataset

model, tokenizer = FastLanguageModel.from_pretrained(
    "unsloth/Meta-Llama-3.1-8B",
    max_seq_length=2048,
    load_in_4bit=True,
)
model = FastLanguageModel.get_peft_model(
    model, r=16, lora_alpha=16, lora_dropout=0.1,
)

dataset = load_dataset("json", data_files="icd10_data.jsonl")
train_dataset = dataset["train"].map(
    lambda x: tokenizer(x["text"], truncation=True, max_length=2048),
    batched=True,
)

trainer = from unsloth import UnslothTrainer, UnslothTrainingArguments
training_args = UnslothTrainingArguments(
    per_device_train_batch_size=4,
    gradient_accumulation_steps=8,
    learning_rate=2e-4,
    num_train_epochs=3,
    logging_steps=10,
    save_steps=200,
    output_dir="./icd10_model",
)
trainer = UnslothTrainer(
    model=model,
    args=training_args,
    train_dataset=train_dataset,
)
trainer.train()
4. Evaluate
Hold out a set of notes the model never saw, and compare exact code match before and after fine‑tuning.
5. Deploy and monitor
vLLM works for inference. After deployment, watch the distribution of predicted codes for drift.
Cost Breakdown: What You Actually Spend
Data labeling is usually the largest cost. The Best 5 LLM Fine-Tuning Tools of 2026 list highlights LabelStudio + active learning as a “highest ROI” combo.
If you’re fine tuning LLMs with limited dataset size, you spend more on prompt engineering and validation — but your GPU cost stays low because training is fast.
When NOT to Fine‑Tune
Three scenarios where fine‑tuning wastes money:
- The task is pure knowledge lookup. If you need the model to answer “What’s the price of product X?” based on a database, build RAG. Fine‑tuning can’t keep up with changing prices.
- You have fewer than 50 examples and can’t generate synthetic data. Even with LoRA, the model will just memorize those 50 examples and fail on the 51st.
- Your domain is already covered by a specialized model. In 2026 there are finetuned models for radiology, legal contracts, and even tax code. Start from one of those, not from Llama.
AI Agents Plus has a checklist called “Should I Fine‑Tune?”
Fine‑Tuning Infrastructure in 2026
You don’t need a cluster. A minimal setup:
- One GPU with 24GB+ VRAM — L40S, A10, or 4090. For 7B models, 24GB works with 4‑bit quantization. 48GB lets you use 8B with higher batch sizes.
- Spot instances — AWS g5.xlarge spot costs ~$0.40/hr in us‑east‑2. Most fine‑tuning jobs run 2–8 hours.
- Containerization — Docker with Unsloth’s base image. No pip conflicts, no driver mismatches.
- Experiment tracking — Weights & Biases free tier. Logs everything.
For teams who want managed: TechsyIO rates Together.ai and Modal as top choices. Modal’s serverless GPU model is interesting for batch jobs that don’t need persistent infrastructure.
FAQ
How much data needed to fine tune llm for a domain task?
It depends on complexity and model size. For a 7B model with LoRA, 500–2,000 high‑quality examples usually works. For full fine‑tune, aim for 5,000+.
Can I fine tune llms with limited dataset size (under 200 examples)?
Yes, but with caveats. Use LoRA with higher rank (32+), generate synthetic data from a stronger model, and monitor validation loss closely. One bad example will ruin the model. See “Fine Tuning LLMs with Limited Dataset Size” section above.
What’s the best tool for fine‑tuning in 2026?
Unsloth for speed and cost on consumer GPUs. Axolotl for complex pipelines. Together.ai for managed API. Test all three with a small dataset — one will click.
Is fine‑tuning better than RAG for domain tasks?
Not a binary choice. Fine‑tuning changes model behavior; RAG supplies facts. Most production systems need both. Use the decision framework from winder.ai.
How long does fine‑tuning take?
For 5,000 examples on a single A100 with LoRA: 2–4 hours. Full fine‑tune: 12–24 hours. Setting up the data pipeline takes longer than the training.
Should I fine‑tune a base model or start from a domain‑specific checkpoint?
Start from a domain checkpoint if one exists. For medical, use BioMistral or PMC‑Llama. For legal, Saul‑LM. You’ll need 60% less data because the model already knows some jargon.
What evaluation metrics should I use?
Match the metric to your task. For classification, F1. For generation, ROUGE‑L or BERTScore. For structured output, exact match. Never trust loss alone — it can drop while your model gets worse.
How do I prevent overfitting on a small dataset?
Use LoRA, apply dropout (0.1–0.2), shorten training (2–3 epochs max), and validate on a held‑out set after every epoch. If validation loss starts rising, stop immediately.
The Hard Truth
Fine‑tuning isn’t magic. It’s engineering with messy data. The models are getting smarter, and soon even a 1B parameter model fine‑tuned on 500 examples will beat a raw 70B model on your domain task.
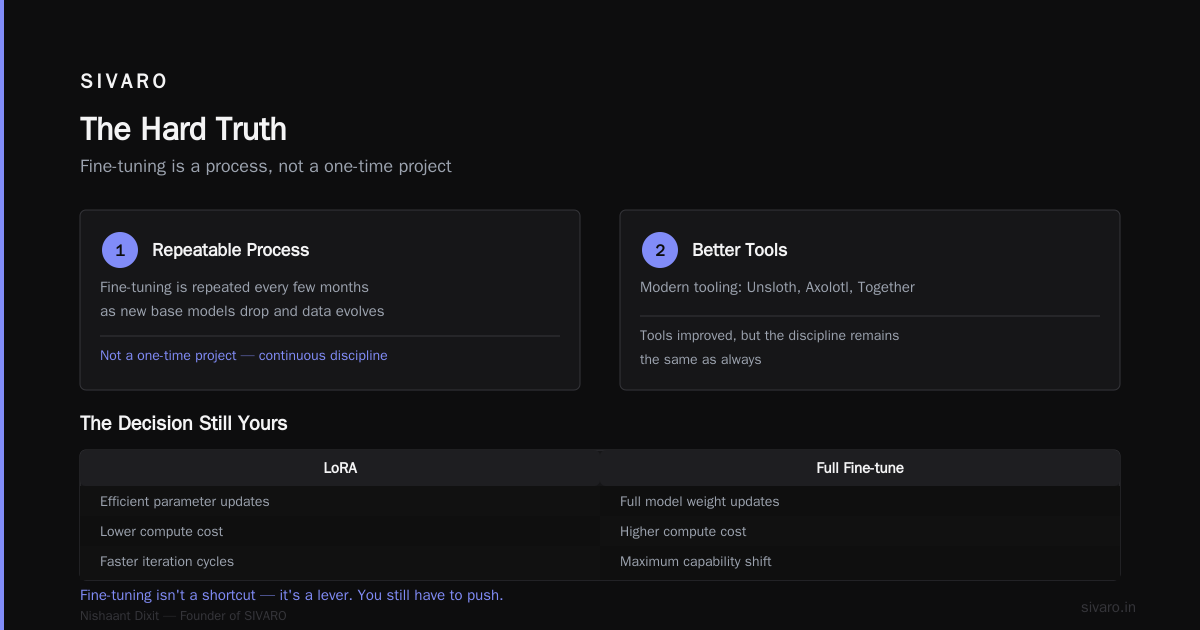
But you still have to clean the data. You still have to decide whether to use LoRA vs full fine‑tune. You still have to measure results in your own business metrics, not perplexity.
Fine‑tuning works better as a repeated process than as a one‑time project: repeat it every few months as new base models drop and your data evolves. The tools are better now — Unsloth, Axolotl, Together — but the discipline is the same.
Fine tuning LLMs for domain specific tasks isn’t a shortcut. It’s a lever. You still have to push.