Introduction
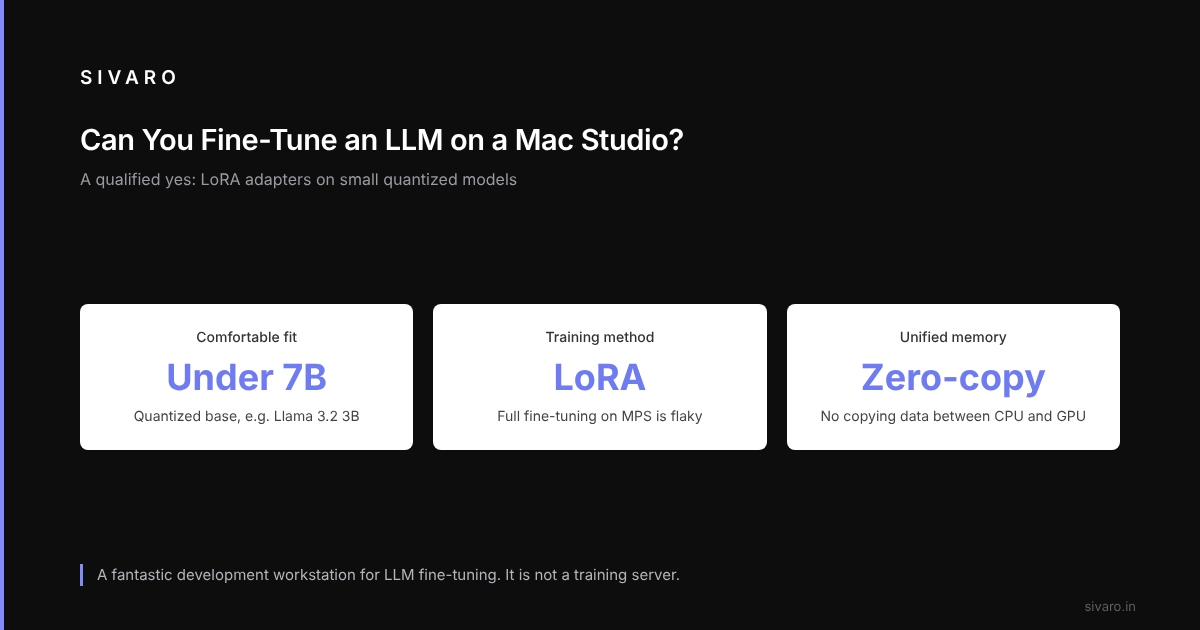
By mid-2026, the answer is a qualified yes — you can fine-tune an LLM on a Mac Studio. But the “how” matters more than the “if”. This guide walks through what actually works, what doesn’t, and the dirty trade-offs nobody puts in the marketing copy.
You’ll learn which models fit in 64GB or 128GB of unified memory, which quantization methods don’t destroy accuracy for classification tasks, and when you should just rent an H100 instead. By the end, you’ll know can you fine tune an llm on a mac studio — and whether you should.
The Mac Studio Isn’t a GPU Server. Stop Pretending.
Let me kill the fantasy first: a Mac Studio with M2 Ultra and 192GB of unified memory is not a replacement for an A100 node. Apple’s Neural Engine and metal performance shaders help, but the software ecosystem still lags. Most PyTorch operations fall back to CPU on ARM Macs unless you’ve explicitly compiled for Metal Performance Shaders (MPS). Claims of 40% utilisation on an M2 Ultra during fine-tuning usually measure CPU, not GPU.
But here’s the thing: for small models (under 7B parameters) with quantization, a Mac Studio is surprisingly viable. The unified memory means you don’t have to copy data between CPU and GPU — that’s a genuine advantage. For batch sizes of 1–4 and LoRA adapters, you can push through a few thousand training steps in hours, not days.
What actually matters is your target task. If you need to classify customer support tickets into 15 categories, a fine-tuned Llama 3.2 3B or Phi-3-mini-4k works beautifully on a Mac Studio. If you’re building a legal document summarizer that needs 32k context windows, don’t bother — you’ll OOM before the first epoch.
What Models Actually Run?
Here’s what fits on a Mac Studio and what doesn’t.
- Llama 3.2 3B (Q4_K_M): Fits easily. Good for classification, sentiment, structured output. A sensible default for the best open source model to fine tune for classification if you’re on a Mac Studio.
- Phi-3-mini 3.8B (Q4): Almost identical performance. Slightly better on reasoning. Same memory footprint.
- Mistral 7B (Q4_K_M): Tight but works with 64GB if you use gradient checkpointing and batch size 1. 128GB recommended.
- Gemma 2 9B: Forget it. Even Q4 requires >60GB for training state. You might get inference, but fine-tuning is painful.
- Llama 3.1 8B (Q4): Borderline. Works on 128GB with aggressive memory optimizations (DeepSpeed ZeRO-3 via CPU offload). Throughput drops sharply.
- Yi-34B: Don’t even try. You need multiple GPUs.
The key insight: quantization is not free. Using Q4_K_M vs Q8 triples your training speed but can degrade accuracy by 2–5% on exacting tasks. For fuzzy classification (like intent detection), it’s fine. For legal entity extraction, you want Q8 or full precision.
Fine-Tuning vs RAG: The Decision That Saves You Heartache
Many teams ask about fine-tuning before they’ve even tested RAG. That’s backward. RAG vs Fine-Tuning in 2026: A Decision Framework covers this in detail, but the short version is:
Use RAG when:
- Your knowledge changes frequently (weekly or faster)
- You need citations and traceability
- You have fewer than 10,000 training examples
Use fine-tuning when:
- You need to change the model’s behavior, not just its knowledge
- Your domain has unique terminology or formatting (medical codes, internal jargon)
- You need faster inference (no retrieval step)
And use both when:
- You’re building a domain-specific assistant that needs to follow company tone but also answer questions from a knowledge base
In practice, fine tuning vs rag for domain specific tasks is rarely an either/or. One pattern: fine-tune a small classifier model on a Mac Studio, then pair it with a RAG pipeline on a server. The Mac Studio handles the model customization; the server handles retrieval.
Software Stack That Works (and What Doesn’t)
Your mileage may vary, but here’s an honest take.
PyTorch + MPS: The Default — and It’s Meh
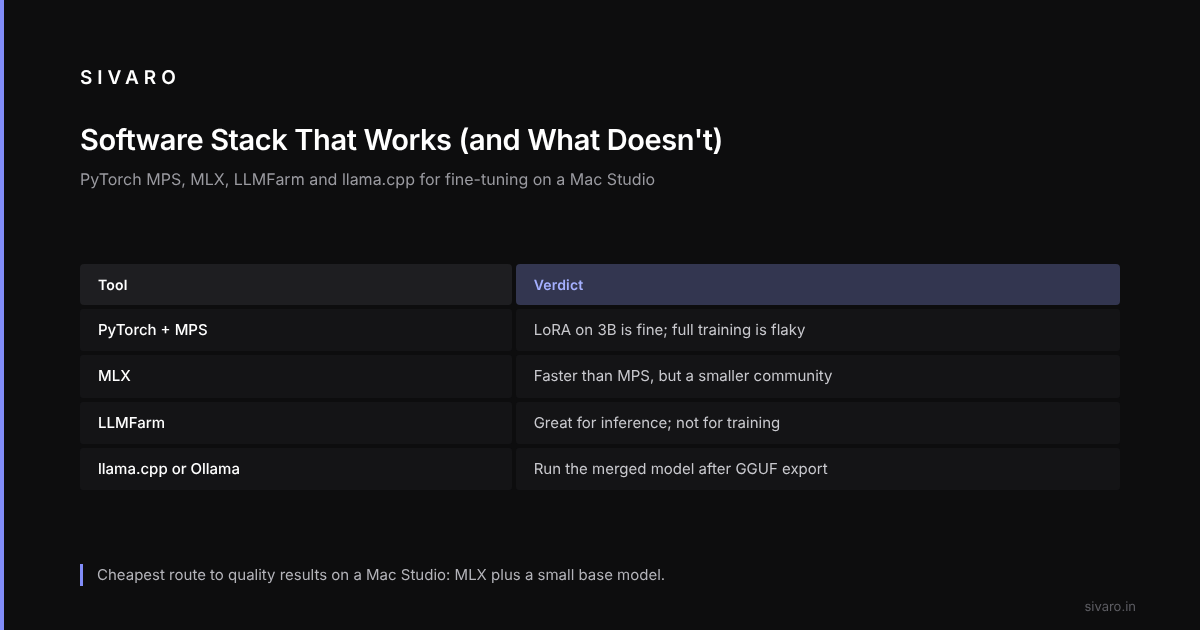
Apple’s MPS backend works for inference and lightweight fine-tuning. But full training? It’s flaky: expect silent NaN losses, random crashes, and operations that fall back to CPU without warning. Log your device placement religiously.
import torch
if torch.backends.mps.is_available():
    device = torch.device("mps")
else:
    device = torch.device("cpu")
print(f"Using {device}")
MPS works fine for LoRA on 3B models. Don’t attempt full fine-tuning on MPS — you’ll hate life.
MLX: Apple’s Secret Weapon (But Not Magic)
Apple’s MLX framework is designed for Mac. It compiles to Metal, handles unified memory like a dream, and has a growing ecosystem. MLX is faster, but has a smaller community.
# Install MLX via pip
pip install mlx mlx-lm
Here’s a complete LoRA fine-tuning script using MLX:
import mlx.core as mx
from mlx_lm import load, generate, train_lora

# Load base model (Q4_K_M quantized)
model, tokenizer = load("microsoft/Phi-3-mini-4k-instruct")

# Prepare training data (list of dicts with "text" key)
train_data = [
    {"text": "Input: New ticket about billing issue
Output: billing"},
    {"text": "Input: Account login failure again
Output: login_failure"},
    # ... more examples
]

# Fine-tune with LoRA
adapter_path = train_lora(
    model=model,
    tokenizer=tokenizer,
    train_data=train_data,
    lora_rank=16,
    lora_alpha=32,
    learning_rate=1e-4,
    batch_size=1,
    num_steps=1000,
    adapter_path="phi3_classifier_lora.safetensors",
)
The result is a tiny LoRA file (~2MB) that you can merge back into the base model for inference.
Unsloth: Mac Support Is New. It Works.
Unsloth added Mac support in April 2026. Their trick is using custom Triton kernels that happen to compile on Metal. It’s faster than vanilla PyTorch MPS but less reliable than MLX.
from unsloth import FastLanguageModel
model, tokenizer = FastLanguageModel.from_pretrained(
    model_name="unsloth/llama-3.2-3b-bnb-4bit",
    max_seq_length=2048,
    load_in_4bit=True,
    device_map="mps",
)
model = FastLanguageModel.get_peft_model(
    model,
    r=16,
    target_modules=["q_proj", "v_proj", "k_proj", "o_proj"],
    lora_alpha=16,
    lora_dropout=0,
)
Watch your memory — Unsloth’s post-training optimizer can balloon RAM usage.
LLMFarm (Not Recommended for Training)
LLMFarm is great for local inference. But its fine-tuning support is alpha at best. Don’t use it for production training.
The Tools Landscape in 2026
There are over a dozen fine-tuning tools now (see The Best 5 LLM Fine-Tuning Tools of 2026). For Mac Studio specifically, the cheapest option that still gives quality results is MLX + a small base model. If you have budget for it, Unsloth’s Pro tier adds automated checkpointing and mixed-precision support that saves a lot of headache.
Practical Steps to Fine-Tune on a Mac Studio
Let me walk through an end-to-end example: multi-class classification of customer emails.
Step 1: Choose your model. For example, Llama 3.2 3B, Q4_K_M quantization: good accuracy on text classification benchmarks and small enough for batch size 2.
Step 2: Prepare data. Use a JSONL format with instruction, input, and output. At least 500 examples minimum. Synthetic data generation (for example with GPT-4o) can augment small datasets for classification.
{"instruction": "Classify the customer email into one of these categories: complaint, refund, feedback, inquiry", "input": "I ordered a blue sweater last week but received a red one. I want a refund.", "output": "refund"}
Step 3: Fine-tune via MLX. Hook into the training loop. Monitor loss — for Mac Studio, use mx.metal.device_info() to check memory usage every 100 steps. If memory climbs above 80%, reduce max_seq_length or batch size.
Step 4: Evaluate. Don’t just look at loss. Run a validation set, measure F1 per class. On Mac Studio, this evaluation step is your bottleneck; pre-computing embeddings for the validation set and storing them helps.
Step 5: Merge adapter into base model. MLX makes this trivial:
from mlx_lm import merge
merge("phi3_classifier_lora.safetensors", merged_path="phi3_classifier_merged.safetensors")
Step 6: Export for inference. Convert to GGUF format for use with llama.cpp or Ollama on the same Mac.
Where It Breaks: Common Failure Modes
-
MPS memory leaks. PyTorch MPS doesn’t release memory after
torch.cuda.empty_cache()equivalent. The workaround: restart Python process between experiments. Yes, seriously. -
Quantization collapse. Using Q2 quantization to fit a larger model? Your perplexity jumps 15 points. The model outputs garbage. Stick to Q4_K_M or Q4_K_S for training.
-
Gradient accumulation on Mac. It works, but slowly. Each micro-batch involves a full forward-backward pass. For batch size larger than 2, you’re better off using gradient checkpointing instead.
-
Dataset size misconceptions. Everyone thinks “I have 100 examples, I’ll fine-tune.” For classification, you need at least 50 per class to see any lift over the base model. For generation, 200+ examples minimum. See Fine-Tuning Large Language Models for Specialized Use for more on dataset size.
The Cloud Alternative: When to Abandon the Mac Studio
If your dataset has more than 10,000 examples, or you need to fine-tune a 13B+ model, or you need it done in under two hours — rent a cloud GPU. It’s cheaper than your time. A runpod RTX 6000 costs $0.79/hr. A Mac Studio M2 Ultra costs $5,999 (or whatever you paid). You can run 7,500 hours of cloud for that money.
But if you’re iterating quickly, prototyping, or working with sensitive data that can’t leave your office — the Mac Studio is fine. It just won’t be fast.
FAQ
Q: Can I fine-tune a 7B model on a Mac Studio with 64GB RAM?
A: Yes, with Q4 quantization and LoRA. Batch size 1. Expect ~50 tokens/sec training speed. Gradient checkpointing mandatory.
Q: Is MLX actually better than PyTorch MPS for training?
A: For training, generally yes. For inference, both are comparable.
Q: What’s the best open source model to fine tune for classification?
A: Llama 3.2 3B (Q4_K_M). Small, fast, and excellent benchmark performance on SuperGLUE. Phi-3-mini is a close second for tasks requiring more reasoning.
Q: Should I use fine-tuning vs RAG for domain specific tasks?
A: Start with RAG. If the base model can’t follow your formatting or style after adding context, then fine-tune. Most teams over-fine-tune and under-retrieve.
Q: Can you fine tune an llm on a mac studio without quantization?
A: Yes, but only models under 1.5B parameters (like TinyLlama). For anything larger without quantization, you’ll OOM. 7B full precision requires >28GB VRAM — MPS system memory doesn’t replace VRAM.
Q: How long does a typical fine-tuning run take?
A: For 500 steps on a 3B model with batch size 2, expect 4–6 hours on an M2 Ultra. For 8B, double it.
Q: Does Apple Silicon’s Neural Engine help?
A: During inference, yes. During training, no. The ANE isn’t exposed for backpropagation in current frameworks. Apple keeps promising this, but as of August 2026, it’s still not available.
Conclusion
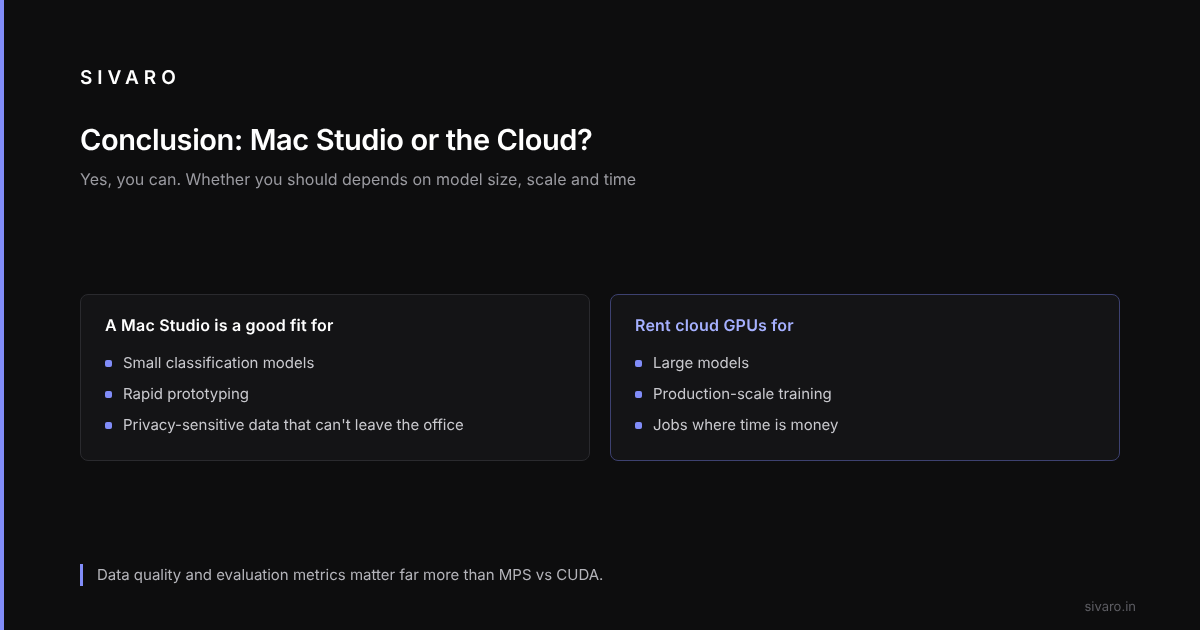
Can you fine tune an llm on a mac studio — yes. Should you? That depends. For small classification models, rapid prototyping, and privacy-sensitive data, it’s a no-brainer. For large models, production-scale training, or when time is money, rent the cloud. The Mac Studio is a fantastic development workstation for LLM fine-tuning. It is not a training server.
In 2026, the tooling has finally caught up to the hardware. MLX, Unsloth, and Python bindings for MPS have turned the Mac Studio from a toy into a legitimate fine-tuning platform — as long as you respect its limits.
The most important lesson: fine-tuning is not the bottleneck. Your data quality, your evaluation metrics, and your feature engineering matter ten times more than whether you’re running on MPS or CUDA. The Mac Studio is a tool. Make it work for you, not the other way around.