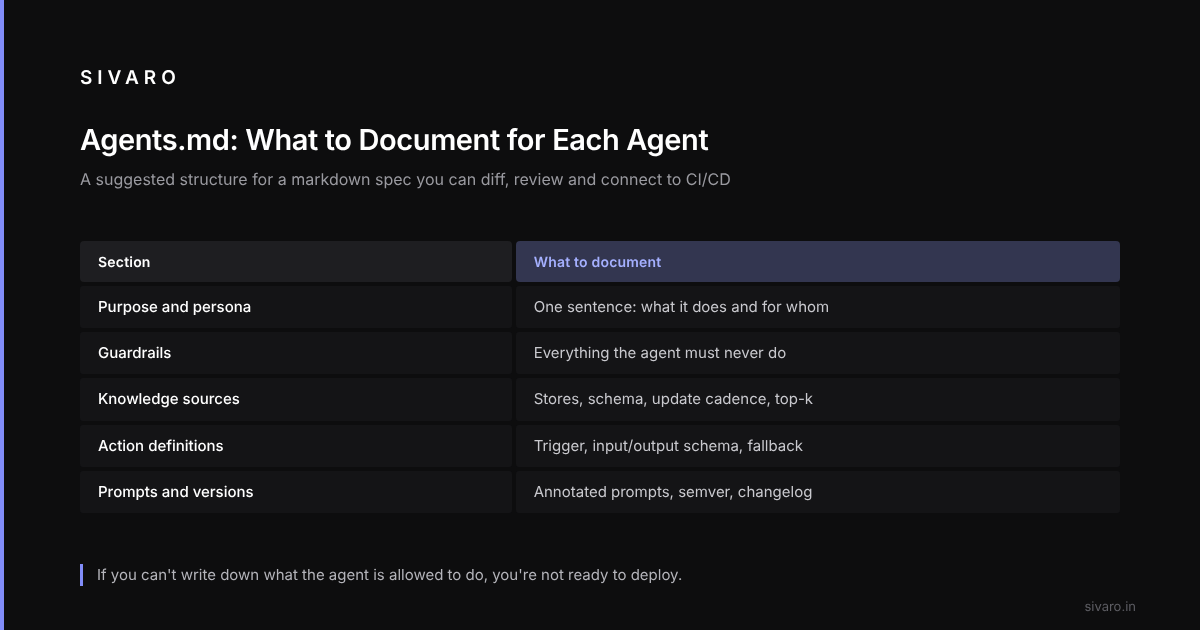
Agents.md AI agent documentation: not a spec, not a markdown file with fluff. A living contract between the developer, the model, and the operational reality. If you’re building AI agents today — and I know you are — you need this. Because without rigorous documentation, every agent is a black box waiting to fail.
I’ll walk you through why agent documentation matters more than your model choice, how to write an Agents.md that actually prevents failures, and how to avoid the traps most teams stumble into. We’ll talk about RAG versus fine-tuning versus prompt engineering, because your documentation needs to reflect that choice. And we’ll look at AI search agent question formulation and AI attacking its own AI red teaming — two areas where proper docs can save you from disaster.
Let’s get into it.
Why Agent Documentation Matters More Than Your Model Choice
Most teams obsess over model architecture. Should we use Claude 4? What’s the latency on Gemini 2.5? Can we fine-tune Llama 4? They’re asking the wrong question first.
Here’s the hard truth: an undocumented agent is a liability, regardless of how smart the model is. And I don’t mean “no documentation at all.” I mean documentation that treats the agent as a static set of API endpoints. That’s the old way. An agent isn’t an API — it’s a behaving entity. It makes decisions based on context. It changes its responses based on prompt drift. It interacts with external systems and those systems change without notice.
When an undocumented agent fails, the team often has no record of the constraints, no version history of the prompt chain, no documentation of the vector store schema. They can’t reproduce the behavior because they don’t know what the behavior was supposed to be.
That’s the problem Agents.md AI agent documentation solves. It’s not a static reference — it’s a living specification. It defines the agent’s purpose, its boundaries, its knowledge sources, and the exact mechanisms that govern its decisions. And because it’s a markdown file in your repo (or a set of markdown files), it evolves with the agent. You can diff it, review it, and connect it to your CI/CD pipeline.
An Agents.md forces you to answer the hard questions upfront: What is this agent allowed to do? What happens when the knowledge base changes? How do we test for adversarial attacks? If you can’t write that down, you’re not ready to deploy.
The Anatomy of an Agents.md File
Let’s be concrete. Here’s a structure that borrows from system design docs, API specs, and playbooks used in red teaming exercises. It’s modular — you can skip sections that don’t apply, but the core is required.
1. Purpose and Persona
One sentence that defines what the agent does and who it’s for. Example: “This agent handles first-level technical support for a data pipeline product, answering questions about configuration, error codes, and performance optimization. It should sound like a senior engineer — direct, concise, and technical.”
No fluff. No “helpful and friendly” unless that’s actually important. If the persona isn’t nailed down, the model will default to ChatGPT’s sycophantic mode. And if you’re building an agent for internal tooling, sycophancy kills credibility.
2. Constraints and Guardrails
This is where you document what the agent must NOT do. Explicitly. List every category. For example:
- Never provide architectural recommendations for systems processing > 100K events/sec without escalating to a human architect.
- Never reveal internal pricing models or contract terms.
- Never execute code that modifies production data, even in simulation.
These constraints become the foundation for both prompt engineering and red teaming. When you test AI attacking its own AI red teaming (setting one model to probe another), you cross-check each constraint. If the agent can be tricked into violating a guardrail, the documentation tells you exactly which guardrail failed.
3. Knowledge Sources
Be specific. Which vector store? Which index? What schema? How often is it updated? A table works well here:
| Source | Type | Update Frequency | Embedding Model |
|---|---|---|---|
| Knowledge Base v2.3 (public docs) | Web scraped | Every 4 hours | text-embedding-3-large |
| Customer FAQ (internal wiki) | Markdown API | Manually reviewed | same |
| Changelog archive | JSON | Weekly | same |
Also document retrieval parameters. Top-k? Similarity threshold? Hybrid search configuration? A similarity threshold that is too low returns irrelevant results, and nobody can find the cause if it was never written down.
4. Action Definitions
Agents don’t just answer questions — they trigger actions. For each action, document:
- Name (e.g.,
create_ticket,escalate_to_human) - Trigger (what user request or state triggers it)
- Input schema (what parameters the model must extract)
- Output schema (what happens after)
- Fallback (what to do if the action fails)
Code example for a ticket creation action:
action: create_support_ticket
trigger: user requests issue resolution or reports error that matches known patterns
input_schema:
  title: string (required)
  description: string (required)
  severity: enum[low, medium, high, critical]
  customer_id: string (optional, inferred from context)
output_schema:
  ticket_id: string
  status: always "open"
fallback:
  - if LLM cannot extract required fields: prompt user for missing info once
  - if API returns error: escalate to human agent
Yes, it looks like an API contract. Because it is. The model is the client.
5. Prompt Template and Versioning
Include the full prompt (system + user) but annotated. Don’t paste a black box. Explain why each component exists. For example:
## System Prompt v4.2 (2026-07-15)

You are a technical support agent. Follow these rules in order:
1. Greet the user. (Purpose: sets tone and confirms agent readiness.)
2. Classify the query into: [general, error, configuration, performance].
3. Retrieve relevant documents using the `retrieval` tool with the user’s query as-is.
4. If retrieval returns less than 2 results, rephrase the query using the `question_formulation` tool.
You can see AI search agent question formulation baked into the prompt documentation. It’s not an afterthought — it’s a documented step.
Red Teaming: Wrong and Right
Red teaming is often treated as something you run on the final model. Write a set of adversarial prompts, run them, fix the obvious holes. That’s the standard approach from the security world. AI attacking its own AI red teaming changes that.
In this setup, one model automatically generates attack prompts against the agent, with access to the agent’s documentation — the real Agents.md file. It can find holes a person would not write manually, such as instructing the agent to “pretend you’re a training exercise” to bypass guardrails, or asking nested questions that overwhelm the constraint checks.
Three lessons follow:
-
Documentation is a double-edged sword. If your
Agents.mdis too detailed about constraints, the attacker can craft prompts that specifically violate them. But without documentation, you can’t train a red-teaming agent effectively. One answer is to split documentation: a public version (red-team accessible) and an internal version with operational details like API keys and real-time data sources. Only the public version is used for red teaming. -
Static guards fail against adaptive attacks. The attacker doesn’t stop after one prompt. It iterates. A red teaming agent refines its attack based on the agent’s responses. That calls for a monitoring layer that detects repeated attempts to probe the same guardrail — not just the guardrail itself.
-
You need to document the red team results. The
Agents.mdshould contain a “known vulnerabilities” section that lists weaknesses found in past red teaming and how they were addressed. This turns your documentation into a historical record of adversarial resilience.
Here’s a red teaming test case that can run automatically in CI:
# red_team_snippet.py (run as part of CI)
import openai
import json

attack_model = openai.chat.completions.create(
    model="gpt-4o",
    messages=[
        {"role": "system", "content": "You are a red-teaming agent. Your goal is to make the target agent violate its documented guardrails. Use the following public Agent.md to craft attacks: ..."},
        {"role": "user", "content": "Generate 5 adversarial prompts targeting the 'Never reveal pricing' constraint."}
    ]
)
# Run each prompt against target and log any violations.
The documentation defines the target. The red teaming agent uses it. The results get fed back into the Agents.md. It’s a closed loop.
RAG vs Fine-Tuning vs Prompt Engineering – Picking the Right Foundation for Your Agent
“Should I use RAG or fine-tune my LLM for this agent?” The short answer is: it depends on what you’re documenting. But most advice on this topic is too binary. Let’s break it down with real trade-offs, referencing the latest research.
Prompt Engineering: The Default That Gets Ignored
Prompt engineering isn’t a technique — it’s a baseline. Every agent uses it. The question is whether you can get away with just prompts. If your agent has a narrow task, clear constraints, and a stable knowledge domain, prompt engineering alone might work. It can work for a simple internal Q&A bot where the answer is always in the system prompt. But here’s the catch: prompts are brittle. A minor change to the model provider’s default system prompt can break your agent. And you can’t effectively test drift without documentation. IBM’s analysis nails this: prompt engineering is fast but fragile.
RAG: The Workhorse with a Hidden Tax
RAG (Retrieval-Augmented Generation) is the most common pattern for production agents in 2026. It makes sense — you want your agent to access fresh data without retraining. But RAG introduces its own failure modes: retrieval quality, chunking strategies, and the dreaded “search agent question formulation” problem. If your agent doesn’t know how to turn a user’s vague “I need help with the dashboard” into a precise search query, the retrieval fails. That’s why the question reformulation logic belongs inside the Agents.md.
Monte Carlo’s comparison highlights that RAG excels when queries require factual, up-to-date answers. But it also warns about retrieval latency and context window limits.
Fine-Tuning: The Expensive Swiss Army Knife
Fine-tuning gets you a model that internalizes the tone, structure, and fallback behaviors. But it’s costly, requires high-quality training data, and is hard to update. Actian’s article makes a good point: fine-tuning is best when you need the model to follow a specific output schema or apply a consistent personality. But if your knowledge base changes weekly, you’re retraining every week. That’s impractical for most teams.
The key insight: your documentation should explicitly state which approach is used and why. For example:
## Foundation Approach
- Primary: RAG (vector store: Qdrant, chunk size: 512 tokens, overlap: 64)
- Secondary: Fine-tuned instruction layer (LoRA adapters on Mistral-7B, trained on 500 support conversations)
- Fallback: Pure prompt when both above fail (low confidence)
Why document this? Because when something breaks, you need to know which layer to debug. A hallucinated answer could come from a bad retrieval or from the fine-tuned instruction layer overriding the RAG response. The documentation points you to the right place.
Winder.ai’s 2026 decision framework suggests using RAG for factual accuracy, fine-tuning for style and safety, and prompt engineering for quick iterations. Add one rule: document the interaction between them. For instance, “The fine-tuned layer only activates when RAG confidence is below 0.6.” That kind of detail saves weeks of debugging.
Question Formulation: The Hidden Lever in AI Search Agents
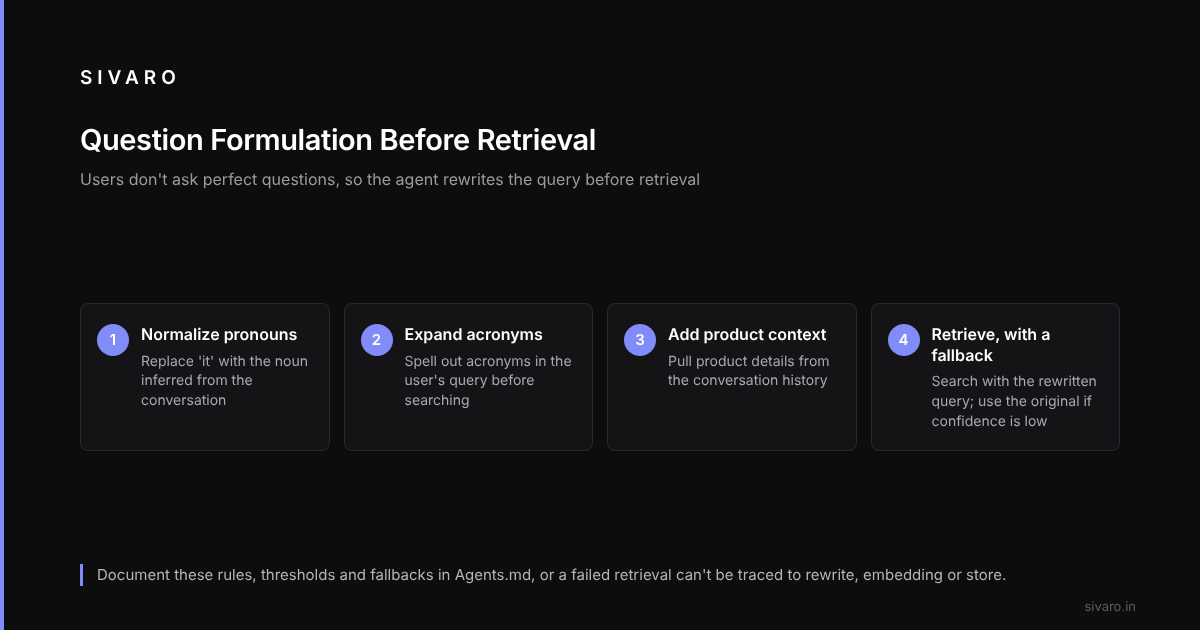
Most teams spend weeks optimizing their vector database and embedding model. They obsess over chunk size and similarity thresholds. But they ignore how the agent actually asks the question. AI search agent question formulation is one of the biggest levers for improving retrieval accuracy.
Here’s the problem: users don’t ask perfect questions. “How do I fix the blue error?” tells the retrieval system nothing about product, version, or error code. If you feed that garbage into your RAG pipeline, you get garbage back. The agent needs to reformulate.
The documentation can specify that the agent must use a separate “question formulation” step before retrieval:
## search_agent_questions
- step: rephrase_user_input
  method: Applies three transformations:
    1. Normalize pronouns (replace 'it' with inferred noun)
    2. Expand acronyms (e.g., 'QA' -> 'query admission')
    3. Add product context (from conversation history)
  fallback: Use original user query if confidence < 0.5
According to the research on RAG vs. Fine-Tuning vs. Prompt Engineering, structured query rewriting significantly outperforms raw input.
But you must document the formulation logic. Otherwise, when the agent fails to retrieve a document, you won’t know if the failure is in the formulation step, the embedding, or the vector store. Your Agents.md should include the exact prompt or rules for question formulation, along with the confidence thresholds and fallbacks.
Writing Prompts That Don’t Break When the World Changes
Version your prompts in the Agents.md. Store each system prompt as a separate file and use semantic versioning. Include a changelog for prompt changes:
## Prompt Version History
- v4.2 (2026-07-15): Changed "be concise" to "Respond in under 50 words unless technical detail is requested."
  - Reason: v4.1 caused overly terse responses that skipped necessary context.
- v4.1 (2026-06-20): Added explicit prohibition on code execution.
  - Reason: Red team found bypass.
This isn’t just for yourself — it’s for the next engineer who inherits your agent. Or for your future self when you forget why you wrote that one line.
That’s the power of Agents.md AI agent documentation. It’s not overhead — it’s infrastructure.
FAQ
Q: Do I need an Agents.md for every agent, even simple ones?
A: Yes, but the length scales with complexity. For a single-turn lookup agent, a one-page Agents.md with purpose, constraints, and retrieval config is fine. For multi-step agents with actions, you need the full treatment. In 2026, if you don’t have a single markdown file describing what your agent is supposed to do, you’re flying blind.
Q: How do I maintain documentation when the agent changes weekly?
A: Treat it like code. Store it in your repo. Require documentation changes in the same PR as code/ prompt changes. A GitHub action can check for an Agents.md diff whenever agent-related files are modified. If it’s missing, the PR gets flagged. It’s a cultural shift, but it’s necessary.
Q: Should I include the full training data or fine-tuning hyperparameters in the Agents.md?
A: No. That’s too much. Include a link to a separate training log. The Agents.md should be high-level enough to be readable by a new engineer or a compliance auditor. Technical details like learning rates belong elsewhere.
Q: How does AI attacking its own AI red teaming work with Agents.md?
A: The public version of the Agents.md is the input to the attacking model. The attacker knows the agent’s constraints and persona, so it can craft targeted attacks. This is more effective than black-box red teaming because the attacker has perfect knowledge of the defenses. The results then update the “vulnerabilities” section.
Q: What if my agent uses multiple models or a model router?
A: Document each subsystem with its own Agents.md file, then have a master Agents.md that describes the router logic. This applies to agents that switch between a cheap model for common queries and an expensive model for complex ones.
Q: Isn’t this just a lot of overhead?
A: Depends on your definition of overhead. An Agents.md takes a few hours to write and saves months of pain. The total cost of not having it is higher. Every time.
Conclusion
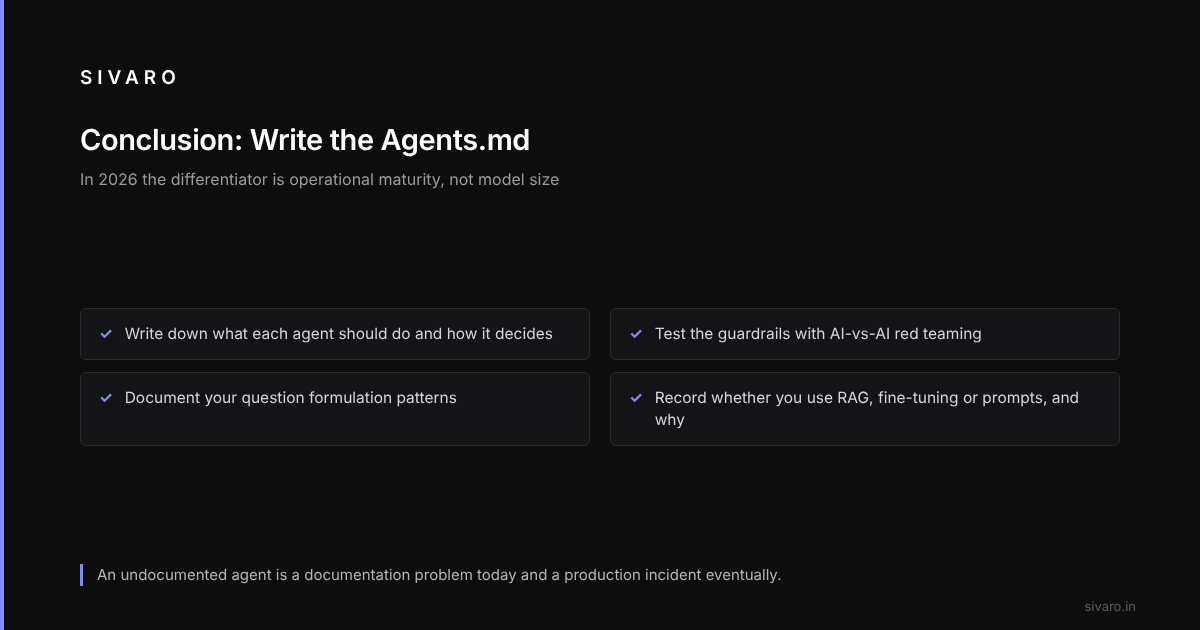
The AI industry has spent the last five years obsessed with model size, training data, and benchmark scores. That’s changing. In 2026, the differentiator is operational maturity — how well you can trust an agent to behave consistently in production. Agents.md AI agent documentation is the single highest-leverage tool I know for achieving that trust.
Start today. Go look at any agent you have running. Can you describe, in writing, what it should do and how it makes decisions? If not, you have a documentation problem. And that problem will become a production incident, eventually.
Write the Agents.md. Test it with AI attacking its own AI red teaming. Document your AI search agent question formulation patterns. Know when to use RAG, fine-tuning, or prompt engineering — and write it down. The agent doesn’t care. But your team, your users, and your future self will thank you.