So you've built a chatbot that can order a pizza. Cute. The real question is: can you trust it to do that for 10,000 customers while your CTO sleeps?
Here's the key point: the difference between AI agents and workflow automation isn't the technology. It's the failure mode.
This guide covers when to use which, how to build both for production, and where most teams screw up.
What I Mean By "Workflow Automation" vs "AI Agent"
Let's define terms. In 2026, these two terms still get conflated constantly. They're not the same thing.
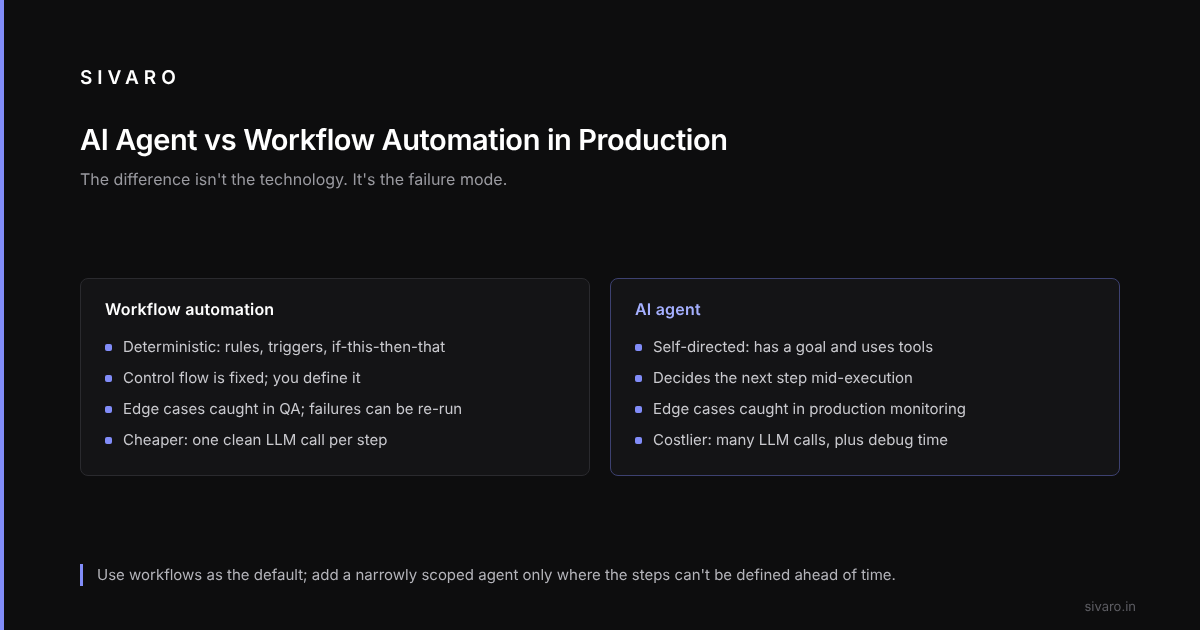
Workflow automation is a deterministic path. Rules. Triggers. If-this-then-that. Maybe with an LLM injected at some step. But the control flow is fixed. You define it. The machine executes it.
AI agents in contrast are self-directed. They have a goal. They use tools. They decide which step comes next based on what they learn mid-execution. The whole point is that you don't script the path.
A year ago, Anthropic published one of the most practical takes on this. They said most production use cases are better served by simple, composable workflows than autonomous agents (Building Effective Agents). That was true then.
It's still true. But the line has moved.
The Reinforced Monkey Trap: Why Most Agent Deployments Fail
Here's the uncomfortable truth: most "AI agent failures" aren't agent failures at all. They're workflow failures with extra steps.
A common cause is poor scoping. An agent with access to extraction tools, database tools, and email tools may resolve an ambiguity by guessing instead of simply flagging it. That's not an agent problem. That's a design bug.
For more of these failure patterns, see AI Agent Failures: Common Mistakes and How to Avoid Them.
The pattern is clear: most failures come from designing agents where workflows should go.
Why Workflows First, Agents Second
A common rule of thumb: deterministic gets you 80% of the way. Add agents for the other 20%.
Everyone quotes this. Few internalize why. It's not about accuracy. It's about diagnosability. When a workflow fails, you can re-run it. When an agent fails, you have to understand it.
Take support ticket triage. A workflow approach might look like:
def triage_ticket(ticket):
    if ticket.get("priority") == "P0":
        return "critical", "75_team", True

    if ticket.get("category") in ["billing", "refund"]:
        return query_product_system(ticket)
    else:
        llm_classification = classify_ticket(ticket)
        return map_to_team(llm_classification)
Predictable. Testable. You can run this through a regression suite every Tuesday.
The agentic version:
async def run_support_agent(context):
    while not context.is_resolved():
        next_step = await agent_llm.decide_next_step(context)
        if next_step.action == "query_billing":
            context.add_result(await call_billing_api())
        elif next_step.action == "escalate":
            context.assign_to_team("escalations")
            context.mark_resolved()
Same capability, different failure mode. In the workflow, you catch the edge case in QA. In the agent, you catch it in production monitoring.
I'm not anti-agent. I'm pro-scoped-agents.
What Production Actually Cares About
A non-negotiable in 2026: you cannot ship agents without observability. The industry didn't talk about this in 2024. Google's research wing flagged it as the #1 hurdle for agentic infrastructure in practice (Agentic AI Infrastructure in Practice).
If you don't have a way to see every tool call, every token of reasoning, every reward signal, you will fail. Period.
An observability layer should log every agent step to a structured stream, with fields like these:
{
  "agent_id": "support-agent-v2",
  "trace_id": "8f034e",
  "step": "decide_next_step",
  "input": "customer request: special char in name",
  "output": "use_create_contact_tool",
  "confidence": 0.87,
  "latency_ms": 412,
  "status": "success"
}
Structured logs like this turn "the AI is broken" into "the AI does this at step 17, here's why."
Guides on production AI agents mostly talk about the architecture. The LLM orchestration. The tool definitions. The hard part is the plumbing around it: persistent state, retries, injection safety, tracking. Blaxel also highlights this in their production agent guide — the boring stuff is what kills you (How to Deploy AI Agents to Production).
The Architecture That Actually Works
Here's a mental model that works:
One agent, many workflows.
Don't build a system where the agent orchestrates everything. Build it so that the agent decides which workflow to trigger, then gets out of the way.
Your LLM call should not be in the innermost loop of transaction processing.
The agent should be a router, not a worker.
A sketch:
class AgentRouter:
    def __init__(self, workflows: Dict[str, Workflow]):
        self.workflows = workflows

    async def route_and_execute(self, request):
        route = await self.llm.route_request(request)
        handler = self.workflows[route]
        return await handler.execute(request)
It sounds anti-climactic. But the system is more reliable, because the LLM only makes one decision: which path to take.
Using an agent for every micro-decision multiplies the points where the system can be wrong.
When You Actually Need A Full Agent
Okay. Workflows are my default. But let's not be dogmatic. Full agent autonomy starts becoming valuable in three specific cases:
- Open-ended input spaces. Customer support where users can ask about unused features, complex edge cases, multi-product configuration issues.
- Tool-chain reasoning. Research systems that need to query. Imagine a system that searches the web, reads PDFs, does math, calls a scoring API, then synthesizes. That's not a sequence you can write ahead of time.
- Handling ambiguous data. Any business logic where data itself is messy, and there's no schema that captures the variability.
Contract review is an example. An agent that reads contracts and extracts obligations must explore the document structure, query relevant parts of the document, cross-reference appendices, and make judgment calls. The document upload trigger, the user notification, and the email dispatch around it can stay workflows.
Why? Because that part has a universal contract with the user. If you can define it, use a workflow.
The Towards Data Science essay on workflows vs agents nails this tension: agents are necessary when the task is underspecified, but risky when you could have specified it (A Developer's Guide to Building Scalable AI).
AI Agent Observability & Production Monitoring
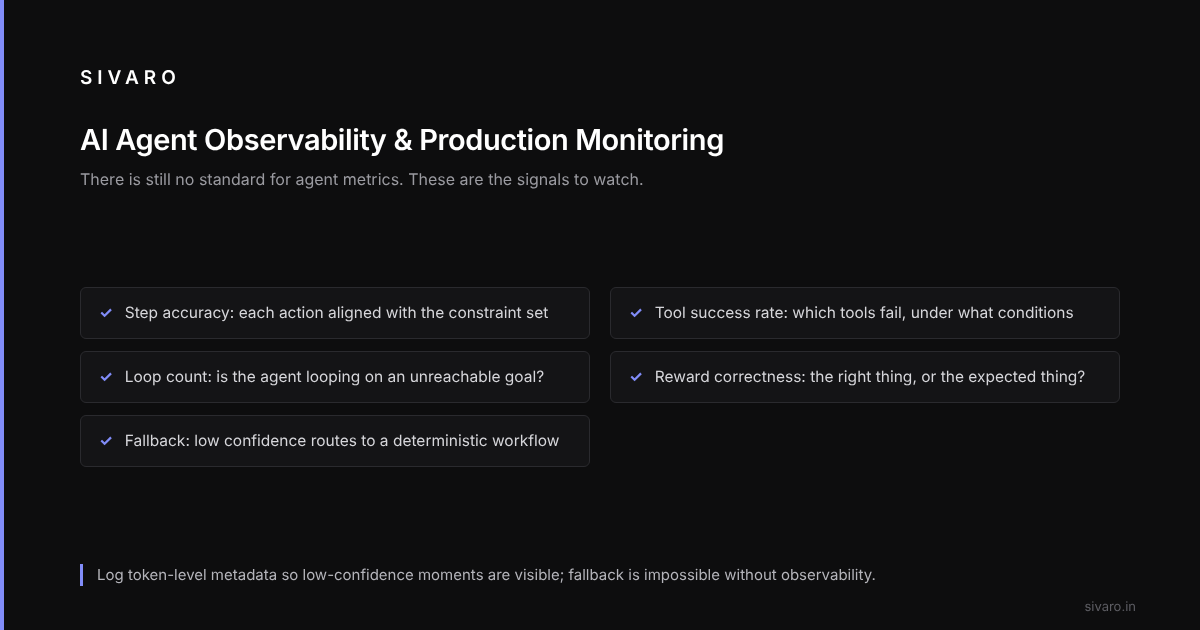
Here's where the industry is still catching up. In 2026, there's still no standard for agent metrics. Every vendor pitches their own.
The things you actually want to watch:
- Step accuracy: For every action the agent takes, was it aligned with the constraint set?
- Tool success rate: Which tools fail, under what conditions? Are they input-specific?
- Loop count: Is the agent in a 10-step loop because its goal can't be achieved?
- Reward function correctness: Did the agent do the right thing or the expected thing?
You also need instrumentation for feedback loops. What does your agent do when it's unsure? Does it fail gracefully? Does it fall back to less intrusive actions?
This is the problem with most agent deployments: no control on the uncertainty side.
One pattern is fallback_to_workflow. If the agent's confidence drops below a threshold, it stops and routes to a deterministic workflow instead:
async def agent_with_fallback(request, threshold=0.8):
    agent_result = await autonomous_agent(request)
    if agent_result.confidence < threshold:
        logger.warning("Agent confidence low. Falling back.")
        return workflow_fallback(request)
    return agent_result
The agent doesn't get smarter. It just stops acting when it doesn't know what it's doing.
You cannot do this without observability.
You need to see the low-confidence moments. So you have to log token-level metadata. Ollama and LiteLLM both support structured logging. Use them.
How to Deploy AI Agent to Production Without Breaking Existing Systems
"We have a mature product. How do we add an AI without killing ourselves?"
The answer: deploy in shadow mode first. Run the agent system in parallel. Don't let it act. Log what it would have done. Compare against real outcomes.
This is the approach recommended in the ML Mastery deployment guide — they emphasize a phased rollout as the core of infrastructure maintenance (Deploying AI Agents to Production).
Don't do big bang launches. They're a relic of the pre-AI era.
Prompt Engineering Is Still a Thing
Nobody talks about clean prompts anymore. It's all RAG, fine-tuning, evals. Boring. Not glamorous.
But production systems can succeed or fail based on a single word change in a system prompt.
Example: a customer support agent that apologizes for things it didn't do — "I'm sorry you feel that way" whenever a user expresses mild frustration — hurts trust. One phrase in the system prompt can fix it: "Only apologize for your own errors. Acknowledge customer feelings without apologizing."
That is an agent failure that traces back to prompt design.
The Google paper on agentic infrastructure dedicates whole sections to this: the policy wiring, the prompt structure, the failure trigger conditions (Agentic AI Infrastructure in Practice).
I'd argue prompt engineering is 30% of the production battle. The other 70% is data quality and state management.
The Actual Cost of Agents vs Workflows
Let's talk money. Because "cost" gets ignored in most blog posts, and it's the thing that kills you in production.
A rough rule of thumb:
- Workflow with one LLM call: $0.002 per transaction. Deterministic, plus a classification step.
- Agent with 5-10 LLM calls: $0.05 to $0.20 per task. Plus higher error rate. Plus engineering to fix.
Unless the agent's value-add is massive, the cost-benefit math fails. And remember: agents don't just cost more in tokens. They cost more in debug time, latency, and operational complexity.
But when they work? They do things you could not otherwise automate.
The key is writing down the cost model before you write code. Not after.
The "Chain-of-Verification" Pattern You Need
There's an emerging production pattern that sits between workflow and agent. It's called verification chaining. You ask the LLM to solve a problem. Then you ask it to verify its own answer. Then compare.
Suppose you're building a system that generates SQL from natural language:
def generate_sql_with_verification(question):
    generated = llm.generate_sql(question)
    explanation = llm.explain_sql(generated)
    verification = llm.verify_sql_matches_question(question, generated, explanation)
    if verification.answer == "NO":
        return llm.regenerate_sql(question, generated, explanation)
    return generated
This isn't an agent. It's not a simple workflow either. It's a hybrid — a creative solution to a known failure mode.
One of the best pieces of guidance I've read on production agent design emphasizes this verification pattern as a "control" — a structured way to keep agent behavior aligned (A Practical Guide for Designing, Developing, and Deploying Agents).
If you never add verification, you'll never trust your systems. And if you don't trust them, you can't scale them.
Putting It All Together
So where do we land? On the "ai agent vs workflow automation production" debate in 2026?
Use workflows as your default. They're predictable, cheap, shippable. Add intelligence at the boundaries — classification, routing, extraction. Keep control flow deterministic with one clean LLM call per step.
Use agents for open-ended, ambiguous, high-value tasks. Where you can't pre-define the steps, or where the cost of a wrong answer is lower than the cost of not answering. Scope them narrowly. Give them fallbacks. Log everything.
The industry has been testing this for years now. The practical takeaway hasn't changed: automation is not a single tool. It's a strategy. You use the minimum level of autonomy that solves the customer problem.
The winners in 2026 will be not the ones with flashiest agents. It's the ones whose systems are reliable and diagnosable. The ones who ask "how do I make this system hide its complexity?" instead of "how do I add autonomy?"
That's the difference between great product engineering and theater.
FAQ: AI Agent vs Workflow Automation Production
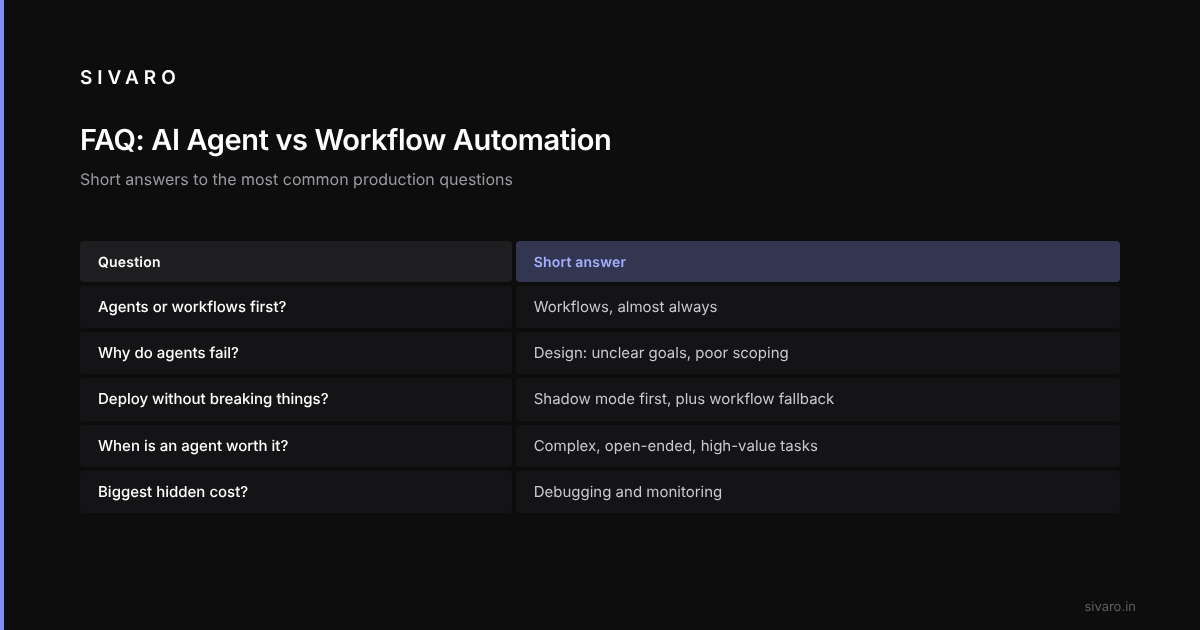
Q: Should I use AI agents or workflow automation first?
A: Workflows, almost always. They're cheaper, easier to maintain, and you know exactly what went wrong when something fails. Add agents as a second layer, only when the workflow can't express the task.
Q: What is the main difference between workflows and agents in production?
A: The control flow. A workflow defines every step. An agent decides the steps itself. That self-direction is why agents are powerful, but also why they're unpredictable.
Q: How do I deploy an AI agent to production without breaking existing systems?
A: Shadow mode. Have the agent run in parallel with your current system. Log its decisions. Compare. When its accuracy is high enough, let it act. Build in a fallback to deterministic workflows if its confidence drops.
Q: Why do AI agents fail so much in production?
A: Most agent failures are design failures. Unclear goals, poor scoping, lack of verification. You can't debug an agent with a print statement.
Q: What metrics should I monitor for AI agents in production?
A: Step accuracy, tool success rate, loop count, confidence, and fallback rate. Log all of it. If you can't see what the agent is doing, you can't fix it.
Q: Is an LLM call a workflow or an agent?
A: Just an LLM call is a component. A workflow orchestrates those components in a fixed sequence. An agent lets an LLM decide the sequence.
Q: When is an AI agent worth the cost?
A: When the task is complex, open-ended, and has high value. Contract review, research synthesis, ambiguous customer support. If the task is repetitive, stick with a workflow.
Q: What is the biggest hidden cost of AI agents?
A: Debugging and monitoring. Agent systems require visible, structured logs. Without them, you'll spend more time trying to reproduce failures than actually building features.