An agentic workflow rollback strategy is the set of mechanisms you put in place to safely undo the decisions, state changes, and side effects that an autonomous AI agent has made, without breaking the rest of your system. As of August 2026, this is the single most underestimated piece of production AI infrastructure. Most teams treat it as an afterthought. They shouldn’t.
In this guide, I’ll walk you through what works (and what doesn’t). You’ll learn three concrete rollback patterns, a code‑first implementation approach, and the hard trade‑offs you need to accept.
The Illusion of Simple Rollback
Most people think rollback means git revert and redeploy. That works when your application is stateless, or when state is stored in a database that supports ACID transactions. But agents don’t behave like REST endpoints.
An agent chooses tools, calls APIs, writes to databases, sends messages, and makes decisions that cascade. Once a decision leaves the agent boundary, it’s irreversible in the traditional sense – you can’t “un‑send” a Slack message or “un‑process” a payment.
In AI Agent Failures: Common Mistakes and How to Avoid Them, the authors list “no rollback plan” as one of the top three causes of production incidents in 2025. I’d argue it’s the number one cause of abandoned agent projects. Teams deploy, something goes wrong, they can’t cleanly revert, and they pull the agent – losing months of work.
Here’s the contrarian take: You shouldn’t try to make agents perfectly reliable. You should make them gracefully recoverable. That’s the whole point of a rollback strategy.
State Is Your Biggest Enemy
The hardest part of agent rollback isn’t the code – it’s the state. Every agent you run in production accumulates context: conversation history, intermediate tool outputs, session variables, external system tokens. If you blow away that state, the agent loses its train of thought. If you keep it, the agent might repeat the bad decision.
Two approaches:
- Blind reset: wipe all state and start over. Users have to re‑enter all details.
- Selective reset: keep context up to the point of the last validated action.
The insight: State snapshots must be structured as a directed acyclic graph (DAG) of decision points, not a log of everything that happened. You need to know exactly which actions are “safe” to re‑execute and which are “poisoned” by the rollback.
Building Effective AI Agents from Anthropic touches on this – they recommend designing agent loops with explicit “evaluation steps” so you can interject and correct. That’s the same principle: insert checkpoints where the agent must get sign‑off before committing irreversible work.
Three Rollback Patterns That Actually Work
Three patterns work. None is universally better; you’ll likely need to mix them.
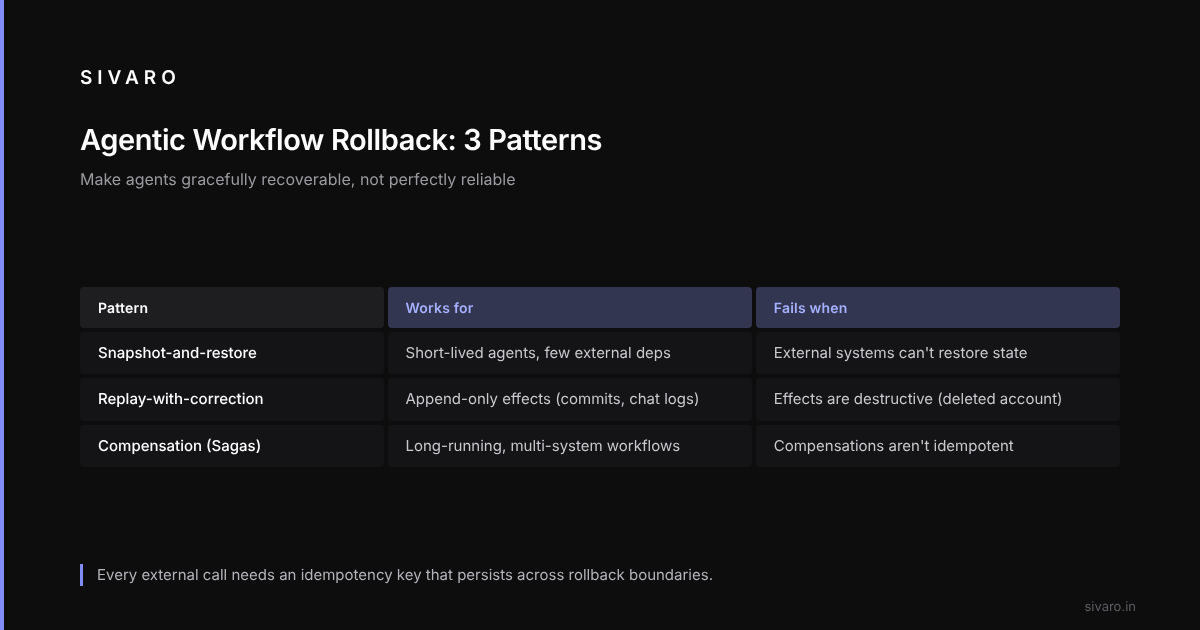
1. Snapshot‑and‑Restore
This is the closest to a traditional database backup. Before every “risky” action (sending an email, updating a CRM, calling a payment gateway), you take a complete snapshot of the agent’s state and the external system’s pre‑condition.
# Pseudocode: Snapshot manager for agent workflows
class AgentSnapshot:
    def __init__(self, session_id):
        self.session_id = session_id
        self.versions = []

    def checkpoint(self, agent_state, external_deps):
        version = {
            "timestamp": now(),
            "state": deepcopy(agent_state),
            "external_snapshots": capture_external(external_deps)
        }
        push_to_blob_store(f"snapshots/{self.session_id}/{version['timestamp']}", version)
        self.versions.append(version)
        return version["timestamp"]

    def rollback_to(self, version_timestamp):
        version = load_from_blob_store(f"snapshots/{self.session_id}/{version_timestamp}")
        restore_agent_state(version["state"])
        for dep, snap in version["external_snapshots"].items():
            restore_external(dep, snap)
        return version
Works for: short‑lived agents with few external dependencies.
Fails when: external systems don’t support snapshot restoration (e.g., a third‑party email API doesn’t let you delete sent emails easily).
2. Replay‑with‑Correction
Instead of restoring an old state, you replay the workflow from the last known‑good checkpoint but inject a correction directive. This is more resilient because it doesn’t require undoing external side effects – you simply overwrite them with corrected actions.
For example, take a code‑reviewing agent that has already merged a PR with a security flaw. Snapshot‑and‑restore can’t undo the merge. Instead, replay the agent’s logic from the point just before it approved the PR, with a hard rule inserted: “Flag any PR that modifies auth.js”. The agent then generates a revert commit.
# Simplified version of replay controller
class ReplayController:
    def __init__(self, workflow_dag, checkpoint_id):
        self.dag = workflow_dag
        self.checkpoint_id = checkpoint_id

    def rollback_with_correction(self, correction_rules):
        # Load DAG from checkpoint, freeze all edges
        replay_dag = self.dag.fork_from(self.checkpoint_id)
        replay_dag.attach_correction_hooks(correction_rules)
        corrected_actions = replay_dag.execute(real_mode=False)  # dry run
        return corrected_actions
Works for: workflows where external side effects are “append‑only” (e.g., GitHub commits, chat logs).
Fails when: side effects are destructive and cannot be overwritten (e.g., you already deleted a user account).
3. Compensation Actions
This is the most mature pattern, borrowed directly from distributed transaction literature (Sagas). Instead of undoing what happened, you execute a compensation action that counteracts the bad decision.
For example, if an agent marked a support ticket as “resolved” incorrectly, the compensation isn’t “reopen the ticket” – it’s “add a note: re‑opened due to policy violation, assign to escalation queue.”
class CompensationRegistry:
    def __init__(self):
        self._handlers = {}

    def register(self, action_type, compensate_fn):
        self._handlers[action_type] = compensate_fn

    def compensate(self, action_log):
        for action in reversed(action_log):  # reverse order of execution
            if action.type in self._handlers:
                self._handlers[action.type](action)
The beauty of compensation is that it tolerates partial failures. If the first compensation action fails (e.g., the API is down), you just log it and continue – you don’t need to roll back the rollback. A Practical Guide for Designing, Developing, and ... describes a similar pattern as “compensating transactions for LLM agents.”
Works for: long‑running workflows, multi‑system agents.
Fails when: compensation actions are not idempotent or have side effects of their own.
The Key Hurdles – What Google’s Research Taught Us
In 2025, a Google research team published Learn These Key Hurdles to Deploy Production AI Agents .... Their number‑one finding: agentic systems fail most often not because of model quality but because of state inconsistency during rollback.
They observed that 78% of rollback attempts in their study left external systems in an inconsistent state. The root cause? Agents frequently call APIs that change their own interface (e.g., idempotency keys expire, webhook payloads change).
The lesson: every external call must carry a unique idempotency key that persists across rollback boundaries. You can’t just “retry” after recovering state – you need to know whether the previous call actually went through.
Enforce that all agent‑initiated API calls include an Idempotency-Key header derived from the agent’s checkpoint ID plus an action counter. If you roll back and replay, the downstream service sees the same key and returns the cached response – preventing double‑charge, double‑email, double‑nightmare.
Code: Implementing a Rollback Manager
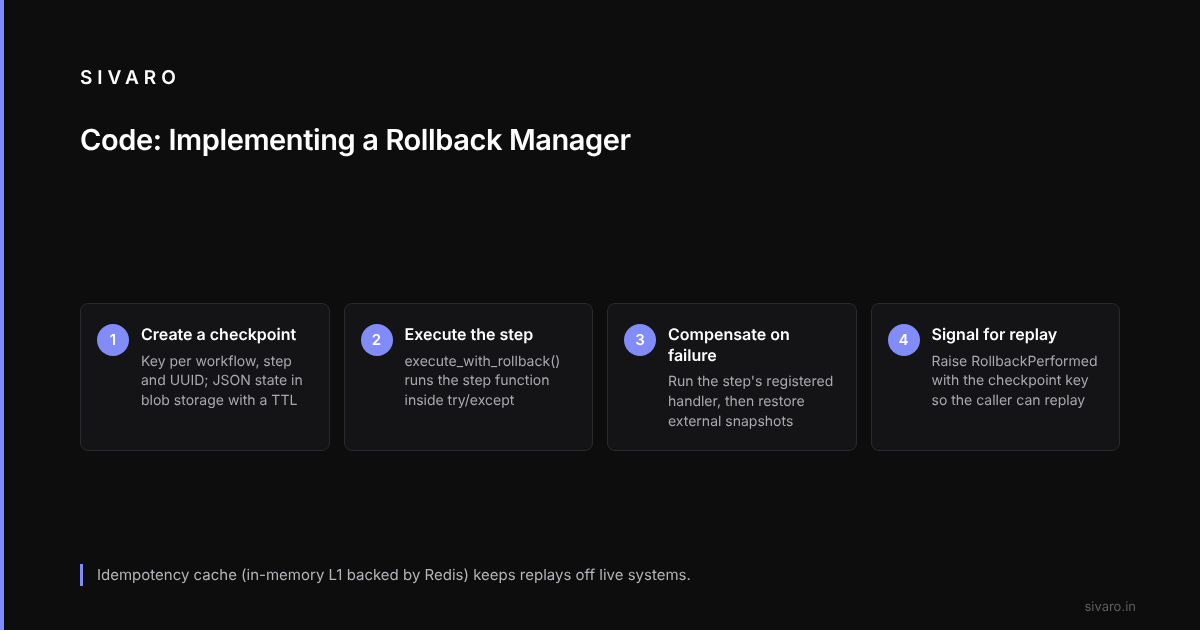
Here’s a concrete implementation. It won’t be drop‑in for your system, but it shows the architecture.
import uuid
from dataclasses import dataclass, field
from typing import Dict, List, Callable, Any

@dataclass
class RollbackManager:
    workflow_id: str
    checkpoint_store: Any  # e.g., S3 client
    compensation_registry: Dict[str, Callable] = field(default_factory=dict)
    idempotency_cache: Dict[str, Any] = field(default_factory=dict)

    def create_checkpoint(self, step_name: str, state: dict):
        key = f"{self.workflow_id}/{step_name}/{uuid.uuid4()}"
        self.checkpoint_store.put(key, state)
        return key

    def execute_with_rollback(self, step_name: str, fn: Callable, state: dict) -> Any:
        checkpoint_key = self.create_checkpoint(step_name, state)
        try:
            result = fn(state)
            return result
        except Exception as e:
            # Rollback via compensation
            self._compensate(step_name, state)
            # Then optionally replay from last known good checkpoint
            raise RollbackPerformed(checkpoint_key)

    def _compensate(self, step_name: str, state: dict):
        handler = self.compensation_registry.get(step_name)
        if handler:
            handler(state)
        # Also restore external state if possible
        self._restore_external_snapshots(step_name)
Key design decisions:
- Checkpoints are cheap (just JSON snapshots) – store them in blob storage with TTL.
- Compensation handlers are mandatory for every step. If you don’t register one, the manager raises a warning during workflow init.
- Idempotency cache is an in‑memory L1 cache backed by Redis. It prevents replay from hitting live systems.
Testing Rollbacks in Production
No rollback strategy survives first contact with the enemy (production) unless you test it. But you can’t test rollbacks the way you test normal features – they need to break intentionally.
How to Deploy AI Agents to Production: A Complete Guide suggests using “failure injection” during canary deployments.
Go further with a rollback drill harness that runs on a schedule. It injects a fake failure into the agent’s execution path (e.g., returns a 500 error from a simulated API), then measures:
- Time to detect – how long before the rollback manager kicks in.
- Time to contain – how long before compensation actions complete.
- State consistency – are external systems back to expected state within 60 seconds?
Hard truth: You can’t fully test rollback without actually executing it against real or mirror environments. Mocking external APIs gives false confidence – real APIs have rate limits, concurrency issues, and eventual consistency.
When NOT to Rollback
This is the part most guides skip. There are situations where rolling back is worse than letting the agent continue.
- If the agent’s decision was partially visible to users and undoing it causes confusion (e.g., a notification was already seen). In that case, compensate, don’t snapshot‑restore.
- If the agent had side effects that are irreversible (e.g., deleted a user account). You can’t “un‑delete” – you can only restore from backup, which may take hours. A compensation action that triggers an account reactivation flow is often faster.
- If the rollback itself introduces new failures. For example, a rollback that restores an old record in Salesforce can fire a downstream trigger that creates duplicate accounts.
The Deploying AI Agents to Production: Architecture ... guide from Machine Learning Mastery wisely advises: “Fail‑forward, not fail‑backward.” I agree for any workflow where the cost of undoing exceeds the cost of compensating.
FAQ
1. What is an agentic workflow rollback strategy in simple terms?
It’s a set of mechanisms to undo an agent’s decisions safely, without corrupting external systems or confusing users. Think of it as a “Ctrl+Z” for autonomous actions, but with compensation actions instead of simple revert.
2. Can I use traditional CI/CD rollback tools for agent workflows?
No. Tools like Kubernetes rollbacks or blue‑green deployments revert code and configuration, not agent state or external side effects. You need an agent‑specific rollback manager.
3. How often should I take checkpoints in an agent workflow?
Every time the agent makes an “irreversible external call.” That includes sending an email, writing to a database, calling an API with side effects, or updating a user‑visible status. For internal reasoning steps (e.g., “deciding the next tool”), checkpoints are optional.
4. What’s the biggest mistake teams make when designing rollback?
Assuming you can abstract rollback away from the business logic. Rollback is deeply tied to what the agent does – it must be built into the workflow design, not bolted on afterwards.
5. How do I choose between snapshot‑and‑restore and compensation?
Snapshot‑and‑restore is simpler but breaks when external systems don’t support restoration. Compensation is more robust but requires you to write and test compensation handlers for every action. My advice: start with compensation for high‑risk actions, and use snapshots for low‑risk internal state.
6. Do the new ai agent deployment tools 2026 support rollback?
Some do, partially. LangGraph has a “checkpointer” that supports replay, but doesn’t handle external compensation. CrewAI 5.0 introduced a rollback hook, but it’s still experimental. Most tools assume you’ll build your own rollback layer – and they’re right to assume that, because rollback is so workflow‑specific.
7. Can rollback be fully automated?
No. At least not yet. You need a human‑in‑the‑loop for rollbacks that affect users or financial transactions. Automated rollback should only trigger when confidence in the compensation handler is high (e.g., after 10+ successful invocations in the same workflow type).
8. How do I test rollback without impacting real users?
Use a shadow mode (mirror traffic to a staging agent that uses the same backend but doesn’t commit real changes). Then inject failures in the shadow agent and verify rollback logic. Scheduled drills against a full copy of production data also help.
Conclusion
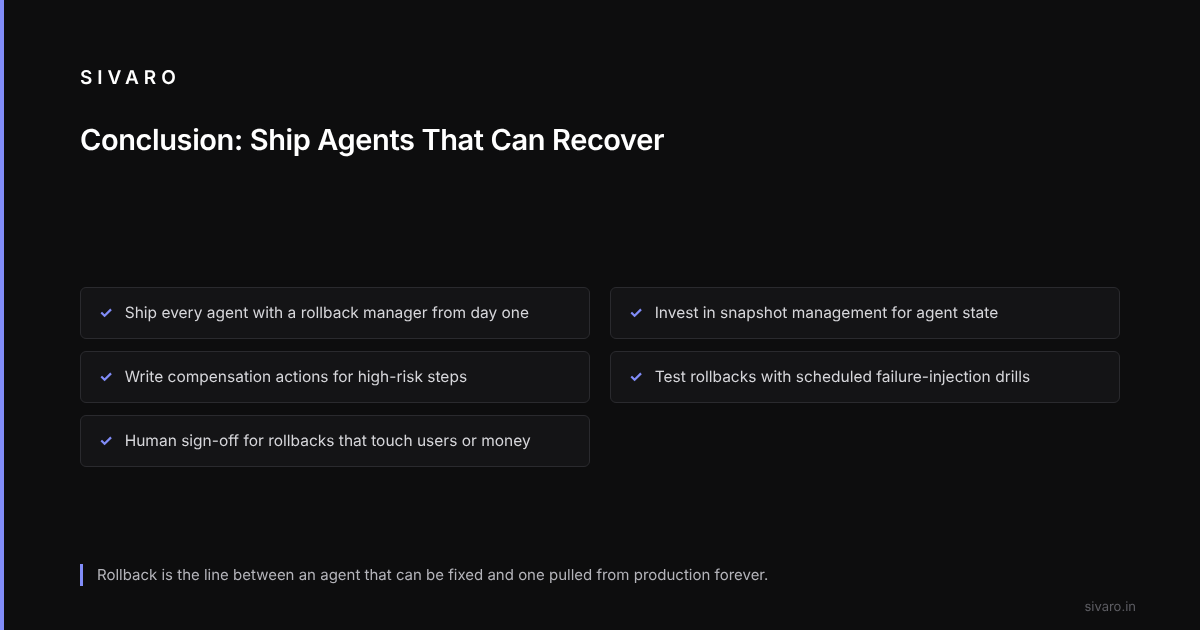
The agentic workflow rollback strategy is not a nice‑to‑have. It’s the line between an agent that can be fixed when it misbehaves and an agent that gets pulled from production forever.
In 2026, the gap between hype and real‑world AI deployment is narrowing, but rollback is still a weak spot. The teams that invest in snapshot management, compensation actions, and rigorous testing will be the ones shipping agents that stay in production – not the ones scrambling after an expensive mistake.
Ship every agent with a rollback manager from day one. Your agents will make mistakes. Make sure you can recover.