Kafka's partition strategy determines how data is distributed across brokers, how consumers parallelize, and — more than most teams realize — whether your system survives traffic spikes without collapsing. Getting it wrong doesn't just mean slower throughput. It means ordering guarantees break, consumer lag explodes, and you end up spending weekends rebalancing.
What you'll get from this guide: code examples showing what actually works, and a clear-eyed view of when Kafka's partition model is your best friend and when it's a trap. I'll also tell you where Kafka falls short compared to newer systems like Pulsar, because pretending it's perfect helps nobody.
Let me start with the mistake that costs teams the most.
Why Partition Count Still Bites People
Most engineers think "more partitions = more throughput." They're half right.
Confluent's benchmarks show that each partition adds roughly 1-2 ms of metadata overhead per broker (Kafka vs Pulsar - Performance, Features, and Architecture). Doesn't sound like much. Scale to 10,000 partitions and you're eating 10-20 seconds of overhead every time the controller needs to do anything.
The fix isn't "use fewer partitions." It's understanding what your partition count is buying you.
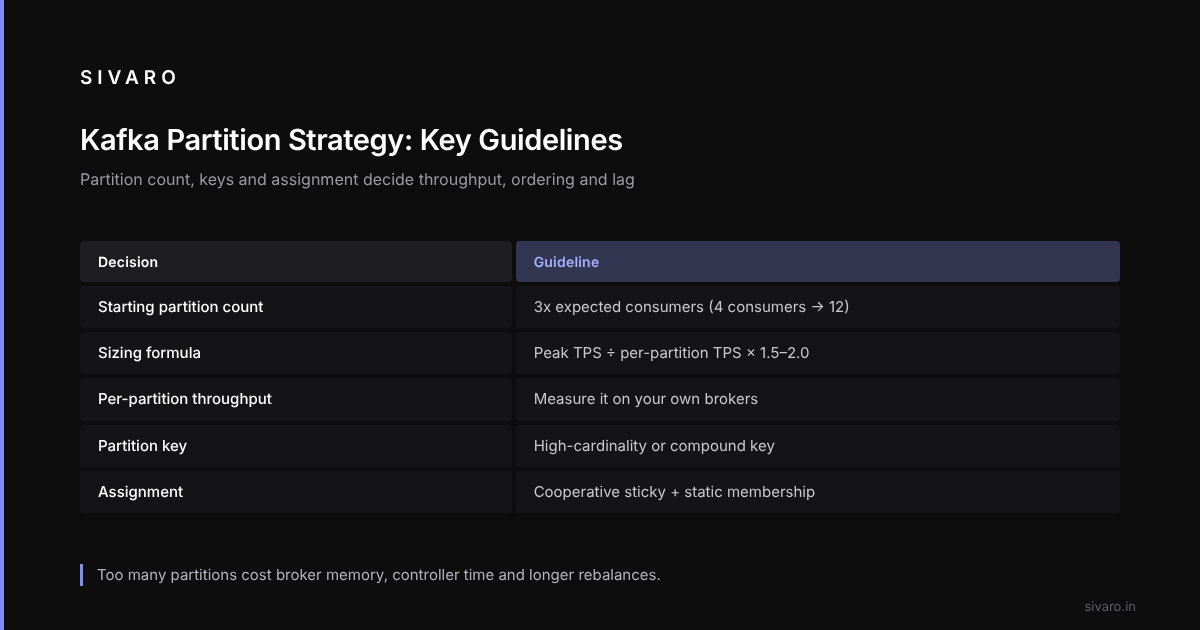
Rule of thumb I use: partitions = max(consumers in a consumer group expecting to parallelize, expected throughput / per-partition throughput capacity). I'll walk through the math later.
The Cardinality Trap: Keys Aren't Free
"I'll just use a random key to distribute evenly." That plan often ends in a production incident.
Kafka partitions messages by hashing the key. If your key has low cardinality — say, customer tier (gold, silver, bronze) — you get three heavily imbalanced partitions. Gold customers produce 10x more events than Bronze. Your Gold partition saturates. Consumers on Bronze sit idle.
What works: Use a compound key. Prefix the natural key with a hash of something high-cardinality. Or switch to a custom partitioner (I'll show code below). And monitor partition size ratios daily. If any partition grows more than 20% faster than the average, investigate.
Throughput vs. Ordering – The Real Trade-off
Most people think partition ordering is free. It's not.
Kafka guarantees order within a partition. If you need global ordering across all events, you're limited to one partition. That kills throughput. Timestamp-ordering at the consumer doesn't work around this, because Kafka doesn't guarantee global time order across partitions.
Here's the honest trade-off: if you need strict ordering, accept lower throughput. If you need high throughput, redesign your system to not require global ordering.
Take player move events that need per-game ordering. That's a partition key of game_id. Fine — until one game has 100,000 players. That game's partition is now a bottleneck.
The smarter approach: Use a two-level partition scheme. First partition by game region, then by game ID. Or use a time-bucketed key. Or — and this is where Kafka's model starts to feel limiting — consider Pulsar, which handles per-message ordering differently with less overhead (Pulsar vs Kafka - Comparison and Myths Explored).
Partition Assignment Strategies You Should Know
Kafka's consumer group rebalancing protocol has three main strategies: Range, RoundRobin, and Sticky.
Range (default): Assigns contiguous ranges of partitions to each consumer. Problem: if you have more consumers than partitions, some consumers get nothing. A 12-consumer group with 6 partitions leaves 6 consumers idle. Range doesn't handle uneven subscriber-to-partition ratios well.
RoundRobin: Distributes partitions evenly across consumers. Fixes the idle consumer issue. But every rebalance means a full stop-the-world reassignment. In 2024 Kafka 3.7 introduced cooperative rebalancing, which helps, but RoundRobin still causes more churn than Sticky.
Sticky: Minimizes partition reassignment during rebalances. If a consumer dies, only that consumer's partitions get reassigned. Everyone else keeps their assignments. This is the best for high-throughput production systems where you can't afford long rebalance pauses.
My recommendation: Use StickyAssignor unless you have a specific reason not to. Set group.instance.id for static group membership to prevent unnecessary rebalances entirely if consumers are predictable.
How to Rightsize Partitions (Without Guessing)
Stop treating partition count as a set-it-and-forget-it number. It changes as your traffic grows.
Here's the formula:
Target partitions = (Peak TPS / Per-partition throughput) × Safety factor
Per-partition throughput depends on your hardware and configuration, so measure it on your own brokers.
Safety factor: 1.5 to 2.0. You need headroom for rebalances and traffic spikes.
But don't go overboard. Kafka documentation recommends no more than 4,000 partitions per broker. Confluent's comparison with Pulsar highlights that Pulsar handles multi-tenancy and high partition counts more natively (Kafka vs Pulsar: Streaming Platform Comparison), but for Kafka you need to stay disciplined.
Another key number: Max partitions per topic before consumer lag becomes unpredictable — around 1,000 on a small cluster. Beyond that, monitor consumer rebalance time. If it exceeds 5 seconds, you're over-partitioned.
When to Rebalance – and When Not To
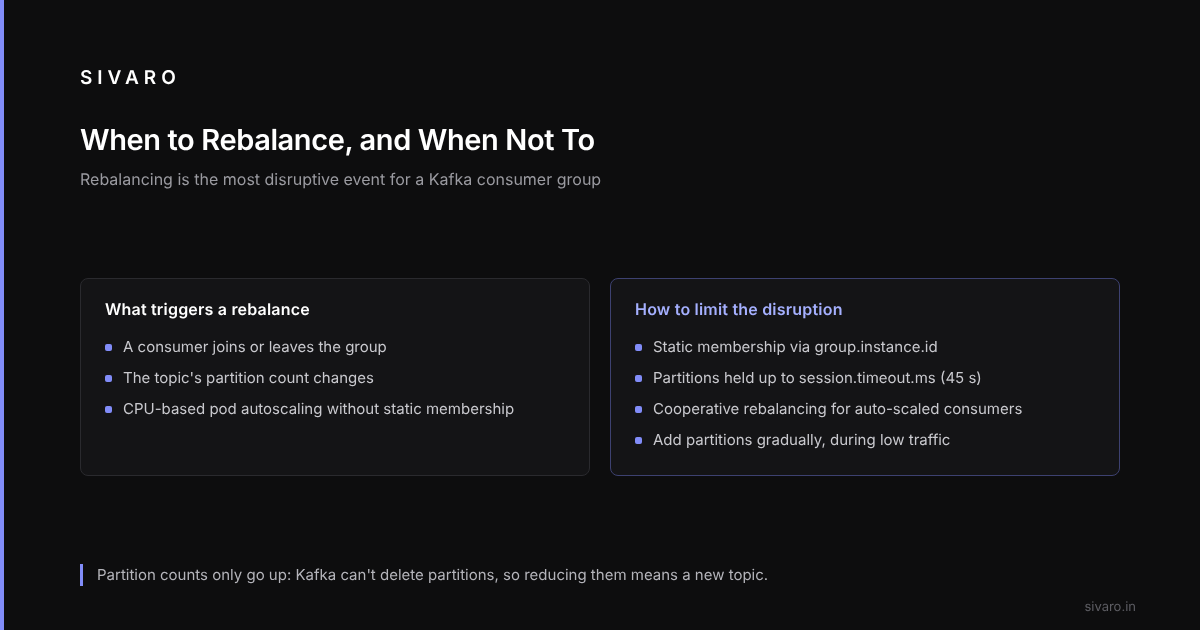
Rebalancing is the most disruptive event in a Kafka cluster. Every rebalance pauses consumption for all consumers in the group.
Two scenarios cause rebalances:
- Consumer joins or leaves the group.
- Partition count changes on the topic.
Obvious trigger to avoid: auto-scaling consumers without static membership. If you use Kubernetes and scale pods based on CPU, every pod start or stop triggers a rebalance. That's milliseconds of disruption per event, but if you're scaling every 30 seconds, you spend half your time rebalancing.
Fix: Use static group membership (group.instance.id) for long-lived consumers. It tells Kafka: "this consumer will come back." Kafka holds its partitions for up to session.timeout.ms (default 45 seconds). For auto-scaled consumers, increase this timeout and use cooperative rebalancing.
When you must rebalance: Only when you need to change the number of partitions. Do it during low traffic. Increase partitions gradually — not by 100 at a time. Each partition increase triggers a reassignment for all consumers in that group.
One more thing: never decrease partitions. Kafka doesn't support partition deletion. You'd have to create a new topic and migrate. Plan your partition count to be a ceiling, not a floor.
Monitoring Partition Health in Production
You can't manage what you don't measure. Here's what to monitor for every partition-focused deployment:
- Partition size growth rate – any partition growing faster than 20% of the median gets flagged.
- Consumer lag per partition – not just total lag. If one partition has 10x the lag of others, your key distribution is broken.
- Time since last rebalance – if rebalances happen more than once per hour during normal operation, something's wrong.
- Broker partition count – keep a dashboard with per-broker partition count. Single-broker overload is a common failure mode.
A simple exporter can expose these metrics as Prometheus gauges, with an alert when any partition's consumer lag exceeds 10 seconds for more than 5 minutes.
Kafka vs Pulsar vs RabbitMQ: Partitioning Lessons
Let's be honest for a second. Kafka's partition model is old. It works. But it has inherent limitations that newer systems address.
Pulsar uses a two-layer architecture: topic data is stored in a log (BookKeeper) and served via brokers that cache. Pulsar partitions are virtual — you can change the number of partitions without data migration. That's a huge operational win. And Pulsar handles higher partition counts per broker without degradation (Kafka vs Pulsar vs RabbitMQ vs NATS: What's Actually ...).
RabbitMQ, on the other hand, is not a log-based system. It's a message broker with queuing semantics. Partitioning isn't native — you'd use multiple queues with a routing key. For workloads needing strict ordering and replay, Kafka wins. For RPC-style messaging with complex routing, RabbitMQ wins (What's the Difference Between Kafka and RabbitMQ?).
Where does Kafka still dominate in 2026? High-throughput event streaming with replayability. Most real-time analytics pipelines are still Kafka-based. The partition strategy I've described applies directly.
Where Kafka loses? Multi-tenant deployments and high partition counts. If you have 100 topics each with 100 partitions, you're at 10,000 partitions. Pulsar handles that more gracefully.
Code Examples: Partitioning in Action
Let me show you what these strategies look like in practice.
Custom Partitioner with Key Hashing
// Java 17, Kafka 3.7+
public class CompoundKeyPartitioner implements Partitioner {
    @Override
    public int partition(String topic, Object key, byte[] keyBytes,
                         Object value, byte[] valueBytes, Cluster cluster) {
        List<PartitionInfo> partitions = cluster.partitionsForTopic(topic);
        int numPartitions = partitions.size();

        // Use a compound key: high-cardinality prefix + original key
        String composite = UUID.randomUUID().toString().substring(0, 8) + ":" + key;
        int hash = composite.hashCode();
        return Math.abs(hash) % numPartitions;
    }
}
This avoids the cardinality trap by mixing in a random prefix. Trade-off: you lose ordering on the original key. If you need per-key ordering, don't randomize. Use the key as-is and monitor hot partitions.
Kafka Producer Callback Example
// kafka producer callback example – handling failures gracefully
producer.send(new ProducerRecord<>("orders", orderKey, orderJson),
    new Callback() {
        @Override
        public void onCompletion(RecordMetadata metadata, Exception e) {
            if (e != null) {
                log.error("Failed to send order {} to partition {}: {}",
                    orderKey, metadata.partition(), e.getMessage());
                // Retry with exponential backoff
                retryLater(orderKey, orderJson, metadata.partition());
            } else {
                log.info("Sent order {} to partition {} at offset {}",
                    orderKey, metadata.partition(), metadata.offset());
                metrics.incrementPartitionSend(metadata.partition());
            }
        }
    });
This is your standard callback. The "pro tip" is logging the partition ID so you can spot skew. If you see 90% of sends going to partition 0, fix your partitioner.
Monitoring Partition Consumer Lag
# Python + kafka-python 3.0
from kafka import KafkaConsumer, KafkaAdminClient
import time

consumer = KafkaConsumer(
    'my-topic',
    bootstrap_servers=['localhost:9092'],
    group_id='my-group'
)

admin = KafkaAdminClient(bootstrap_servers=['localhost:9092'])
end_offsets = admin.list_consumer_group_offsets('my-group')

for partition in consumer.partitions_for_topic('my-topic'):
    consumer.assign([partition])
    consumer.seek_to_end(partition)
    latest = consumer.position(partition)
    committed = end_offsets[partition].offset
    lag = latest - committed
    print(f"Partition {partition}: lag {lag}")
    if lag > 10000:
        alert_team(f"High lag on partition {partition}: {lag}")
Run this every 60 seconds. If any partition's lag exceeds 10K, you've got a partition strategy problem.
FAQ: Kafka Topic Partition Strategy
Q: How many partitions should I start with?
A: Start with 3X the number of consumers you expect to run. So if you plan 4 consumers, start with 12 partitions. Monitor throughput and add partitions as needed. Don't start with 1.
Q: Can I change partition count after the topic exists?
A: Yes, you can increase it using kafka-topics.sh --alter --partitions. But it triggers a rebalance. Do it during low traffic. And never try to decrease — that's not supported.
Q: What happens if I set partition count too high?
A: More rebalances, higher memory usage on brokers, slower controller operations. At extreme counts (10K+), you might see request timeouts. Confluent's Kafka vs Pulsar paper shows Pulsar partitions have lower overhead per unit (Kafka vs Pulsar - Performance, Features, and Architecture).
Q: Should I use a custom partitioner or default hash?
A: Default hash is fine if your key cardinality is high and uniformly distributed. If you have hot keys, use a custom partitioner that spreads them artificially. But accept the ordering trade-off.
Q: Is Kafka or RabbitMQ better for partitioning in 2026?
A: Different tools. Kafka is built for partitioning and replay. RabbitMQ is built for routing and fine-grained acknowledgments. If your workload is event streaming, Kafka. If it's task distribution, RabbitMQ. The kafka vs rabbitmq 2026 conversation still comes down to that fundamental difference.
Q: How does Pulsar's partition model compare?
A: Pulsar allows dynamic partition count changes without rebalancing. It also supports per-message ordering with less state overhead. If you're starting fresh, I'd evaluate Pulsar strongly for multi-tenant streaming (Pulsar vs Kafka - Comparison and Myths Explored).
Q: Do I need to think about partitions if I use Kafka with Schema Registry?
A: Yes. Schema evolution doesn't affect partitioning. Partition strategy is orthogonal to schema management. You still need to manage partition counts and keys.
Q: What's the fastest way to debug partition imbalance?
A: Use kafka-consumer-groups.sh --bootstrap-server localhost:9092 --group my-group --describe and look at the LAG column. High variance = imbalance. Then check partition size with kafka-log-dirs.sh across brokers.
Conclusion
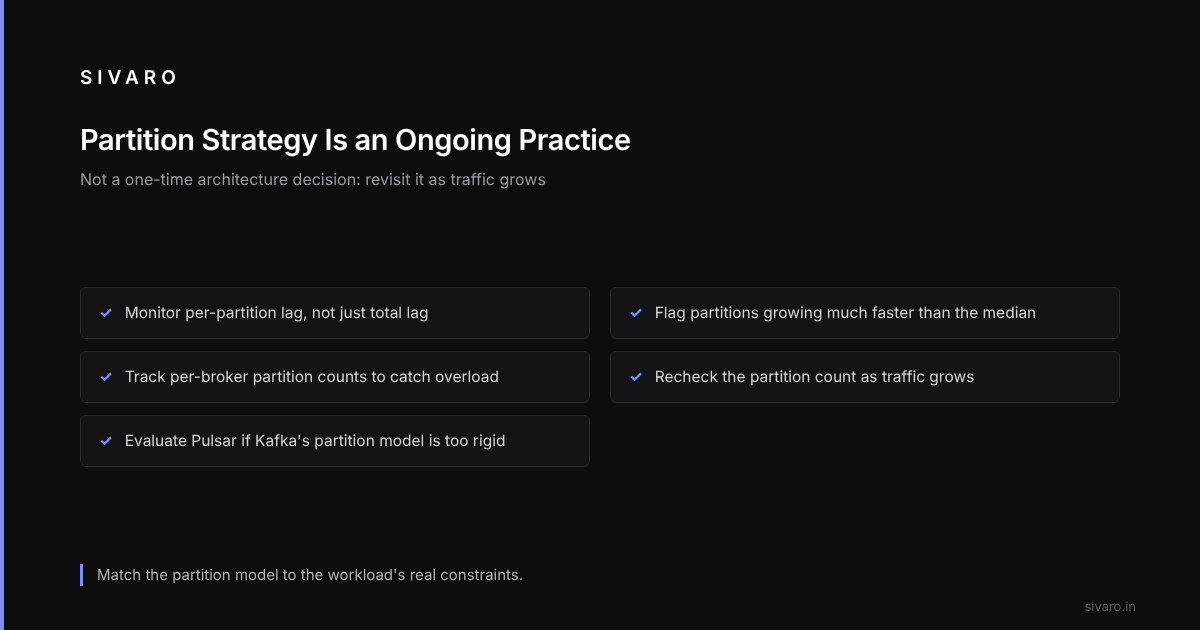
Partition strategy isn't a one-time architecture decision. It's a recurring operational practice. Most teams get it wrong because they treat it as configuration, not as a evolving system.
Kafka topic partition strategy best practices aren't complicated. Use a high-cardinality key (or compound key). Rightsize partitions based on your throughput and parallelism needs. Monitor per-partition lag like it's your job. And when the system demands more flexibility than Kafka's partition model provides, don't be afraid to evaluate Pulsar.
In 2026, the conversation isn't Kafka vs RabbitMQ vs Pulsar as a religious war. It's matching the partition model to your workload's real constraints. I'll take a well-partitioned Kafka topic over a misconfigured Pulsar cluster any day. But I'd rather see people use the right tool from day one.