So you've decided to delete a Kafka topic. Good luck. Outages happen because someone thinks kafka-topics.sh --delete will actually delete something. It won't, most of the time, unless you understand the half-dozen ways it silently fails. And resetting offsets? That's a different beast entirely.
This guide covers the exact commands, the traps that bite, and the order of operations that cleans up production clusters without causing a rebalancing stampede. You'll learn the honest answer to what happens to your consumer groups, why lag monitoring matters before and after the reset, and the one trick most people miss when they think they've deleted a topic.
Before You Delete Anything: Check Your Broker Config
The first thing to check on any cluster is delete.topic.enable. After 2024's Kafka 4.0 migration wave, most clusters have it set to true by default. But legacy setups still exist from an era when someone turned it off to prevent accidental data loss. That's how you end up with the most common "delete failed" error you'll ever see.
Run this:
# Check the broker config
kafka-configs.sh --bootstrap-server localhost:9092   --entity-type brokers --entity-name 0 --describe | grep delete
If it shows delete.topic.enable=false, you have two options. Either set it from the server config file and restart brokers, or use kafka-configs.sh --alter to change it dynamically. Dynamic is better. I never restart a whole cluster for a topic deletion.
Also note: even with the flag enabled, deletion is asynchronous. The --delete command returns immediately. The topic stays in a 'marked for deletion' state until the controller processes it. On a busy cluster, that can take thirty seconds or more. People sometimes panic and re-create the topic before the old one has finished dying. Don't be that person.
The Delete Command and Why It Sometimes Fails
The standard command looks simple:
kafka-topics.sh --bootstrap-server localhost:9092 --delete --topic orders
But "topic successfully deleted" in the output doesn't mean it's gone. It means the topic was marked. You need to verify with --list or --describe. And even then, you'll see something odd: the topic name still shows up in the list for a while.
Why? Because partition replicas on each broker need to be cleaned up. That's handled by background threads. If a broker is under heavy load, or the partition files are huge, deletion can take minutes.
The real trap is this: you can't delete a topic if there are active consumer groups still using it. The broker will block the deletion. The fix is to identify and stop the consumers first.
Check groups consuming from the topic:
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --list
Then for each group, find the topic:
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --describe --group order-processors
Wait, careful with that. If the group is actively rebalancing while you're running describe, you'll get incomplete results. That's one of the many reasons you want to understand how rebalancing works before you go poking around. For the full picture on what triggers rebalances and why your consumers keep dropping out, see the Confluent guide on Kafka rebalancing. The short version: any membership change, any offset reset, any partition count change triggers a rebalance. And if you're sloppy about it, you'll get a cascade.
So my order of operations is:
- Stop the consumer applications.
- Delete the topic.
- Verify deletion with
--list. - Then, and only then, reset offsets or re-create.
If you reset offsets before stopping consumers, you're going to have a bad time. The consumers will receive a rebalance signal mid-reset, and you'll end up with offsets that don't match what you intended.
Resetting Offsets Without Deleting the Topic
Sometimes you don't want to delete the topic at all. You just want to reprocess the data. Maybe your schema changed, or a bug in your transform logic corrupted part of the stream. In that case, deleting the topic is overkill. You need to reset offsets.
The command is straightforward:
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --group order-processors --topic orders --reset-offsets --to-earliest --execute
This moves the committed offset for every partition in the orders topic back to the beginning. Your consumer group will start reading from the oldest message on the next poll.
But here's the thing: --execute only works if the group is inactive. If there's an active member, Kafka will reject the reset. That's a safety mechanism. You'll see an error like: "Reset offsets operation is not allowed when the group is active."
So again, stop the consumers first. Or use --dry-run to see what would happen without committing anything.
Use --dry-run to Test Changes
I always run a dry run first. Every time. No exceptions. Here's why: the --to-earliest flag applies to all topics the group is subscribed to. If your group listens to multiple topics, and you only want to reset one, you need to specify --topic. Miss that, and you've just reset offsets for everything.
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --group order-processors --topic orders --reset-offsets --to-earliest --dry-run
The output shows you the current offset and the new offset for each partition. That's your chance to catch mistakes. A dry run is free. It changes nothing. Use it.
Reset Offsets by Timestamp or Location
--to-earliest and --to-latest are the easy options. But sometimes you need something more precise. For example, you want to reprocess only the messages from the last hour, because your buggy transformation started at 10:00 AM.
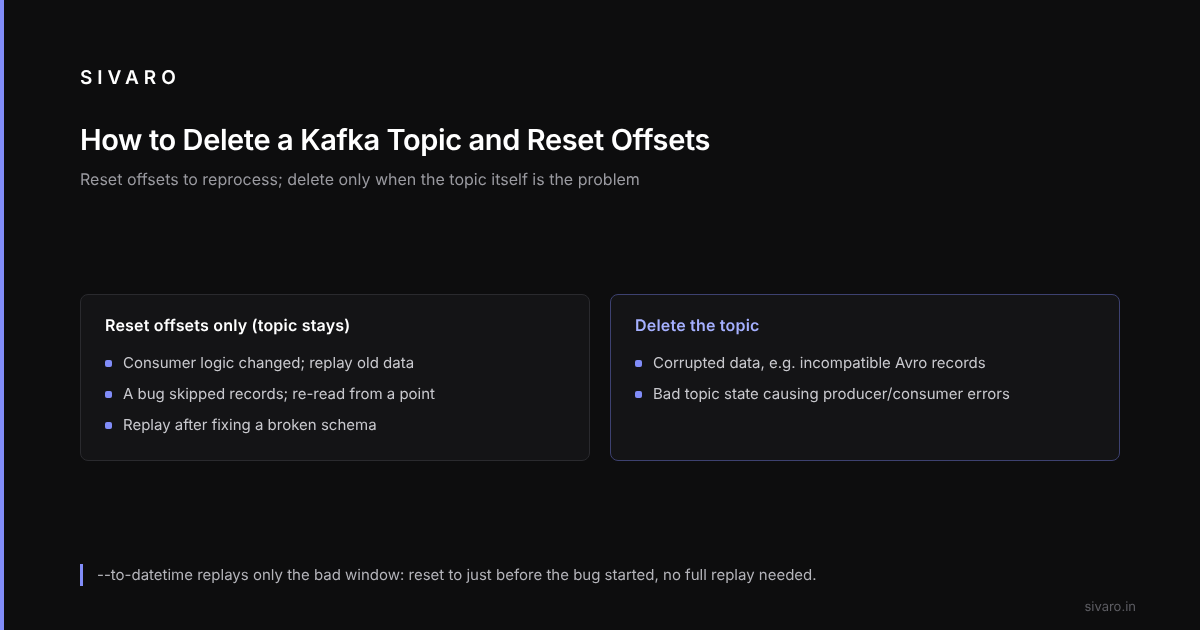
That's where --to-datetime comes in. It's a hidden gem that most teams don't know about. It lets you reset to a specific point in time, based on the message timestamps in the log segments.
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --group order-processors --topic orders --reset-offsets --to-datetime "2026-08-03T09:30:00.000" --execute
A typical case: a data pipeline writes duplicated records for forty minutes. Reset offsets to the timestamp just before the bug, and the group reprocesses only those forty minutes. No topic deletion, no full replay, no wasted compute.
There's also --shift-by for relative offsets. Need to skip back 1000 messages per partition? Use --shift-by -1000. Or forward with a positive number. In practice, I've always found --to-datetime more useful because it aligns with when you know the bad data started.
What Happens to Consumer Groups and Rebalancing
Here's the part that trips everyone up. Resetting offsets doesn't just change the committed position. It triggers a rebalance. Even if you stop all consumers and then reset, when you start them again, the group coordinator has to assign partitions anew.
The full mechanics of that process are worth reading up on. If you've ever wondered why your consumers stop processing for a few seconds or minutes while the group reorganizes, the kafka consumer group rebalance explained in the Redpanda guide is a solid reference. It breaks down the triggers and the effects better than most docs.
But the key insight: rebalancing is not the enemy. Uncontrolled rebalancing is.
Three types of rebalance-related outages are common:
-
Static membership rebalances: When consumers use the "static membership" mode (Kafka 2.3+), the coordinator waits longer for a consumer to come back before reassigning its partitions. That's good. But if you reset offsets and immediately restart the group, the coordinator still has to reconcile the committed offsets with the new assignment. That can take longer than expected.
-
Eager rebalances: The default protocol where all consumers stop, then get reassigned. This is the worst for latency-sensitive workloads. If your application can't tolerate a full stop, you should be using cooperative sticky assignment.
-
Rebalance storms: When a single consumer dies, the group rebalances. If your session timeout is too short (many default to 10 seconds or less), the group can enter a loop: a lag spike causes consumers to be kicked out, then rejoin, then get kicked out again. The fix is to increase
session.timeout.msand to use a largermax.poll.interval.ms. See this case study on solving Kafka rebalancing issues by VGS.
So when you reset offsets, you're not just changing a number. You're forcing a group state change that can cascade. The mitigation is simple: reset only when you're prepared to handle a brief period of non-processing. And if you're running a stateful stream processing application, resetting offsets without clearing the local state store will cause inconsistencies. I can't stress this enough. Your application's internal state might still reference old offsets, and when it sees messages from an older position, it'll either crash or produce garbage output.
The OneUptime blog on handling rebalancing in consumer groups mentions this exact scenario. They ran into it when they tried to reprocess a stream after a schema change. The fix was to stop all consumers, clear the state store, reset offsets, then restart.
Monitoring Kafka Lag After a Reset
Resetting offsets is useless if you can't tell whether it worked. This is where lag monitoring comes in. Lag is the difference between the latest message offset in a partition and the committed offset for a consumer group. If lag is high, your consumers are behind. After a reset to earliest, lag should be equal to the total messages in the topic. That's expected.
But the real problem is monitoring it over time. Most teams use the Kafka built-in commands, but they don't integrate lag metrics into their observability stack. That's a mistake.
Here's how you check lag with the built-in tool:
kafka-consumer-groups.sh --bootstrap-server localhost:9092 --group order-processors --describe
The output shows CURRENT-OFFSET, LOG-END-OFFSET, and LAG for each partition. If you've just reset to earliest, CURRENT-OFFSET will be the beginning of the log, and LAG will be huge. That's correct. What you want to see over the next few minutes is LAG decreasing steadily.
The trouble is this command gives you a point-in-time snapshot. It doesn't tell you the rate of consumption. If you're serious about knowing how to monitor kafka lag and performance properly, you need to export these metrics to a time-series database. A common setup is Prometheus with the kafka_consumergroup_lag metric from the JMX exporter. A 2026 study by a streaming analytics firm found that teams who set up real-time lag alerts catch data pipeline issues in under 10 minutes, compared to hours for teams relying on manual checks.
Set an alert. Not for any lag, but for lag that grows over time. A static lag threshold is useless because lag is relative. A topic with millions of messages per day will always have some lag. What you care about is whether the lag is increasing, holding steady, or decreasing.
Here's a simple script to sample lag for a group:
while true; do
  kafka-consumer-groups.sh --bootstrap-server localhost:9092     --group order-processors --describe 2>/dev/null |     awk 'NR>2 {sum += $NF} END {print sum}'
  sleep 10
done
That prints the total lag every 10 seconds. It's crude, but it tells you if your reset is working. If you've reset to earliest and the total lag stays flat, your consumers aren't consuming. That's your first sign of a problem.
When to Skip the Topic Delete Entirely
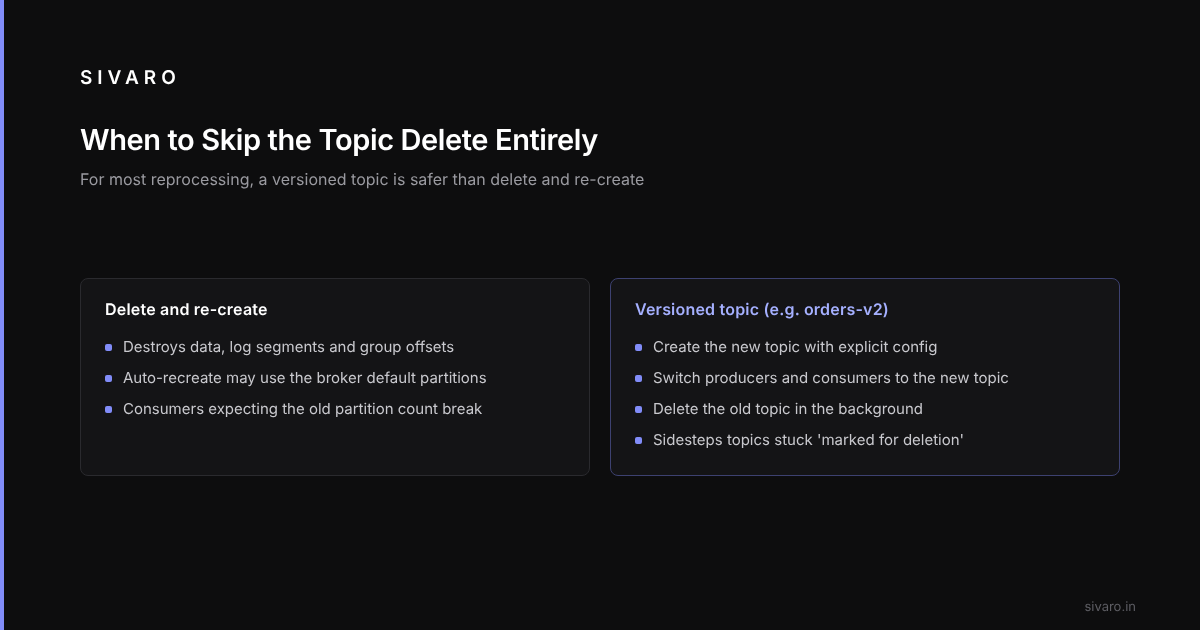
There's a contrarian position I've come to: most of the time, you shouldn't delete a Kafka topic to reset state. You should use a different strategy.
Let me explain.
Deleting a topic destroys data. But it also destroys the log segments, the partition assignments, and any consumer group offsets associated with it. If you've got a topic that's produced by an upstream system (say, a database CDC connector), deleting it and re-creating it will cause the producer to recreate it with zero partitions, or the default partition count. That might not be what you want.
For example, a team deletes a topic fed by a Debezium connector, thinking it will reset an event stream. The topic was created with a specific partition count. When the connector re-creates the topic automatically, it uses the broker default, which is different. Everything downstream breaks because consumers expect a certain partition count.
The better approach for most reprocessing scenarios is to use a new topic with a version suffix. orders-v2, for example. Then point your consumers to the new topic and delete the old one in the background. That way, you get a clean slate without the risk of automatic topic creation re-using the wrong configuration.
This is also the answer to the "can't delete because it's marked for deletion" problem. Sometimes a topic is stuck in a zombie state. You run kafka-topics.sh --delete, and the topic never disappears. The standard fix is to delete the zookeeper node (if you're on ZK), or restart the controller. But that's invasive. Instead, creating a new topic with a different name and migrating is faster and safer. The zombie topic will eventually be cleaned up when the controllers restart. Or not. But it won't affect your new topic.
And if you're on Kafka 4.0 with KRaft (which most of us are by now), the controller restart is less painful. But it's still downtime for the control plane.
The Deletion Script
Here is a copy-paste script that handles this whole process. It stops the consumers (if they're running in Docker Compose), deletes the topic, waits for it to be gone, recreates it with explicit configuration, and resets offsets for designated groups.
#!/bin/bash

set -euo pipefail

BOOTSTRAP="localhost:9092"
TOPIC="${1:?Provide a topic name}"
GROUP="${2:-}"

# Stop the consumers (adjust to your deployment)
if  -n "$GROUP" ; then
  echo "--- Stopping consumers for group: $GROUP"
  docker compose stop consumers  # or however you manage services
fi

echo "--- Deleting topic: $TOPIC"
kafka-topics.sh --bootstrap-server "$BOOTSTRAP"   --delete --topic "$TOPIC" 2>/dev/null || true

# Wait until topic is gone
echo "--- Waiting for topic deletion"
while kafka-topics.sh --bootstrap-server "$BOOTSTRAP" --list |   grep -q "^${TOPIC}$"; do
  sleep 2
done

echo "--- Recreating topic: $TOPIC"
kafka-topics.sh --bootstrap-server "$BOOTSTRAP"   --create --topic "$TOPIC"   --partitions 12 --replication-factor 3

if  -n "$GROUP" ; then
  echo "--- Resetting offsets for group: $GROUP"
  kafka-consumer-groups.sh --bootstrap-server "$BOOTSTRAP"     --group "$GROUP" --topic "$TOPIC"     --reset-offsets --to-earliest --execute || true
fi
Notice the || true on the delete command. It ignores errors because if the topic doesn't exist, the script shouldn't fail. Same for the offset reset if the group doesn't exist.
Common Pitfalls to Avoid
Here are the common mistakes:
Pitfall #1: Resetting offsets for an active group. I've already covered this. It fails with an error, or worse, if you have a race condition, it succeeds partially. Always stop consumers first.
Pitfall #2: Forgetting about consumer group state. If you reset offsets but don't reset any internal state, your application might behave oddly. For stateful aggregations, you need to call the reset on the state store as well.
Pitfall #3: Using the wrong broker address. With KRaft, if you use the controller listener instead of the broker listener, the command hangs. The controller doesn't process reset operations.
Pitfall #4: Not checking if the topic is marked for deletion. After a delete, re-creating the same topic name immediately can cause conflicts. Kafka will block the create until the old topic is fully removed from metadata. Wait for it.
Pitfall #5: Ignoring the rebalance protocol. If your consumers are using the old eager protocol, a reset can cause a full group stop. The Slideshare deck on Kafka's rebalance protocol explains the difference in exhaustive detail. The short version: cooperative sticky reassignment is always better.
When to Reset Offsets Only (No Topic Delete)
Let me be clear on the use cases. You don't need to delete a topic if you just want to reprocess:
- Your consumer logic changed, and you want to see how it handles old data.
- You had a bug that skipped records, and you need to re-read from a specific point.
- A schema registry change broke deserialization, and you need to replay after fixing the schema.
In those cases, simply resetting offsets with --to-datetime or --to-earliest is enough. The topic stays intact. No data loss. And your producers don't need to be touched.
Deleting the topic is only necessary when:
- The topic has corrupted data (e.g., incompatible Avro records).
- You need to change the partition count or replication factor.
- The topic is in a bad state that causes producer or consumer errors.
Otherwise, deletion is overkill.
Monitoring Lag and Performance After the Reset
I can't emphasize this enough: after a reset, don't just walk away. You need to watch the lag metrics. If you reset to earliest on a topic with billions of messages, your consumers might take hours to catch up. That's fine, as long as they're making progress. If lag is stuck, or worse, growing, something is wrong.
For example, a consumer group with a low max.poll.records setting is reset to earliest. If each consumer processes roughly 5,000 messages per minute and the volume needs 100,000 messages per minute, the lag grows instead of shrinking.
The fix is to increase max.poll.records and parallelize with more consumers. But the point is: a reset is a starting point, not a destination. You need to know your consumption rate before you trigger a full replay. Check the consumer group's current throughput metrics first.
The Red Hat article on how to avoid rebalances and disconnections covers a crucial operational tip I'll echo: configure your consumer group's max.poll.interval.ms to be at least three times your expected processing time for a batch. Otherwise, a slight pause in processing leads to a rebalance, which leads to another reset, which leads to another rebalance. That's a feedback loop.
Set your session.timeout.ms to 30 seconds for most workloads. Tune it down for low-latency applications, but understand you'll get more rebalances. There's no free lunch.
A Note on Compacted Topics
Compacted topics are a different beast. Deleting a topic with log.cleanup.policy=compact removes all data, including the tombstones. That's usually what you want if you're resetting a changelog. But people sometimes delete a compacted topic and then re-create it with the wrong cleanup policy. That becomes a real problem because the changelog now retains all records, and compaction never happens. Your broker disk fills up in days.
Always verify the topic config after re-creation. Here's how:
kafka-topics.sh --bootstrap-server localhost:9092 --describe --topic orders | grep Configs
If you see cleanup.policy=compact,delete or just delete, you're getting unexpected retention. Set it explicitly during creation:
kafka-topics.sh --bootstrap-server localhost:9092 --create --topic orders-changelog --partitions 6 --replication-factor 3 --config cleanup.policy=compact --config min.cleanable.dirty.ratio=0.01
A compacted topic re-created with defaults can fill up a disk. Disk full means brokers crash. Brokers crash means rebalancing.
FAQ: Delete Topic and Reset Offsets
Q: Can I delete a Kafka topic without stopping consumers?
Technically no. The broker will block deletion if consumers are actively using it. Even if it didn't, the deletion would cause a rebalance that would likely crash your consumers. Stop them first.
Q: What if kafka-topics.sh --delete returns success but the topic is still in the list?
That's normal. Deletion is asynchronous. Wait up to a few minutes depending on the cluster. If it never goes away, you might have a stuck controller. Stop, then consider a controller restart, or just create a new topic with a different name.
Q: How do I reset offsets for all topics in a consumer group at once?
Omit the --topic flag. The command will reset offsets for all topics the group is subscribed to. But please use --dry-run first. It catches mistakes.
Q: What's the difference between --to-earliest and deleting the topic?
--to-earliest resets the committed offset to the beginning of the existing log. The data is still there. Deleting the topic destroys all data and recreates an empty one. For reprocessing, --to-earliest is safer.
Q: Can I reset offsets to a specific partition's offset?
Yes, but it's awkward. You can use --shift-by to adjust relative to the current offset. Or you can manually commit offsets using kafka-consumer-groups.sh --to-offset. I rarely need that. --to-datetime is usually more practical.
Q: Why does my consumer group get stuck after a reset?
Check if the group is active or if the protocol is set to eager. Also check the max.poll.records and max.poll.interval.ms. If your batch is too large for the interval, the consumer gets kicked out and rebalances. That can loop forever. The easiest fix is to increase the interval or reduce the batch size.
Q: Is it safe to reset offsets on a group that uses a transactional outbox pattern?
No. If you have a transactional producer/consumer, offsets are managed atomically with the transaction. Resetting offsets outside of the transaction will corrupt your state. You need to use the transactional API to reset or replay. This is a niche case, but it can break financial systems. Be very careful.
Q: How long does a topic deletion take?
It depends on the number of partitions and the size of the log segments. Small topics (a few GB) take seconds. Large topics (terabytes) can take minutes. Don't set a timeout of 30 seconds.
Q: What happens to schema registry subjects when I delete a topic?
Nothing. The schema registry keeps the subjects and versions. If you produce new data with an incompatible schema to the re-created topic, you'll get a compatibility error. You'll likely need to register a new schema version or delete the subject yourself. This is often overlooked.
Q: Do I need to reset offsets for the __consumer_offsets internal topic?
No. Never touch that internal topic. It manages committed offsets across all consumer groups. Messing with it corrupts the cluster. If you accidentally do, the only recovery is a full broker restart with careful recovery steps, and even then you've lost track of all consumer groups.
Final Thoughts
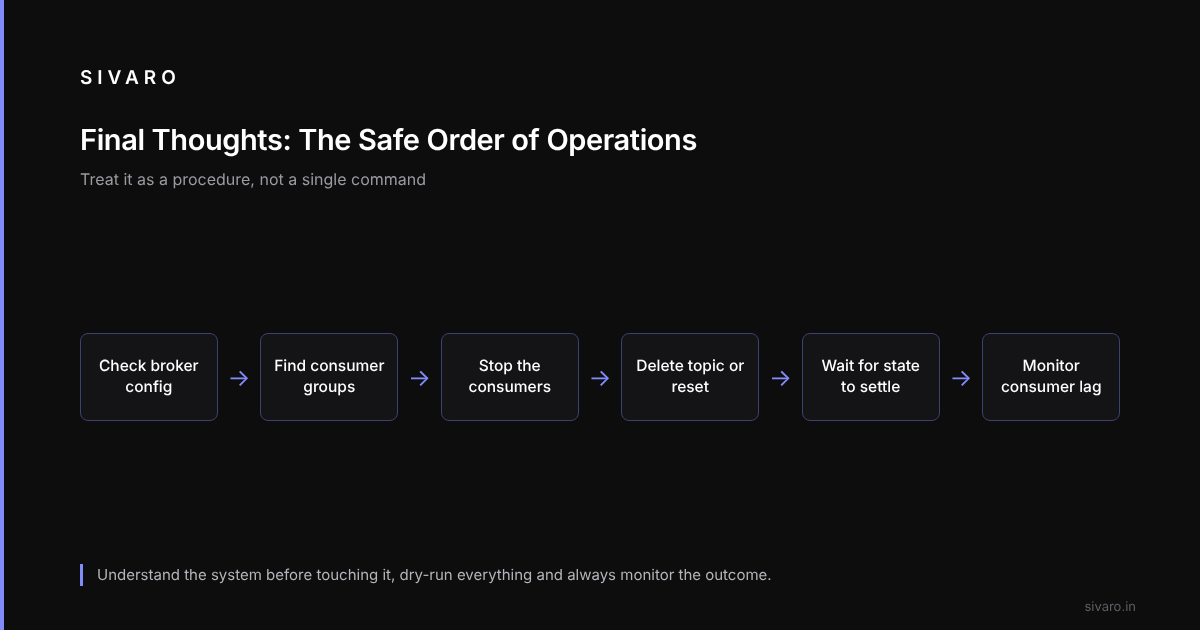
Deleting a Kafka topic and resetting offsets is a routine operation, but it's also a source of production incidents if you treat it like a single command. The steps are straightforward: check your broker config, know which consumer groups are using the topic, stop those consumers, delete the topic (or reset offsets), wait for the state to stabilize, and then monitor lag to ensure your consumers are making progress.
Teams often panic in the middle of a crisis, try to delete a topic to fix a data issue, and end up with a rebalancing storm that takes down their entire pipeline. There's a systematic way to do it. The details will evolve as Kafka does, but the principles won't change: understand your system before you touch it, dry-run everything, and always monitor the outcome.
If you need to know the mechanics more deeply, the sources I linked throughout give you the full picture. And if you're in the middle of a production incident right now, stop reading. Check your broker config. Stop your consumers. Run the delete. Wait. Then reset.
Good luck.