Add four A100s to a PyTorch training run and you might expect a fourfold speedup. Often you get far less. Parallel computing isn't about buying more hardware. It's about partitioning the problem, not just the GPUs.
That's what this guide covers: AWS parallel computing explained, with the failure modes that show up in production. By the end, you'll know when to use SageMaker Distributed, when to roll your own EKS cluster, whether AWS Spot Instances for AI training are worth the risk, and how AWS stacks up against owning a dedicated GPU cluster. You'll also see the code patterns that actually work, and the network bottlenecks that will make you want to throw your laptop.
The First Mistake: Scaling GPU Count Instead of Data Flow
A familiar pattern: the data grows faster than training times, so the team decides to "just rent more GPUs on EC2." Two V100s become four. Four become eight. And training time barely improves.
The problem isn't GPU count. It's synchronizing gradients over a slow network (for example 1 Gbps) every single step. The GPUs spend more time waiting for each other than computing. That's the dirty secret of parallel computing: it's not a hardware problem, it's a data movement problem.
AWS gives you the raw pieces—EC2 instances, EBS, S3, Elastic Fabric Adapter. But raw pieces don't make a distributed system. You need a strategy. Distributed training in Amazon SageMaker AI has a clear breakdown of the strategies: data parallel, model parallel, and pipeline parallel.
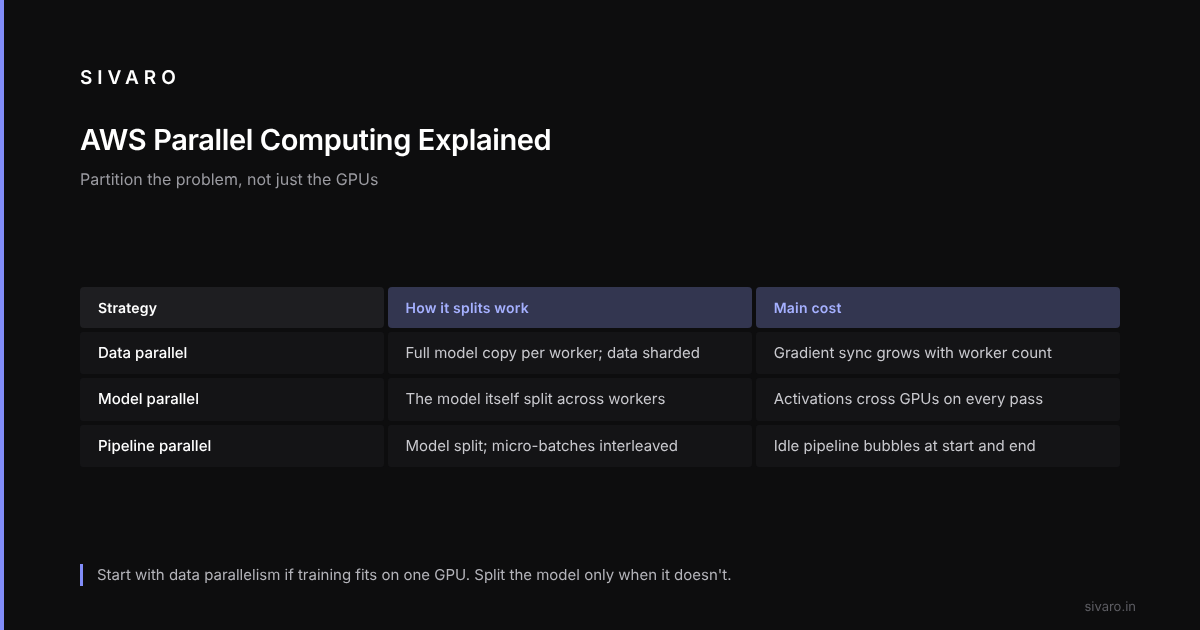
The most important rule: start with data parallelism if your model fits on one GPU. Only move to model parallelism when the model literally doesn't fit. That sounds obvious, but you'd be surprised how many teams split a 7B model across four GPUs when a single A100 has 80GB of HBM.
The Real Meaning of AWS Parallel Computing Explained
AWS parallel computing explained in plain terms: you split a workload across multiple processing units and coordinate them to produce a result faster than any single unit could. That's it. The complexity lives in the coordination.
There are three core forms on AWS:
- Data parallelism: Every worker runs the same model, but sees different chunks of data. They sync gradients at the end of each batch.
- Model parallelism: The model itself is split across workers. Each worker computes a piece of the forward pass.
- Pipeline parallelism: A special case of model parallelism where you interleave micro-batches so all workers stay busy.
And then there's the orchestration layer—SageMaker, EKS, Batch, ParallelCluster. The trick is choosing the right tool for the job.
For most teams, SageMaker Distributed is the right default. It abstracts away the grunt work of spinning up instances, setting up distributed communication, and checkpointing. What Is Distributed Machine Learning? from IBM makes the point that distributed ML is as much about fault tolerance as speed. SageMaker handles node failures and restarts. Do you want to build that yourself? Probably not.
Data Parallel, Model Parallel, and Pipeline Parallel: Picking Your Poison
Here's the blunt version. If your model fits on one GPU, use data parallel. If it doesn't, you're in for a world of pain regardless.
Data parallelism is simple to reason about. You have N workers. Each worker holds a copy of the model. You shard your dataset into N chunks. At the end of each step, you all-reduce the gradients. With a fast interconnect like Elastic Fabric Adapter or NVIDIA NVLink, this scales decently. But the synchronization cost grows with the number of workers. At some point, adding a worker doesn't help.
For many models, that point is around 32 nodes—unless you're using gradient accumulation to hide the communication latency.
Model parallelism is a different beast. You're splitting the model layers across GPUs. Every forward and backward pass requires sending activations between GPUs. Distributed Training & Large-Scale Systems has a good analogy: model parallelism is like an assembly line. The output of one worker is the input of the next. If one worker is slow, the whole line waits.
Pipeline parallelism improves throughput by allowing multiple micro-batches to flow through the assembly line at once. But it introduces pipeline bubbles—idle time at the start and end of each cycle. The larger the pipeline, the more bubbles.
For a 13B dense model on an 8-node cluster, pipeline parallelism may finish only somewhat faster than data parallelism, with much more setup work. The marginal gain often isn't worth the complexity for that model size. For a 70B model? Pipeline wins. But you need the ops maturity to debug it.
AWS Parallel Computing Explained: Spot Instances for AI Training
Let's talk about the cheap stuff. AWS Spot Instances can slash your training costs by 60-80%. For AI workloads, that's the difference between running a fine-tune and not running it.
But the story isn't that simple. Spot instances are reclaimable. AWS can take them back with a two-minute warning. Your training job has to handle that interruption gracefully.
Most people think spot instances are useless for training. They're wrong. Spot works for anything that supports fault tolerance. Here's the pattern that works:
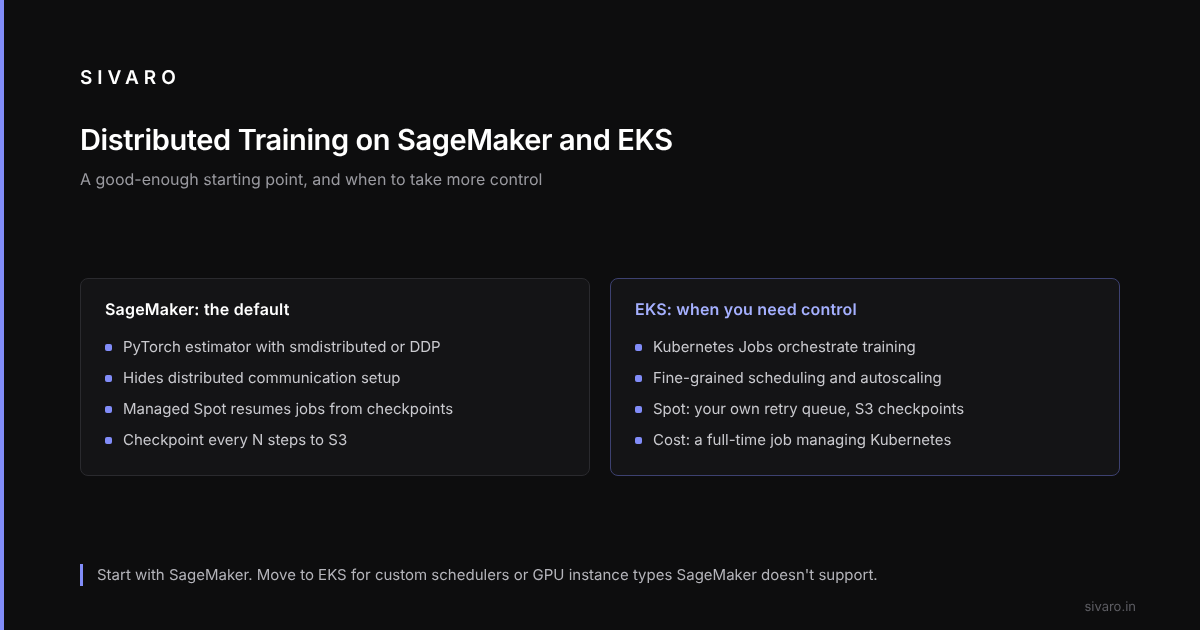
- Use SageMaker with Managed Spot Training. SageMaker automatically handles spot interruptions by resuming from checkpoints.
- For custom EKS training, use a job queue with retry logic and S3-backed checkpoints.
- Only use spot for data parallel jobs, not model parallel. If you lose one worker in a model parallel job, the entire job collapses.
A worked example with illustrative prices: 4 on-demand A100s at $6.60 per hour each for 9 hours is $237.60. At a spot price of $1.90 per hour, the same job costs about $70, even with a couple of interruptions, if checkpoints every 15 minutes let it recover cleanly.
And here's boto3 code to request spot instances for custom training with AWS ParallelCluster:
import boto3

ec2 = boto3.client('ec2', region_name='us-east-2')
response = ec2.request_spot_fleet(
    SpotFleetRequestConfig={
        'IamFleetRole': 'arn:aws:iam::123456789012:role/aws-ec2-spot-fleet-tagging-role',
        'TargetCapacity': 4,
        'AllocationStrategy': 'capacityOptimized',
        'LaunchSpecifications': [
            {
                'ImageId': 'ami-0abcdef1234567890',
                'InstanceType': 'p4d.24xlarge',
                'SecurityGroups': [{'GroupId': 'sg-0123456789'}],
                'SubnetId': 'subnet-0123456789',
                'BlockDeviceMappings': [
                    {
                        'DeviceName': '/dev/sda1',
                        'Ebs': {'VolumeSize': 500, 'VolumeType': 'gp3'}
                    }
                ]
            }
        ]
    }
)
print(response['SpotFleetRequestId'])
It works—if you design for interruption from day one.
AWS vs GPU Cluster for AI Workloads: What You're Really Paying For
There's a running joke: the cheapest way to get 100 H100s is to buy a house and put them in the garage. That's not true anymore. And honestly, for most workloads, it never was.
Let's compare. In mid-2026, renting an H100 on AWS costs roughly $4-5 per hour on-demand, maybe $1.50-2 on spot. A dedicated 8-GPU node from a vendor like CoreWeave or Lambda Labs can be cheaper per hour—sometimes $2.50-3 for H100. But that's just the GPU.
The hidden costs of a dedicated GPU cluster are the network, storage, and engineering time. Training a 30B parameter model requires high-bandwidth interconnect between GPUs. On AWS, that's the Elastic Fabric Adapter (EFA). On your own cluster, it's InfiniBand. InfiniBand is fast, but it's also expensive to maintain. And you don't get to scale up overnight when you suddenly need 200 GPUs.
AWS wins on elasticity. You can go from 0 to 100 GPUs in five minutes. Try that with your own hardware.
But there's a catch. AWS wins only if you're using managed services properly. If you're wasting time babysitting EC2 instances, doing manual failover, and rebuilding broken schedulers, a dedicated cluster might actually be simpler. The tradeoff isn't just dollars. It's your team's attention.
A rule of thumb: if you need a stable training cluster for more than 6 months and you have a full-time infrastructure engineer, buy or rent dedicated capacity. If your workload is bursty—like fine-tuning jobs that run a few times a week—use AWS. The flexibility is worth the premium.
Owning hardware has a setup cost that is easy to underestimate. Setting up the environment and fixing kernel drivers can take weeks, and by the time the cluster is stable, the model may already have changed.
Building a Distributed Training Stack on SageMaker and EKS
Let's get practical. You have a model to train. You think you need distributed training. Here's the "good enough" starting point:
- Use SageMaker with a PyTorch estimator.
- Set
distributionforsmdistributedor just extend PyTorch DDP. - Use a checkpointing strategy that saves every N steps to S3.
- Use Automatic Model Tuning if you're searching hyperparameters.
Here's a minimal SageMaker training script:
import sagemaker
from sagemaker.pytorch import PyTorch

estimator = PyTorch(
    entry_point='train.py',
    role='arn:aws:iam::123456789012:role/service-role/AmazonSageMaker-ExecutionRole-20240101T000001',
    instance_count=4,
    instance_type='ml.p4d.24xlarge',
    distribution={'smdistributed': {'dataparallel': {'enabled': True}}},
    checkpoint_s3_uri='s3://my-bucket/checkpoints',
    output_path='s3://my-bucket/output',
    hyperparameters={
        'epochs': 30,
        'batch_size': 64,
        'learning_rate': 0.001
    }
)

estimator.fit({'train': 's3://my-bucket/train', 'test': 's3://my-bucket/test'})
Inside train.py, you still need to handle the distributed world. SageMaker sets the environment variables for you, but the PyTorch side is yours. Here's the classic DDP boilerplate:
import os
import torch
import torch.distributed as dist
from torch.nn.parallel import DistributedDataParallel as DDP

def init_process_group():
    dist.init_process_group(
        backend='nccl',
        init_method='env://',
        world_size=int(os.environ.get('WORLD_SIZE', 1)),
        rank=int(os.environ.get('RANK', 0))
    )
    torch.cuda.set_device(int(os.environ['LOCAL_RANK']))
Yes, it's boilerplate. Use it. It's the foundation of distributed training.
But if you need more control, EKS is the way to go. With the AWS Distro for OpenTelemetry and Kubernetes Jobs, you can orchestrate training workloads. Here's a simple Kubernetes job:
apiVersion: batch/v1
kind: Job
metadata:
  name: distributed-training
spec:
  completions: 4
  parallelism: 4
  template:
    spec:
      containers:
      - name: trainer
        image: 123456789012.dkr.ecr.us-east-2.amazonaws.com/trainer:latest
        args: ["--epochs", "30", "--dataset", "s3://my-bucket/train"]
        resources:
          limits:
            nvidia.com/gpu: 1
        env:
        - name: MASTER_ADDR
          value: "distributed-training-0"
        - name: MASTER_PORT
          value: "12345"
      restartPolicy: Never
EKS gives you fine-grained control over scheduling and autoscaling. But it also gives you a full-time job of managing Kubernetes. If you're not already comfortable with K8s, SageMaker will save you a lot of late nights.
Example: Parallelizing a Daily Retraining Job
Consider a fine-tuned 7B parameter transformer for content moderation that must be retrained every day on fresh data. On a single g5.48xlarge instance, training can take hours.
Parallelizing across 4 instances using SageMaker with data parallel cuts the wall-clock time, at a higher total cost. Whether that is worth the spend depends on how much a fresher model is worth to the system.
The key is a fast checkpointing frequency. SageMaker's default checkpoint interval is too long for spot instances. With spot, set checkpoint_frequency=60 (seconds) and add a use_spot_instances=True flag. Without frequent checkpoints, a spot reclaim can wipe out everything since the last checkpoint.
Here's the exactly right way to enable spot with manual checkpointing in SageMaker:
from sagemaker.pytorch import PyTorch

estimator = PyTorch(
    entry_point='train.py',
    role='arn:aws:iam::123456789012:role/service-role/AmazonSageMaker-ExecutionRole-20240101T000001',
    instance_count=4,
    instance_type='ml.p4d.24xlarge',
    use_spot_instances=True,
    max_wait=4 * 60 * 60,
    max_run=3 * 60 * 60,
    checkpoint_s3_uri='s3://my-bucket/checkpoints',
    checkpoint_frequency=60
)
That small configuration change can cut the training bill substantially.
Networking Is the Silent Killer in Parallel Computing
Here's something the docs don't emphasize enough: your network protocol and topology matter more than your GPU model. If you're training with multiple nodes, the network is the bottleneck. Plain Ethernet will murder your distributed training performance.
AWS's answer is the Elastic Fabric Adapter (EFA). EFA supports OS-bypass communication, which means data moves between GPUs without the CPU getting in the way. It's essentially AWS's version of InfiniBand. Use it. Don't use regular ENI for distributed training.
Without EFA, all-reduce time per step on a multi-node A100 setup can be several times higher than with it. Across 10,000 steps, that adds up.
If you're using SageMaker, EFA is automatically enabled for ml.p4d and ml.p4de instances. But if you're building your own EC2-based cluster, you have to manually attach EFA to your instances. And you need to pick a placement group that allows low-latency communication between nodes. This is one of those areas where the managed service pays for itself.
Agentic Systems Are Also Distributed Systems
We've been talking about training. But there's a second kind of parallel computing that's become impossible to ignore: serving AI agents. As of 2026, enterprise AI agents don't call one model. They call dozens. They manage context windows, call external tools, and coordinate with other agents. That's a distributed system.
Agentic Systems Are Distributed Systems makes exactly this point. An agent that needs to reason, call APIs, and await events is doing distributed computing. AWS parallel computing isn't just for GPUs. It's also for the orchestration layer.
For agent backends on Amazon EKS and Step Functions, the key insight is the same: you need to treat agent state as a distributed state machine, not a Python function call. If one agent node fails, another must pick up the state. That means thinking in terms of event sourcing, idempotency, and retry queues.
A simple two-agent workflow can keep failing because the second agent waits forever for a callback. One fix is a distributed lock with Amazon DynamoDB and a timeout circuit breaker. It's parallel computing at the application level. CI/CD for agents is still immature. But the principles of distributed systems—decoupling, retry, idempotency—apply perfectly.
The Cloud-Native Angle: Efficiency as a First-Class Citizen
The paper Cloud-native and Distributed Systems for Efficient and ... makes a useful argument: on cloud infrastructure, efficiency is a distributed systems problem, not a hardware problem.
You can't just throw more GPUs at a job. The cloud-native approach is to design your training pipeline to be aware of instance types, spot availability, and network topology. For example, use eks-node-viewer to understand utilization. Use Karpenter to scale based on real-time demand. Use S3 Express to reduce checkpoint latency.
The teams that win are the ones that treat AWS as an evolving system, not a static pool of resources. Distributed Training & Large-Scale Systems covers this too: the best distributed ML systems are designed with elasticity in mind. They can scale down just as easily as up.
Keeping A100s running overnight just to avoid cold starts is wasted money. SageMaker Serverless for the idle periods and Karpenter for the training spikes cost less. It's boring, but it works.
Frequently Asked Questions
Do I need distributed training if I have a single large GPU?
Only if you're hitting memory limits or you need faster throughput. Start with one GPU, optimize your data loading pipeline, and then go distributed. Most teams skip the first step and pay for it later.
What is the difference between data parallel and model parallel?
Data parallel replicates the model and splits the data. Model parallel splits the model itself. Data parallel is easier to implement and scales better for large datasets. Model parallel is necessary when a model doesn't fit into memory.
Are AWS Spot Instances safe for AI training?
Yes, if you build with checkpoints and fault tolerance. Use SageMaker Managed Spot for automatic recovery, or implement your own resubmission logic on EKS. They're not safe for model-parallel workloads unless you can afford the restart cost.
How does AWS compare to owning a GPU cluster?
AWS is more expensive per GPU-hour but offers elasticity, managed services, and no hardware maintenance. A dedicated cluster is cheaper at full utilization but requires your team to handle infrastructure. For most companies, the total cost of ownership favors AWS when utilization is below 60%.
What is EFA and do I need it?
EFA is AWS's Elastic Fabric Adapter. It enables low-latency, high-throughput networking between instances. If you're doing multi-node training, you need it. Without it, your training will be bottlenecked by the network.
Should I use SageMaker or EKS for distributed training?
Start with SageMaker. It hides the complexity of setting up distributed communication and handles spot interruptions automatically. Move to EKS only when you need custom schedulers, private networking, or access to specific GPU instance types that SageMaker doesn't support.
What's the best way to checkpoint large models on AWS?
Use S3 for durable checkpoints and EFS or FSx for fast local snapshots. Save checkpoints every 5-10 minutes for training jobs longer than an hour. Use asynchronous checkpointing so your training loop isn't blocked by writes.
How many GPUs should I use for a 70B parameter model?
For training from scratch, you need a few hundred. For fine-tuning, 8-16 GPUs are usually enough with model parallelism and gradient checkpointing. The exact number depends on your sequence length, batch size, and optimizer overhead.
So What's the Bottom Line?
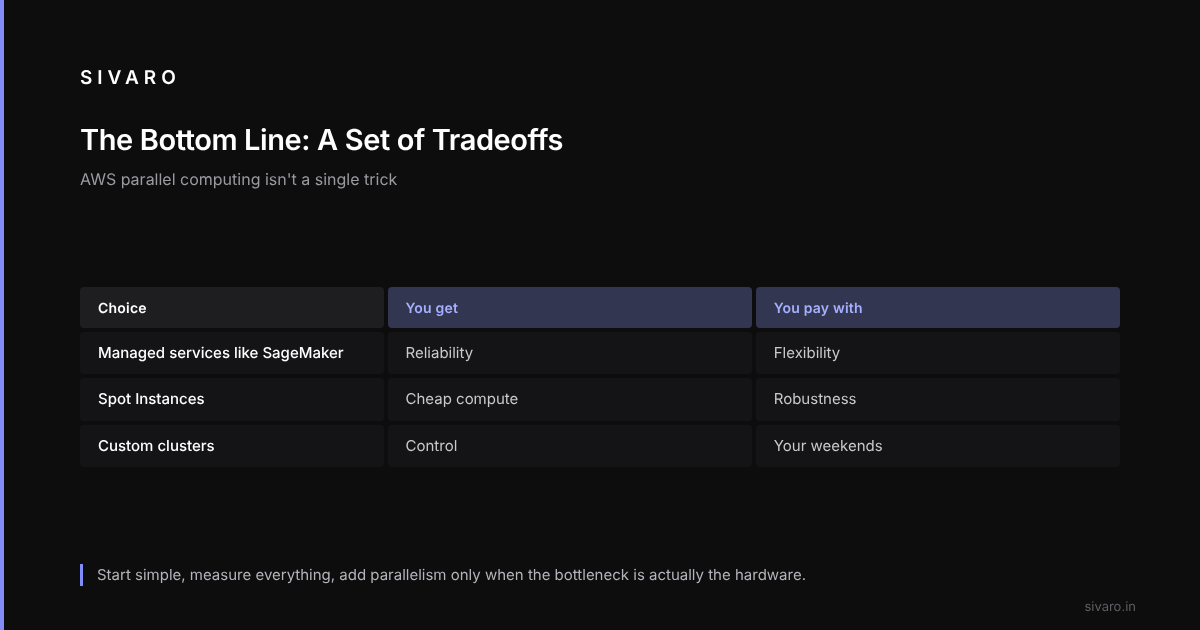
AWS parallel computing explained isn't a single trick. It's a set of tradeoffs. Managed services like SageMaker give you reliability at the cost of flexibility. Spot instances give you cheap compute at the cost of robustness. Custom clusters give you control at the cost of your weekends.
The mistakes in this article are easy to make: training jobs that fail at hour 6 because nothing was checkpointed, dedicated GPUs that sit idle, clusters over-provisioned for jobs that two instances could do.
The pattern that works is this: start simple, measure everything, add parallelism only when the bottleneck is actually the hardware. Use AWS Spot Instances for AI training whenever your workload can tolerate retries. And remember that distributed computing is a discipline, not a product.
You can build a lot with the AWS building blocks. Just be honest about the complexity you're willing to own.