This isn't a philosophy piece. You're reading it because you're building something with agents — LLM agents, robotic process agents, simulation agents — and you need an infrastructure layer that doesn't collapse under the weight of coordination, state, and concurrency. You need to decide between AWS and Kubernetes. Or maybe you think you can have both. Let me show you what happens when you actually try.
What makes multi-agent systems different from a typical microservice
Most people think agent orchestration is just fancy RPC. They're wrong. Multi-agent systems are distributed systems with all the classic problems plus a few new ones: non-deterministic execution, ephemeral state, long-running conversations, and the need for dynamic scaling. Agentic Systems Are Distributed Systems — Akka's 2024 blog captured it perfectly. Agents aren't stateless microservices. They hold context, they negotiate, they back off and retry. They act like tiny distributed databases with language models strapped to them.
The infrastructure question isn't just "where do I run my containers?" It's "how do I handle message delivery guarantees, state persistence, scaling from 5 agents to 5,000, and cost control when each agent invocation burns GPU time?"
That's where the AWS vs Kubernetes debate gets real.
The core difference: managed vs. self-managed control
Kubernetes gives you total control. AWS gives you a lot less control — and way less headache.
With Kubernetes, you own the control plane, the node groups, the CNI plugin, the storage class, the observability stack, the secrets management. You can pin agents to specific GPU types, use custom scheduling policies, and tune every layer of the stack. That's powerful. It's also a part-time job for a team of three.
With AWS, you pick a service (EKS, SageMaker, Step Functions, ECS, Bedrock Agents) and accept whatever abstraction it provides. You lose flexibility. You gain operational zero.
Distributed training in Amazon SageMaker AI documents the kind of infrastructure that makes the managed approach possible — it's not just training, it's inference orchestration with built-in scaling.
aws parallel computing architecture explained
Let's get technical for a minute. AWS's parallel computing architecture for multi-agent systems relies on three layers: a compute layer (ECS, EKS, or SageMaker), a messaging layer (SQS, EventBridge, SNS), and a state layer (DynamoDB, ElastiCache, or Step Functions with task tokens). This is fundamentally different from Kubernetes, where you roll your own messaging with Kafka or NATS, your own state with etcd or a database, and your own compute scheduling with the Kubernetes scheduler.
The AWS architecture is opinionated. It assumes you want eventual consistency, horizontal scaling, and pay-per-use. Kubernetes is agnostic. It assumes you want to control everything.
For multi-agent systems, the AWS opinionated model maps shockingly well. Agents need to communicate asynchronously. They need to store intermediate state. They need to scale independently. AWS's managed message queues and state stores handle this with zero operational work. In Kubernetes, you're debugging why your agent pod can't connect to your NATS cluster at 2 AM.
What Kubernetes actually wins at
I don't want to sound like an AWS fanboy. Kubernetes has real advantages for multi-agent systems, especially when you need to run agents that are tightly coupled to each other or when you need custom networking.
On-premise or hybrid scenarios. If you're a financial institution with data that can't leave your data center, Kubernetes is your only real option. AWS Outposts exists but it's expensive and limited.
Custom GPU scheduling. Kubernetes allows you to use node affinities, taints, and tolerations to place agents on specific GPU instances. AWS managed services are coarser — you pick an instance type and the service handles placement. If you need to guarantee that two agents share the same GPU (for shared memory or fast communication), Kubernetes gives you that level of control. AWS usually doesn't.
Open-source flexibility. You can run any agent runtime on Kubernetes. LangChain, AutoGen, CrewAI, custom frameworks — they all run as containers. AWS services like Bedrock Agents are vendor-locked. You can't easily swap the model runtime.
But here's the thing: most multi-agent systems don't need that control. They need reliability and speed of iteration. And on those dimensions, AWS consistently beats Kubernetes for the average team.
aws gpu cluster pricing for ai workloads
Let's talk money, because that's where the tech decision becomes a business decision.
In 2026, a single NVIDIA H200 GPU on AWS (p4d.24xlarge) costs around $32 per hour on-demand. Reserved instances drop that to ~$20 per hour. A Kubernetes cluster on the same hardware, self-managed, costs exactly the same for the compute — but you add the cost of the control plane nodes (three m6i.large instances, $0.20/hr each), the load balancers ($20/month each), the block storage, the monitoring infrastructure (Grafana, Prometheus, Loki — all running on their own instances), and the engineering time spent managing it.
Managed services, on the other hand, carry higher per-invoke costs because of API overhead, so the compute bill alone can be higher. The engineering time saved on operating the platform is what usually decides the comparison.
Distributed Training & Large-Scale Systems calls out this exact trade-off: managed services are often more expensive at high scale but cheaper at moderate scale due to reduced operational burden. For most multi-agent systems today, moderate scale (< 1M agent calls/day) is the norm. AWS wins on economics.
The practical architecture: an example
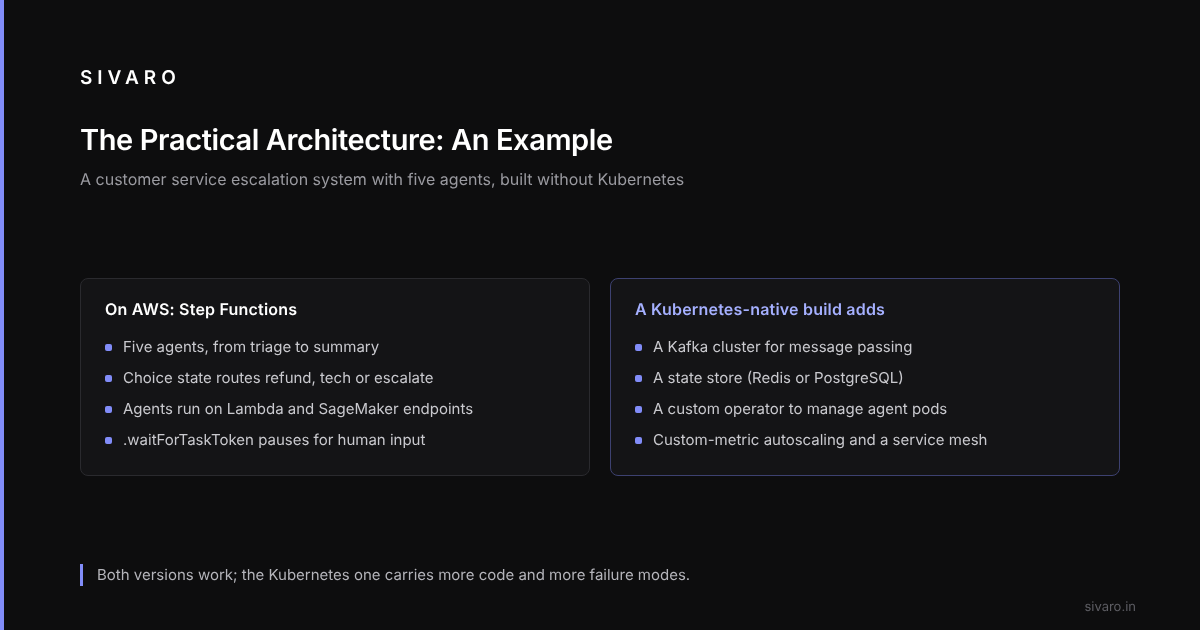
Here's an example: a customer service escalation system. Five agents: triage agent, refund agent, technical support agent, manager escalation agent, and a summarizing agent.
It runs on AWS using Step Functions, Lambda, and SageMaker endpoints. No Kubernetes.
# AWS Step Functions definition (pseudo-code)
{
  "Comment": "Multi-agent escalation workflow",
  "StartAt": "TriageAgent",
  "States": {
    "TriageAgent": {
      "Type": "Task",
      "Resource": "arn:aws:lambda:us-east-1:xxx:function:triage",
      "ResultPath": "$.classification",
      "Next": "RouteToAgent"
    },
    "RouteToAgent": {
      "Type": "Choice",
      "Choices": [
        {"Variable": "$.classification.type", "StringEquals": "refund", "Next": "RefundAgent"},
        {"Variable": "$.classification.type", "StringEquals": "tech", "Next": "TechSupportAgent"},
        {"Variable": "$.classification.type", "StringEquals": "escalate", "Next": "ManagerEscalation"}
      ],
      "Default": "SummarizeAgent"
    },
    "RefundAgent": {
      "Type": "Task",
      "Resource": "arn:aws:sagemaker:us-east-1:xxx:endpoint/refund-agent",
      "ResultPath": "$.refund_response",
      "Next": "SummarizeAgent"
    },
    "SummarizeAgent": {
      "Type": "Task",
      "Resource": "arn:aws:lambda:us-east-1:xxx:function:summarize",
      "End": true
    }
  }
}
Each agent's SageMaker endpoint can run a fine-tuned model on a single G5 instance. The Step Functions workflow tracks the conversation state in DynamoDB (using the ResultPath and a callback). When an agent needs to pause and ask a human, Step Functions' .waitForTaskToken creates a long-lived hold.
The same system in Kubernetes would require:
- A Kafka cluster for message passing
- A statestore (Redis or PostgreSQL)
- A custom operator to manage agent pods
- Horizontal pod autoscaling based on custom metrics
- A service mesh for inter-agent communication
All of that works. It's just 10x more code and 10x more failure modes.
When Kubernetes actually makes sense
I'm not anti-Kubernetes. I'm anti-Kubernetes-when-you-don't-need-it.
If you're building a multi-agent system that requires:
- Sub-millisecond latency between agents (co-located on the same node)
- Custom networking (e.g., agents that share a GPU through CUDA inter-process communication)
- Multi-cloud or hybrid cloud deployment
- Very high throughput ( > 10K agent invocations per second)
Then Kubernetes is the right choice. You need the control. I'd recommend running it on EKS (managed Kubernetes) to get the best of both worlds — Kubernetes control plane managed by AWS, but your own custom scheduling and networking.
Here's an example Kubernetes deployment for an agent with GPU requirements:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: credit-risk-agent
spec:
  replicas: 3
  selector:
    matchLabels:
      app: credit-risk-agent
  template:
    metadata:
      labels:
        app: credit-risk-agent
    spec:
      nodeSelector:
        node.kubernetes.io/instance-type: g5.xlarge
      containers:
      - name: agent
        image: myrepo/credit-risk-agent:2026-07-15
        resources:
          limits:
            nvidia.com/gpu: 1
            memory: "16Gi"
        env:
        - name: AGENT_ID
          value: "credit-risk"
        - name: MESSAGE_BROKER
          value: "nats://nats-cluster:4222"
Notice the nodeSelector and GPU resource limits. In Kubernetes, you can pin agents to specific node pools. In SageMaker, you'd create separate endpoints for each agent type, and the pricing per inference call might be higher for bursty workloads.
Monitoring and observability
Multi-agent systems are notoriously hard to debug. An agent can produce a bad output, another agent picks it up, and the error propagates through the system. You need tracing, not just logging.
AWS has X-Ray, CloudWatch Logs, and SageMaker's model monitor. Kubernetes has Jaeger, Zipkin, Prometheus, and the OpenTelemetry collector. Both ecosystems work.
The difference is setup time. AWS's built-in tracing for Step Functions is instant. Every state transition is logged, timed, and visualized. In Kubernetes, you need to install the OpenTelemetry operator, configure exporters, deploy Jaeger or Tempo, and instrument every agent.
For a team that's already struggling with multi-agent logic, adding a Kubernetes observability stack is a distraction.
AWS vs kubernetes for multi agent systems: the decision framework
A simple framework for this decision:
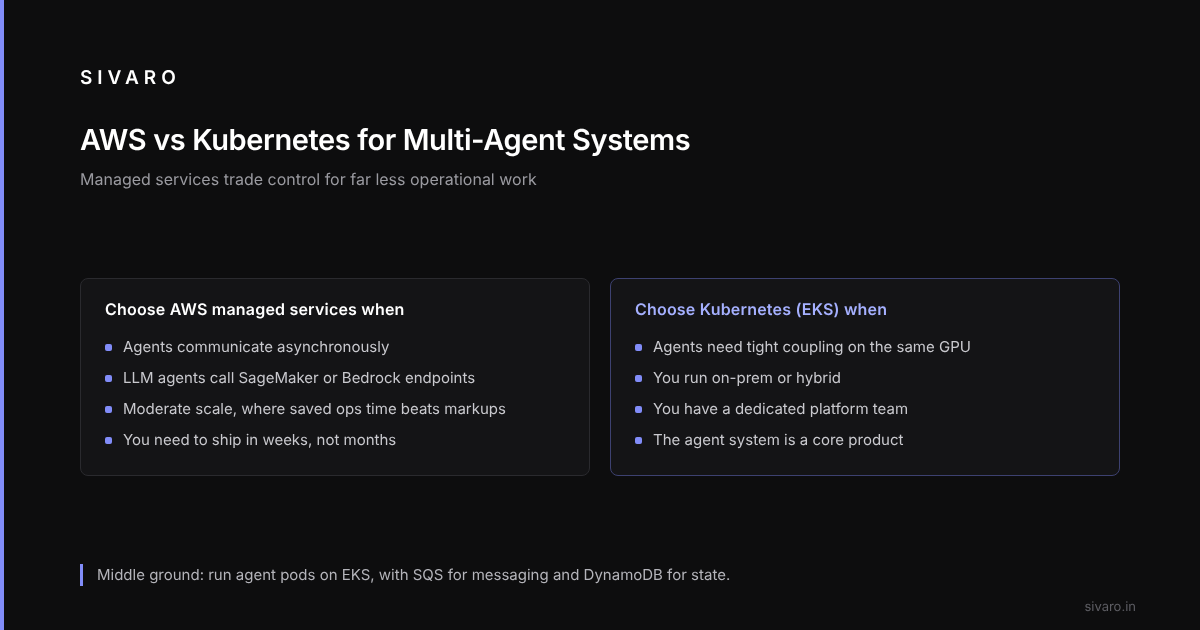
Choose AWS managed services when:
- Your agents communicate asynchronously (most do)
- You have < 5M agent invocations per day
- Your team size is < 10 engineers
- You need to ship in weeks, not months
- You're using LLM agents that call SageMaker or Bedrock endpoints
Choose Kubernetes (ideally EKS) when:
- You need tight agent-to-agent coupling on the same GPU
- You're running on-prem or hybrid
- You have a dedicated platform team
- Your agent system is a core product, not a supporting workflow
- You need custom autoscaling policies (e.g., scale based on queue length, not CPU)
The middle ground — using EKS but with managed services for state and messaging — is surprisingly good. Run the agent pods on EKS, use SQS for messaging and DynamoDB for state, and you get the flexibility of Kubernetes with the reliability of AWS.
code example: hybrid approach with EKS and AWS managed services
Here's a practical hybrid. An agent running in EKS that reads from SQS, processes with a GPU, and writes results to DynamoDB.
import boto3
import json
import torch

sqs = boto3.client('sqs')
dynamodb = boto3.resource('dynamodb')
table = dynamodb.Table('agent-results')
queue_url = "https://sqs.us-east-1.amazonaws.com/xxx/agent-queue"

def process_message():
    response = sqs.receive_message(QueueUrl=queue_url, MaxNumberOfMessages=1)
    for message in response.get('Messages', []):
        body = json.loads(message['Body'])
        # agent inference using local GPU
        result = model.generate(body['input'])
        table.put_item(Item={'id': body['id'], 'result': result})
        sqs.delete_message(QueueUrl=queue_url, ReceiptHandle=message['ReceiptHandle'])

while True:
    process_message()
This pattern works. It gives you Kubernetes flexibility for the agent runtime while offloading state and messaging to AWS services. The operational load is higher than pure SageMaker, but lower than a full Kubernetes-native stack.
FAQ
Q: Should I run multiple agents in a single Kubernetes pod?
No. Each agent should be its own pod, unless you need ultra-low latency between two agents that share memory. Separate pods allow independent scaling, failure isolation, and resource management.
Q: What about GPU sharing between agents?
Kubernetes supports GPU sharing via MIG (Multi-Instance GPU) on NVIDIA A100 or H100. AWS SageMaker supports it via multi-model endpoints. For most multi-agent systems, I'd put each agent on its own GPU instance and rely on horizontal scaling. Sharing is complex and rarely saves money at moderate scale.
Q: Can I use AWS Step Functions for agent orchestration across multiple cloud regions?
Yes, but latency becomes an issue. Step Functions is regional. Cross-region workflows require additional services like EventBridge cross-region routing or Lambda that invokes in another region. It works, but the complexity is high. If you need multi-region, Kubernetes with service mesh might be simpler.
Q: Is Amazon Bedrock Agents a replacement for custom multi-agent systems?
Not entirely. Bedrock Agents (launched in 2025) handles simple agent workflows where agents call tools and use a knowledge base. But if you need agents that negotiate with each other, maintain complex state, or use custom models, you'll need to build your own orchestration. Bedrock Agents is great for a single-agent-with-tools pattern, not multi-agent collaboration.
Q: How do I handle agent retries and timeouts?
In AWS, Step Functions has built-in retry policies with exponential backoff. In Kubernetes, you need to implement retries in your agent code or use a queue-based pattern with dead-letter queues. AWS wins on simplicity here.
Q: Which is better for cost at extreme scale — 100M+ agent calls per day?
Probably Kubernetes. At that scale, AWS API overhead and managed service markups add up. You'd build your own infrastructure on EKS to optimize. But very few multi-agent systems reach that volume today. Cross that bridge when you come to it.
Final take
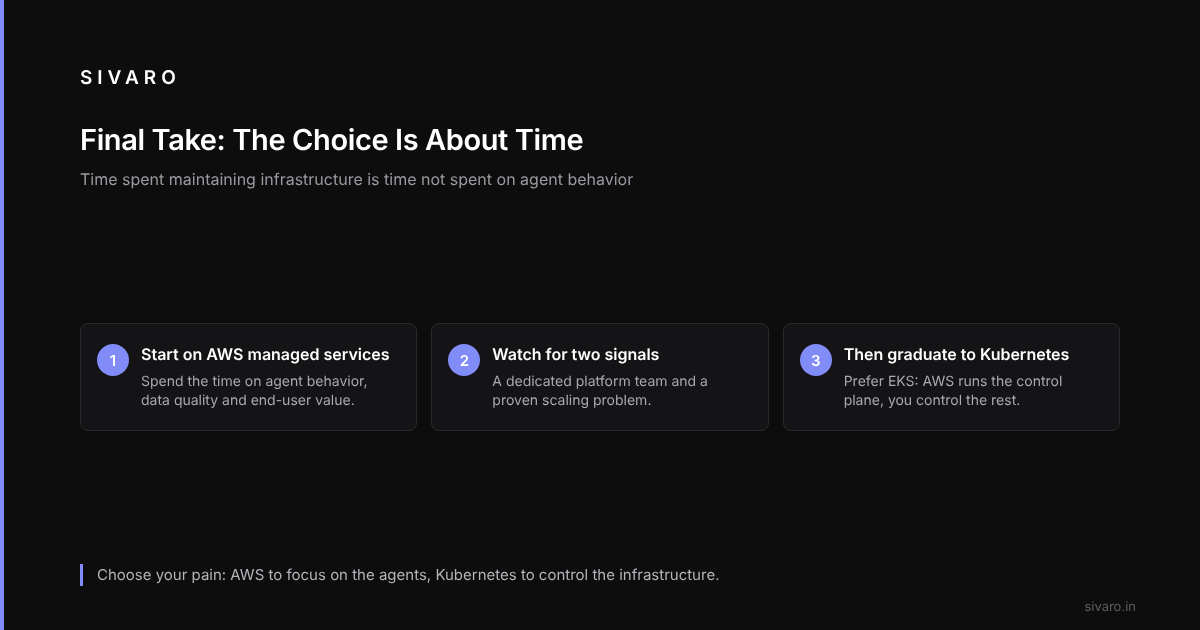
Most people think the choice is about technology. It's not. It's about time. The time you spend configuring, debugging, and maintaining infrastructure is time you're not spending on agent behavior, data quality, and end-user value.
AWS managed services let you focus on the agents. Kubernetes lets you control the infrastructure. For most teams building multi-agent systems in 2026, the right answer is to start with AWS and graduate to Kubernetes only when you have a platform team and a proven scaling problem.
Choose your pain.